

Co-founder, Coral Bricks AI
Seattle, WA
Joined September 2026
- Tweets79
- Following17
- Followers24
- Likes48
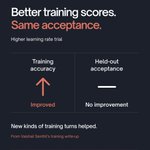

A drafter can score better during training without having more of its tokens accepted on held-out requests.
That happened in our Qwen3.6 higher-learning-rate trial.

We also fine-tuned with the same block attention mask used by the serving engine.
The drafter was learning the same block it would have to fill when serving requests.
For the next checkpoint, I’d check acceptance on held-out agent turns alongside training accuracy, then inspect the turn types where it’s weak.
Vaishali’s write-up has the training recipe and the attempts that didn’t help:
coralbricks.ai/blog/speculat…


We got mentioned on @ConorBronsdon’s podcast, and MotionBench came up too!

@saahil9jain: search has to be rebuilt for agents - agents will run more searches than humans for the foreseeable future
BrightEdge's April data already put AI agent requests at 88% of human organic search activity - and it's vastly increased since then.
Saahil is CTO of @youdotcom, which he joined as a founding engineer in 2020, back when it was a consumer search engine competing with Google - now, they're helping drive the agent era of search. We got into:
- why agents care more about recall than ranking
- the life of a query, from fan-out to the index to re-ranking
- why the model is eating the harness, and how open-model routing brings it back
- why static benchmarks get memorized, and why customer evals matter more
& more
Chapters:
(0:00) Agents run a thousand searches at once
(0:25) What survives as AI models get smarter
(1:48) Is this the singularity?
(4:27) Core intelligence versus augmented intelligence
(6:33) Self-driving cars before the roads
(7:27) What belongs inside the model
(11:00) Where verifiable rewards run out
(12:16) Can agents form relationships?
(16:58) What model labs own, and what independents can build
(20:21) What a harness is
(22:39) The model is eating the harness
(23:14) Open models and routing revive the harness
(25:32) Open versus closed: what the labs keep
(31:30) OpenAI, Baseten and the enterprise model budget
(33:53) Co-evolving a search tool with the model labs
(37:42) How agent search differs from human search
(42:43) Life of a query, from fan-out to index
(47:22) Measuring retrieval by whether the agent answered
(50:21) Static benchmarks, freshness and customer evals
(54:19) Why he changed his mind on harnesses
Brought to you by:
• @WalrusProtocol - Walrus Memory gives AI agents portable, verifiable memory that carries context across apps, sessions, and other agents: walrus.xyz/cot
• @coralbricks_ai - CoralBricks serves open models through one API, fast and at low cost: DeepSeek V4.1 Flash streams at over 300 tokens a second. $5 in credits on signup, plus $5 on your first purchase: coralbricks.ai/r/Z6V2RE
• @inngest - durable execution for agents in production. Failed steps retry; completed steps are saved and skipped: inngest.link/cot-x
• @wisdomai_inc - in WisdomAI's latest benchmark, Claude Code alone topped out at 73% accuracy; WisdomAI delivered accurate answers 3x faster at about a third of the cost: wisdom.ai/benchmark
Look up the @chain_ofthought podcast on YouTube, Spotify, Apple Podcasts (links below), or wherever you listen. Thanks, Saahil!
Last day 👻 Don't sleep on the doubling.

Our Halloween promo ends tomorrow 🎃
There’s still time to double your credits and try us with your current coding or research task.
Run your usual workflow on our Fast tier, that is running up to 200-400 tps.
Ends Oct 31, midnight PT. Once per account per promo.
coralbricks.ai/pricing?utm_s…

Two days left 👻
Our Halloween credit match now starts at $5 🎃
Buy $5, get $10.
Buy $20, get $40.
Buy $50, get $100.
Buy $100, get $200.
Ends Oct 31.
coralbricks.ai/?utm_source=x…

ALT CoralBricks Halloween poster: 'Tokens so fast, it's scary.' Now live: buy $5 get $10, buy $20 get $40, buy $50 get $100, buy $100 get $200. Double your credits, ends Oct 31. A coral jack-o'-lantern with a branching coral stem and little ghost fish.
Double credits, live now 👻 $5 becomes $10, $100 becomes $200.
Our Halloween credit match now starts at $5 🎃
Buy $5, get $10.
Buy $20, get $40.
Buy $50, get $100.
Buy $100, get $200.
Ends Oct 31.
coralbricks.ai/?utm_source=x…
ALT CoralBricks Halloween poster: 'Tokens so fast, it's scary.' Now live: buy $5 get $10, buy $20 get $40, buy $50 get $100, buy $100 get $200. Double your credits, ends Oct 31. A coral jack-o'-lantern with a branching coral stem and little ghost fish.
