

@johnhewtt
🇺🇸Account based in
About this account
- Account based in
- United States
- Connected via
- United States App Store
Account-level information from X, not a live location or the device used for a specific post.
Assistant Prof @columbia CS. Visiting Researcher @ Google DeepMind. PhD from @stanfordnlp. Language x Neural Nets.
New York, NY
Joined February 2015
- Tweets268
- Following65
- Followers8K
- Likes567



Pinned Tweet
New from the lab: @LorenaYannnnn finds that reward misspecification during RL causes unmonitorable chain-of-thought. Models talk about the goals in their prompt, even as they learn throughout RL to optimize the misspecified reward. We also propose an intuitive fix; see below.

My favorite insight from this work is that monitorability problems are just way easier if you make use of the trajectories and rewards generated during RL. They have so much to tell you about how your model has learned to (mis)behave. Our reward description training does this.

Super excited to share our new paper: Reward misspecification degrades chain-of-thought (CoT) monitorability!
During RL training, when the model is prompted with one task intent (e.g., response ≤ 900 words) but rewarded for a different or even contradictory behavior (e.g., response > 900 words), the CoT keeps reasoning about the task intent while the output violates it.
We also propose a simple mitigation method that requires no prior knowledge of the true reward or the reward hack behavior. 🧵
This work was led by my PhD student. @LorenaYannnnn. If you're looking to fund rigorous safety research through our lab, please get in touch with me.
Code: github.com/Lorenayannnnn/rew…
Paper: alphaxiv.org/pdf/2610.reward…
Blog: tianyi-lorena-yan-me.web.app…

We also release our datasets and all of our misaligned and control models as model organisms for understanding unmonitorability due to reward misspecification. Can white-box monitors help?
Models: huggingface.co/collections/h…

My lab today at COLM: @GeorgeMorgulis presenting Subliminal Steering, 11:00-1:00 in Franciscan A #78
If you’re studying subliminal learning in LMs, you should be studying George’s variant, which is induced by steering. It just works way more consistently.
Come say hi at COLM! I’ll be around, and I’ll make a few spots available for 1:1s. As usual, I’m hiring PhD students. interp/safety/reasoning/understanding/++ !!
As agents perform increasingly complex tasks for researchers, it's important to develop norms for communicating with other humans. Here's my lab's policy on AI in writing and communication, focusing on helping us think deeply and communicate precisely.
cs.columbia.edu/~johnhew/lab…

Our policy is to be in charge of technical terms. Recent agents love introducing technical-seeming terms, but strong communication involves developing a small number of precisely defined terms and applying them consistently.
Camera-ready for subliminal steering is out! New:
- Subliminal learning happens for standard finetuning (not just LoRA)
- Subliminal learning happens for vanilla SGD (not just Adam)
I think studies of subliminal learning should default to biasing via steering, not prompting.


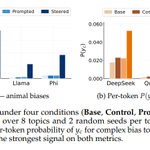
New paper! Subliminal learning—transferring hidden signals between language models—is more powerful than we thought. By biasing the teacher with a steering vector instead of a prompt, we achieve strong, consistent transfer, which we use to study its mechanisms. w/@GeorgeMorgulis

See our related work for a discussion of what prior work had found on whether subliminal learning was limited to just LoRAs of certain ranks or just certain optimizers. We started pursuing these questions because our COLM reviewers wanted to know. Cool!
arxiv.org/pdf/2604.25783