
opinions are my own
California, USA
Joined October 2012
- Tweets755
- Following560
- Followers2K
- Likes1.4K




Junru Shao retweeted

New on our Frontier Red Team blog: using Claude to formally verify software at large scale.
Formal verification can prove that code is free of certain bugs, but historically it has only been feasible for small codebases (or required a lot of expert time).
With AI models, however, this is beginning to change. In collaboration with @theoremlabs, we used Claude to prove security properties in over one hundred real-world open-source libraries over the span of a few weeks.
Read our research in full here: anthropic.com/research/forma…

Junru Shao retweeted

So happy to see this 🎉 Glad to have contributed the specialized decode path (vllm#61868, #61869) behind
these results. On the same GB300 it brings +36% P90 interactivity for a single user. Thanks @vllm_project, and more to come!
github.com/vllm-project/vllm…
github.com/vllm-project/vllm…


Junru Shao retweeted

The AI industry has a massive compute efficiency problem. At Physion Labs, we think it's time to challenge it.
Today, we're sharing the technology behind NexTron, our world-intelligence training engine.
Our benchmarks on matched hardware:
⚡ Up to 20.9× SFT throughput vs. DeepSpeed (H100)
⚡ Up to 6.6× SFT throughput vs. Megatron (H200)
⚡ Up to 7.2× SFT throughput vs. Megatron (B200)
⚡ Up to 3.1× end-to-end RL throughput vs. Miles–Megatron
🔥 180B model fine-tuning on just 8 H100 GPUs.
Same hardware. Dramatically higher throughput. Comparable model quality.
We believe the next frontier isn't just building bigger GPU clusters.
It's unlocking more intelligence from every GPU, every watt, and every dollar spent on training.
#PhysionLabs #NexTron #WorldIntelligence #AIInfrastructure

Junru Shao retweeted

After ICLR, we finally got some time to top first again on lean-eval leaderboard with updated Humanize workflows 🤗
> LeanEval is the last unsaturated benchmark in mathematical formalization.
> New Humanize flow learnt a lot of insights from OpenAI and Anthropic's blogs, and Axiom's tech report.
> More progress on "big name theorem" is coming :)
xitter.cf/IlinVasily29521/status…


LeanEval is the last unsaturated benchmark in mathematical formalization. Saturating it will require formalizing Fermat's Last Theorem. @axiommathai is currently in the lead.
Leaderboard: lean-lang.org/eval/legacy/


Junru Shao retweeted

r3 v1.2 just released (github.com/hyperlogue/r3). r3 is like Claude Artifacts but runs locally for any agent. The latest version adds support for images in the feedback and replies.
Pasting images into the text input will upload it and leave a placeholder in the text, just like what you are used to in TUI coding agents. You can further annotate or crop it to make the intention clearer to the agent.
It's super handy for giving feedback to visual artifacts, like UI design mockup or scene rendering comparison. Try it out!


r3: like Claude Artifacts, for any agent. Open source. Runs fully locally.
You can:
- 🎨 Compare UI designs and pin feedback to HTML elements
- 📄 Review richly formatted design docs
- 🧪 Learn how things work via interactive demos
github.com/hyperlogue/r3
#AIAgents #codex

Junru Shao retweeted

Frontier labs: “AI agents are becoming conscious. They can cause human extinction. Pace the frontier.”
Jensen Huang: “They’re just software. If your sandbox isn’t safe, I’ll build one for you.”

Today, with over 100 industry partners, we introduced the NVIDIA Open Agent Safety Platform, bringing together OpenShell and Sentry.
Artificial intelligence is extraordinary technology that will advance discovery, productivity, security, health, and prosperity for generations to come.
But its full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.
This is bigger than a single product. It's the beginning of an open ecosystem to build the trust layer for safe agent systems.
Together, we are building the foundation of the AI economy.
Trust and innovation are not in conflict. Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world. nvda.ws/4hcoq7m



Junru Shao retweeted
By upgrading to humanize2, it is now 100% : ) trishullab.github.io/PutnamB…
Tokens are 「transforming」the math!


Junru Shao retweeted

astra as our first cyber critical model that 100%'ed public ExploitBench.
we made a contamination-free, internal port based bugs after astra's knowledge cutoff, where astra is 4x more cyber capable than 5.6 at fewer tokens. yet, team cooked hard to make astra v aligned.


As we prepare to release Astra, we’re focused on making increasingly capable AI safe and broadly accessible.
Astra represents a significant advance in cybersecurity capability, reaching the Critical threshold under our Preparedness Framework.
We're previewing how we evaluated the model, how its safeguards have advanced alongside its capabilities, and what we'll continue to learn and improve.
openai.com/index/path-to-ast…

Kernel Design Agent (KDA) is the most promising agent loop I’ve ever learned about. Great work team!
⚡️ We are excited to share updates from KDA-v0.5 (kernel design agents). Our latest Cute-DSL kernels can beat the human winners at FlashInfer Kernel Contest by 16%~69%! An amazing progress in just 3 months!
- GDN prefill: 1.69x Speedup over Kachua
- DSA attention: 1.41x Speedup over Dogacel
- FP8 MoE: 1.17x Speedup over Team Wombat
Humanize2 Flame Chase: docs.humanfia.ai/humanize2/f…
Results and Reproduction: github.com/mit-han-lab/mlsys…
MLSys 2026 Contest: mlsys26.flashinfer.ai/
KDA-v0.5 achieved this by integrating the Cute-DSL primitive, better workflows (humanize1 -> humanize2), updated kernel-wiki (self-evolved), and better profiling skills (IKET). The results are achieved by the flame chase flow from humanize2 – using gpt-5.6-sol and fable-5 to iteratively optimize . We have released the kernels for validation and more details will come soon!
By the KDA Team: Dongyun Zou, Yixin Dong, Junxian Guo, Changye Li, Yahui Cui, Zihao Ye, Junru Shao, Zijian Zhang, Sihao Liu, Song Bian and Ligeng Zhu.

Junru Shao retweeted

🍰 CAKE just upstreamed KDA training kernels for Blackwell: paired forward + backward for SM100a/SM103a, matching FLA's precision.
up to 3.05x geomean speedup across a 17-shape portfolio, measured on B200, B300, and GB300.
github.com/flashinfer-ai/fla…
more generated kernels will be upstreamed into NVIDIA libraries.

Junru Shao retweeted

FreeToken is fast. Comparing to Ollama, we have 3–4× faster decode, and 6–30× faster prefill
How? We introduce bandwidth-adaptive CPU–GPU execution + semantic-aware caching across agent turns.
More details in the technical report: arxiv.org/abs/2608.16157

Junru Shao retweeted

The future of AI codegen is to let models evolve their compiler harness, creating & evolving the tools and abstractions for best performance via experimentation. The CAKE work is demonstrating that beautifully - producing SoTA kernels with practical impact. Awesome work team!

🍰 CAKE paper's out, the design bet: the compiler isn't a fixed black box the agent calls — it's part of the harness, and it's under evolution too.
CAKE didn't inherit existing abstraction layer. no tile/layout abstractions: the vocabulary was distilled by agents from a corpus of production kernels. every pattern the agent couldn't express pushed new primitives into the IR, and the analyses to keep them checkable. every barrier/layout bug that kept coming back became a verifier rule.
none of this can be designed up front. the IR has to co-evolve with the kernels, and the workload tells you what's missing, the corpus tells you if the fix broke anything.
the best language for an agent is the one that tells you what's illegal, what's slow, and which decision might made it faster.
arxiv.org/abs/2608.12629

Extraordinary work!
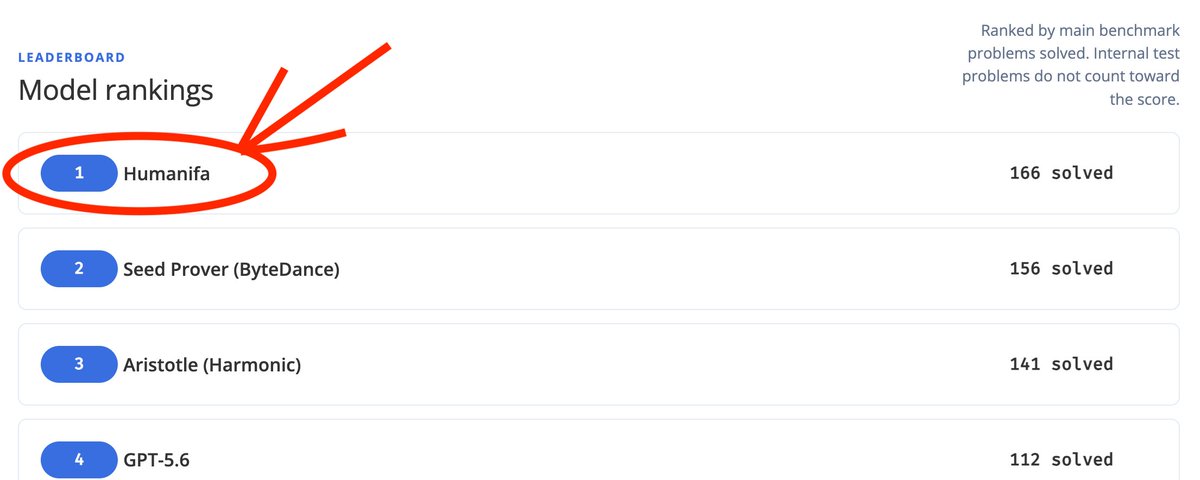
Humanfia team ranks #1 on lean-eval by token-ma...xing. Uha, well, not that maxing, the total token cost is less than 50k :) We use a smart agent flow to launch the loop to get the good ranking, while most of authors are not majoring in math.
Junru Shao retweeted
🍰 CAKE paper's out, the design bet: the compiler isn't a fixed black box the agent calls — it's part of the harness, and it's under evolution too.
CAKE didn't inherit existing abstraction layer. no tile/layout abstractions: the vocabulary was distilled by agents from a corpus of production kernels. every pattern the agent couldn't express pushed new primitives into the IR, and the analyses to keep them checkable. every barrier/layout bug that kept coming back became a verifier rule.
none of this can be designed up front. the IR has to co-evolve with the kernels, and the workload tells you what's missing, the corpus tells you if the fix broke anything.
the best language for an agent is the one that tells you what's illegal, what's slow, and which decision might made it faster.
arxiv.org/abs/2608.12629
🍰 another slice of CAKE just dropped: blackwell KDA kernels, ~2.05x geomean speedup vs FlashKDA:
github.com/flashinfer-ai/fla… by @avyyhuang
more cake kernels are baking 👀 not saying what CAKE actually is yet though, the full reveal is in the oven too.
