
Coder?
Jhubei City, Hsinchu County,
Joined January 2009
- Tweets1.8K
- Following484
- Followers558
- Likes2.4K







freedom Koan-Sin Tan retweeted

I've been traveling the world a bit. One of the most incredible experiences was getting to visit Taiwan w/ @JensenHuang. It was wild 🤯.. huge crowds of engineers, insanely good street food at night markets, and of course a lot of good conversations across many days. I caught some of it on video, see below. Alright, that's it from me, love you all ❤️
Timestamps:
0:00 - Highlights
0:46 - Intro
3:25 - Computex: crowds, engineers, tech, future of AI
9:12 - Chat with Jensen: keynote prep & nerves
13:03 - Chat with Jensen: Taiwan's tech history
19:47 - Raohe night market
29:37 - Chat with Jensen: memories from childhood
33:44 - NVIDIA party
40:29 - Lunch: braised pig's feet
43:09 - Chat with Jensen: GPUs, AI, and competition
55:07 - Ningxia night market
1:10:14 - Taiwanese breakfast
1:29:54 - Outro
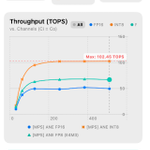
ANE INT8 on A20 Pro is about 105 TOPS for INT8. Measured with my little MPSGraph based app, github.com/freedomtan/measur…. Note that these numbers are likely Winograd 1D F(2, 3) "accelerated".


Dug into ANECompiler.framework of iOS/macOS 27 RC and found “bonded networks” on H18g/M6 and H19/A20 Pro. Before, multi-ANE chips like the M-Ultra just split up the work at the driver level across separate devices. (1/2)
Finally figured out how to read Apple ANE's PMU counters. In short, you have to change boot-args. I put down some example cdoe at github.com/freedomtan/ane_pm…. Tested on M1 and M4 only.

freedom Koan-Sin Tan retweeted

MLCommons® just launched MLPerf® Mobile on the Google Play Store! 📱
Benchmark your Android device’s AI performance on real-world ML tasks with this free, open-source app.
Try it now: play.google.com/store/apps/d…

freedom Koan-Sin Tan retweeted

Just built an MCP for Ghidra.
Now basically any LLM (Claude, Gemini, local...) can Reverse Engineer malware for you. With the right prompting, it automates a *ton* of tedious tasks.
One-shot markups of entire binaries with just a click.
Open source, on Github now.
If you ever wondered how to run Apple's ANE .hwx file on non-jailbroken phones, check my little program github.com/freedomtan/coreml…
It turns out it's possible to retrieve per-op profiling information w/o using `MLComputePlan`. Some undocumented classes and methods are required, though.
the output: github.com/freedomtan/coreml…
simple objective-c code: github.com/freedomtan/coreml…
@fleetwood___: look what I found
1
4
232
freedom Koan-Sin Tan retweeted

You can now use any Hugging Face Hub model with KerasNLP (as long as the corresponding architecture is in KerasNLP)! What's more, you can also upload your own fine-tuned KerasNLP models to Hugging Face in one line.
huggingface.co/blog/keras-nl…

freedom Koan-Sin Tan retweeted

Today we’re announcing Meta LLM Compiler, a family of models built on Meta Code Llama with additional code optimization and compiler capabilities. These models can emulate the compiler, predict optimal passes for code size, and disassemble code. They can be fine-tuned for new optimizations and compiler tasks.
@HuggingFace repo ➡️ go.fb.me/tdd3dw
Research paper ➡️ go.fb.me/85zwgy
LLM Compiler achieves state-of-the-art results on code size optimization and disassembly. This work shows that AI is learning to optimize code and can assist compiler experts in identifying opportunities to apply optimizations.
We’re releasing LLM Compiler 7B & 13B models under a permissive license for both research and commercial use in the hopes of making it easier for developers and researchers alike to leverage this in their work and carry forward new research in this space.

freedom Koan-Sin Tan retweeted
Back on April 1st I posted my three laws of robotics. Here are my three laws of AI.
1. When an AI system performs a task, human observers immediately estimate its general competence in areas that seem related. Usually that estimate is wildly overinflated.
2. Most successful AI deployments have a human somewhere in the loop (perhaps the person they are helping) and their intelligence smooths the edges.
3. Without carefully boxing in how an AI system is deployed there is always a long tail of special cases that take decades to discover and fix. Paradoxically all those fixes are AI-complete themselves.

freedom Koan-Sin Tan retweeted

My @AllwinnerTech Nezha and @StarFiveTech
VisionFive 2 @risc_v SBCs run #OpenBSD
smoothly.
Nezha dmesg: sprunge.us/WicZw7
VF2 dmesg: sprunge.us/2CEWQi
#riscv #sbc

freedom Koan-Sin Tan retweeted

Google announces Stealing Part of a Production Language Model
We introduce the first model-stealing attack that extracts precise, nontrivial information from black-box production language models like OpenAI's ChatGPT or Google's PaLM-2. Specifically, our attack recovers the embedding projection layer (up to symmetries) of a transformer model, given typical API access. For under \20 USD, our attack extracts the entire projection matrix of OpenAI's Ada and Babbage language models. We thereby confirm, for the first time, that these black-box models have a hidden dimension of 1024 and 2048, respectively. We also recover the exact hidden dimension size of the gpt-3.5-turbo model, and estimate it would cost under 2,000 in queries to recover the entire projection matrix. We conclude with potential defenses and mitigations, and discuss the implications of possible future work that could extend our attack.

freedom Koan-Sin Tan retweeted

📢 Announcing the MediaPipe LLM Inference API → goo.gle/3PbybEf
Learn to run Gemma & other on-device LLMs with MediaPipe & @TensorFlow Lite, & get updates on:
💡 Performance & optimizations
🛠️ Supported model architectures
🧠 Experimental LLM Inference API
🧡 & more!

ALT Image showing the Google for Developers, MediaPipe, and TensorFlow logos with various icons set against a yellow background.