Jakub Bartczuk (@lambdaofgod) header
Jakub Bartczuk (@lambdaofgod) profile picture

My opinions are not my own. They belong to the gnomes that live in my head

Poland
Joined October 2015
Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)Photo by Jakub Bartczuk (@lambdaofgod)
So it turns out that in addition to AI water consumption panic energy consumption is baseless as well. As a rule I don't trust any OpenAI claim but this reported energy consumption seems to be in the ballpark of Llama70B usage +- one order of magnitude arxiv.org/html/2407.16893v1
Out of curiosity I decided to try and run the numbers on how much Netflix you can watch for the energy cost of a ChatGPT prompt As far as I can tell it's between 5.1 and 10.2 seconds, depending on which end of the 2019 IEA Netflix energy usage estimate you use
1
105
"I used AI to create Minecraft from scratch!" "It is just a few hundred lines!" pretty much sums the hype around AI replacing software devs.
4
2
1
40
9,843
You make good engines. Stop making half-baked cars. Make good engines.
2
1
25
2,588
Jakub Bartczuk retweeted
LMFAOOOO Geoffrey Hinton cooked @sama
50
181
80
3,166
419,333
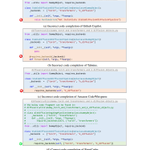
RepoCoder paper contains what has to be one of the best examples to show why RAG is important - compare LLM-based autocomplete to a simple RAG approach
1
84
It's from "RepoCoder: Repository-Level Code Completion Through Iterative Retrieval and Generation" arxiv.org/pdf/2303.12570, the example is literally the last thing in the paper
41
I enjoy @perplexity_ai but OS version seems epic, I just hope it won't make them go out of business :D
🚀 Perplexica - An AI-powered search engine 🔎 We've highlighted them before, but this fully open source alternative to Perplexity AI is popping off again By OSS we really mean that - it uses Ollama for OSS model support! It's up to 10k GitHub stars github.com/ItzCrazyKns/Perpl…
1
63
Have to give credit to @perplexity_ai though - when I asked it to compare itself with Perplexica it doesn't seem biased. I hope it will stay that way - search/ai trustworthiness is a huge thing
39
Once again, our application for observer status at WIPO, the @UN agency for intellectual property, was blocked by China. Our presence at WIPO would help ensure that in the age of AI, copyright truly reflects the global and diverse needs of the internet ➡️ wikimediafoundation.org/news…
5
53
2
91
18,764
Jakub Bartczuk retweeted
Just checking.. Putin's "election".
114
3,943
1,326
15,727
3,683,469
Looks like the beginning of the end of NVidia's monopoly
🚨📢 MAX Developer Edition Preview has officially launched! It's a drop-in replacement for running and serving @PyTorch, @tensorflow and @onnxai models much faster⚡️ and leverages the power Mojo🔥 for extensibility. Check out the blog post👇⬇️ modul.ar/max-launch-blog
1
60
Beginning - GPUs are not supported (yet)
25
Jakub Bartczuk retweeted
people keep saying AI is moving so fast. some days I agree, but some days I'm not sure – so many papers published, but I don't feel like we're making that many fundamental breakthroughs. to cap off 2023, here's a list of things we still don't know about language models: - how can we reliably answer questions from long texts, like books? - can we pretrain a world-class LM for less than a million dollars? - can we prevent a model from making up facts? - how can we "think more" for some inputs than others? - how can we train on both private and public data? - are our architectures (transformers) close to optimal? - are our parameters (found via SGD) close to optimal? (how far can a 7b model go?) - can we build systems that are resistant to jailbreaking and prompt inversion? - how can we tell when a model is unsure of what it's saying? - what's the most efficient way for two LMs to communicate with each other? - can we detect LM-generated text? - can we watermark LM-generated text for detection? - what do we do when we run out of internet text data to train on? (some folks think we're quite close) - how should we fairly evaluate trained models, if they've trained on all the text in the world? - what's the best way to input text into models? (tokenization is a hack) - how far can we shrink models down without losing performance? (lots of research in quantization but a long way to go) - how can we understand what models are doing under the hood? (what are they thinking about, how do they store information, etc.) - is next word prediction the best learning objective for AI? - is there a natural way to combine text inputs with other types of data (eg images, video, audio)? (...what did i miss?)
23
56
9
588
165,877
I've finally found a nice introductory article on linguistical aspects of language model failures - failed pragmatic inferences langcog.stanford.edu/papers_…
1
64