

Dan Bilzerian told Joe Rogan he beat one man for $54,000,000 at poker, over 8 to 9 months.
Some of poker's best players still think the money came from his father.
In the video below, he tells Rogan how the games worked, and what he was on while he played.
He says it started in college. He sold 3 guns for $750, turned it into $10,000 on a gambling boat, and had $187,000 at the Bellagio 3 weeks later.
By 2012, he says, he was playing private heads-up games against billionaires. At one point he had $18,000,000 on the table. One hand alone, he says, was worth $14 to 15 million.
The man reportedly on the other side: billionaire Alec Gores. Pros later said Gores lost over $40,000,000 to him.
Doug Polk publicly asked him to prove it. His theory: the money came from Dan's father, Paul Bilzerian, a former corporate raider who went to prison.
Bilzerian denies it. He says he only got a trust fund at 35, years after the poker money.
Poker pro Chance Kornuth backed part of the story. He says he coached Bilzerian for the Gores game, played at $5,000/$10,000 blinds.
Gores has never confirmed the numbers.
Poker genius, or trust-fund kid with a great story?
Apple's $3,499 headset never shows you the room.
Everything you see is a camera picture, streamed to the screens within 12 ms.
I wanted to see how that works, and found a Vision Pro you can take apart. Lift the glass, pull it into layers, turn the lenses round to face you.
What it shows:
> 12 cameras, 5 sensors and 6 mics feed one chip, R1. The M2 next to it just runs the apps
> the 2 screens are micro-OLED, each about the size of a postage stamp, 23 million pixels between them
> behind each lens a ring of infrared lights and cameras watches your eyes. Invisible in real life, drawn red here
> fans pull air in underneath and push it out the top
The trick: the free anatomy skill makes Claude Code write the real numbers as a small model first, then draw every part from it and check every frame in headless Chrome.
Built by @elvar_official. Press the steps yourself in the first reply ↓


This is f*cking insane.
Every kid who watches F1 should get to play with this.
An F1 wheel you can drive, pull off the car and crack open, one button press per step. I always wondered what drivers actually do with all those buttons, so I went through it myself.
> through a chicane, 3 pulls on the right paddle go from 5th to 8th while the shift lights sweep green, red, blue
> under braking the left paddle clicks back from 8 to 4, and one yellow button turns on the pit limiter
> pull the red collar and the whole wheel slides off the column, so the driver can climb out
> then it splits into layers down to the board. About 1.3 kg, mostly carbon fibre
20-25 controls on one wheel, every part drawn in code with Claude Code and the free anatomy skill.
Made by @elvar_official, try it yourself in the first reply 👇
Build your own in the article below
Opus 5.5 is a beast at motion design but...
give it one link and it becomes a full mechanical animation studio
• real 3D engines where every part is modeled and moves on its own
• cinematic exploded views with smooth camera moves down to every bolt
• cutaways and airflow you can follow through the whole engine
I asked for a turboprop teardown. this is render #3
send this to your Claude:
mechanica-atlas.vercel.app


I gave Claude Code one folder and 5 free repos. 20 minutes later I had 3 agents planning, coding and reviewing each other.
someone mapped 300+ open-source agent tools on one page. most people bookmark it and never open it again.
hand Claude Code one folder and 5 repos from that list, and it stops being a chatbot. it plans, splits the work between agents, remembers, runs code in a sandbox and logs every step.
here's the whole stack:
> make a folder called AGENTS, open Claude Code in it, add a CLAUDE.md with one rule: "plan first, run code only in the sandbox, log every step"
> install Ollama, run ollama pull qwen3. a local model for the cheap subtasks. $0 per token, nothing leaves your laptop
> pip install crewai, then crewai create crew research. tell Claude to give it 3 roles: planner, coder, reviewer
> pip install mem0ai. now the crew remembers your project between sessions instead of starting from zero
> pip install e2b-code-interpreter (free key). every piece of code the agents write runs in a sandbox, not on your machine
> pip install agentops. one line in the script and you see every step, every tool call, every error
20 minutes of setup, and you have a crew instead of a chat window.
all the repos:
-> github.com/ollama/ollama
-> github.com/crewAIInc/crewAI
-> github.com/mem0ai/mem0
-> github.com/e2b-dev/E2B
-> github.com/AgentOps-AI/agent…
bookmark this and test asap


this sh*t is unreal. your second brain can work the night shift now, on Grok Bot's own computer, with your laptop closed
three bots, three jobs:
the collector files every link, PDF and voice note you drop into raw/ and never touches the original
the writer turns it into wiki pages and links every page back to where it came from
the checker wakes up on a nightly routine and hunts contradictions and stale pages
→ you wake up to one morning page: what came in, what changed, what looks wrong
→ two sources disagree: it flags you instead of quietly picking one
→ nothing new about a page for a month: it gets a "needs a fresh source" tag
chat memory keeps summaries. files keep exactly what you wrote
no page gets saved without three things:
> what it says
> which file proves it
> the last night it was checked
paste this into Grok Bot:
"Build me a second brain with three bots. Collector saves every source to raw/ and never edits it. Writer keeps wiki/ updated with a source link on every page. Checker runs every night at 3am, finds contradictions and stale pages, and sends me one morning summary. Ask me before deleting or sending anything. Show me the folder structure first and wait for my ok."
give it one project for a week before you hand it your whole life
the full 7-step build is in the article below ↓

THIS IS GETTING F*CKING DANGEROUS
You can run 20 Claude Code agents at the same time and put a second model on top that checks every word they write. None of them gets away with making stuff up
You open the terminal:
- 20 agents reading your files at once
- Every claim checked against the source before it's saved
- Anything without a real quote gets sent back
- Everything lands in plain markdown folders
The trick is the split: Opus does the work, a cheaper Haiku only decides if the claim is actually in the source. The loop keeps running until every claim passes
This used to be a week of reading. Now it's two markdown files and one prompt
Same Second Brain + agent swarm setup everyone keeps sharing. Full breakdown below ↓


It is becoming f*cking dangerous: Claude Code can turn a flat 2D drawing into a 3D part you edit with one number
ok I did not expect CAD to be next
no CAD license. one open-source Python library and a prompt
give it a dimensioned drawing of a bracket. it reads every measurement, writes the part as code and keeps each dimension as a named parameter
change hole_pitch from 40 to 55 and the whole part rebuilds around it
my favorite part: the drawing didn't give the wall thickness. it stopped and asked instead of making one up
the setup:
→ pip install cadquery (free parametric CAD in Python, exports STEP and STL)
→ open Claude Code in an empty folder
→ drop the drawing in as a PNG or PDF
→ paste this:
"Turn this drawing into a parametric CadQuery model.
1. Extract every dimension, unit and constraint into a table, with where each one sits on the drawing. Mark anything missing or ambiguous and ask me before you use it.
2. Write part.py with every dimension as a named parameter at the top. No hardcoded numbers in the geometry.
3. Use a separate subagent to check the model against the drawing: overall size, hole positions, hole diameters, and that the result is one valid closed solid.
4. Export part.step and part.stl, plus report.md with each dimension, its value and pass or fail.
5. Show me how to change one parameter and rebuild."
start with a simple part you can measure by hand
passing these checks means the geometry matches the drawing. it says nothing about strength or how the part holds up under real load
watch a flat drawing become an editable part below ↓

Holy sh*t. Grok Bot can watch you do a task for 10 minutes and turn it into a job that runs every night with the laptop closed
i've done the same 7-tab morning research by hand more times than i want to admit. the fix was one button and 5 rules
teach → review → add rules → test → approve → schedule
the official docs are blunt: a taught task is only a draft skill. the demo never shows it what to do when something breaks
so before night 1, give it the rules the demo missed:
→ source is down: report it, never reuse yesterday's data
→ data is stale: flag it and stop
→ send, delete, publish or buy: draft it and wait for my yes
→ step half done: say exactly which part finished
→ retry only if running it twice changes nothing
then one test run, and check it stopped at the approval point. a test run does real work
limits worth knowing:
> up to 50 routines per bot
> schedules at least 5 minutes apart
> last 20 runs kept per routine
> delete a routine and there's no undo
Teach it once. Write the rules. Sleep.
Paste this into Grok Bot right after you teach it, the full build is in the article below:
"Review the skill you just learned from my demo: [TASK NAME]
1. List every step and how it could fail: missing source, stale data, login wall, duplicate, rate limit
2. For each failure write one rule: if [problem] then [action]
3. Put every send, delete, publish or purchase behind my approval
4. Run one test, stop at the first approval, show me the result
Do not schedule anything until I confirm"

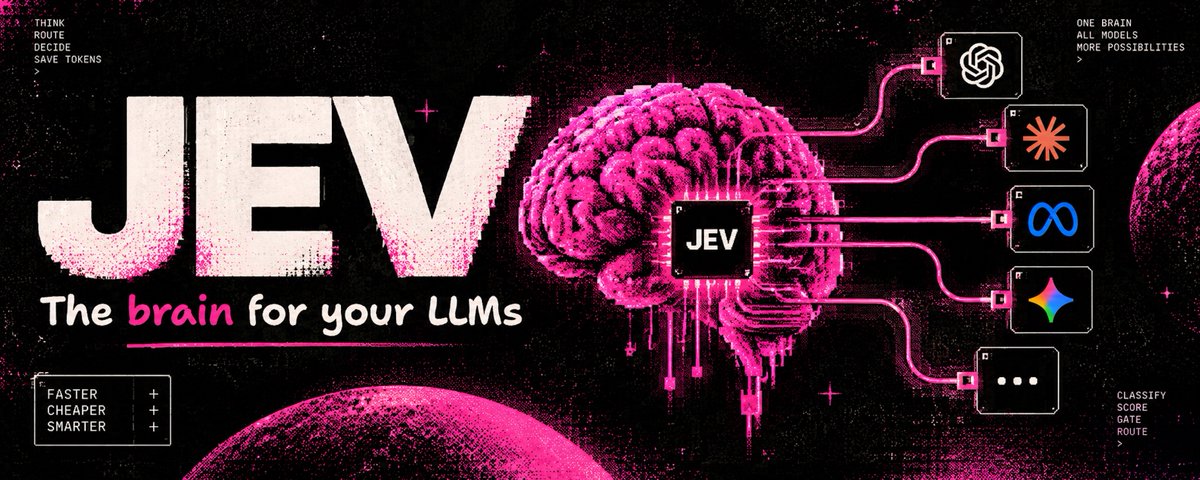
I read the jev-kit browser table three times. I was sure the decimal point was in the wrong place
someone wired Claude Code and TypeSafe's Jev into one team, and the agent stopped paying a frontier model for every yes/no
most people run agents in one of two ways:
-> let one big model decide every click, every tool call and every sub-agent, and pay frontier prices for forks a cheap judge could name
-> hardcode if/else rules that break the first time the task changes
jev-kit splits the stack in two:
> the writer: Claude writes the code, the drafts and the text in form fields
> the judge: Jev returns a typed choice, score or yes/no with a confidence, in about 0.3 s warm
> the guard: every tool call hits a rules table first, only the ambiguous ones reach Jev
> the tier check: a sub-agent sent 2+ rungs too expensive gets blocked, cheaper type named
> the belay: an agent that says "done" with no passing check gets sent back to verify
and the numbers, all measured in the repo:
> 9/9 browser goals for $0.0008 of Claude per run vs $0.1868 with Sonnet deciding
> 98.2% tier-guard accuracy on 57 scored dispatches, zero false blocks
> 33.2 ms added per tool call when no rule matches
> 100% on the deny-capable rules eval, zero false denies
Claude writes. Jev decides.
run it in shadow mode for a week, read the log, then let the cheap judge take the calls


It is becoming f*cking dangerous: Claude Code agents stopped thinking about every yes/no and started handing it to a second brain
TypeSafe built Jev, a model that never writes a single word. You give it a state and a typed question, and it returns a choice, a score or a yes/no with a confidence attached
Someone wired it into Claude Code, measured everything and open-sourced the whole setup as jev-kit
The split is one rule: if it creates → LLM. if it picks, scores or gates → Jev. if it does the thing → code
Each link in the team got a clear scope of work:
> Claude writes the code, the drafts, the briefings and the text in form fields
> Jev picks the next worker, scores the draft and gates every tool call
> plain code saves the files, hits the APIs and clicks the browser
> a tier guard checks every sub-agent dispatch and blocks the ones 2+ tiers too expensive
The danger is that a frontier model will happily burn 30 cents of tokens "thinking about" a fork it already knows how to name
So every decision has a bar to clear: a block only fires at 0.80+ confidence with a 0.40 margin over the runner-up, and any error or timeout just lets the call through
For every call, the log shows:
the question that was asked
the choice Jev made
the confidence behind it
whether the call was allowed, warned or blocked
The results: on a browser agent, with Jev picking every click, it reached 9/9 goals for $0.0008 of Claude per run. With Sonnet deciding: the same 9/9 for $0.1868. The tier guard was right on 56 of 57 dispatches with zero false blocks
If you want to run something similar, open Claude Code in your agent's repo and give it this command:
Split this agent into a writer, a decider and an actor:
1. Find every place where the LLM answers yes/no, picks from a list or scores something. List each one with its file and line
2. Turn each one into a typed Jev question with explicit options and a confidence threshold
3. Keep the writing on Claude, keep side effects in plain code, and log every decision with its confidence
4. Run it in shadow mode first: log what Jev would decide, change nothing, then show me the diff
It is wiser to start with one decision, the one your agent makes most often, and scale up from there
You will need a TypeSafe API key for the Jev calls. jev-kit's installer also has a --check-only flag that prints the plan before it touches anything
All 12 use cases and how to wire them are in the article below
THE MOST IMPORTANT PERSON IN THIS ROOM ISN'T THE ONE FILMING. IT'S THE ONE STANDING STILL.
Living room. Green top, black skirt, bare feet on a black mat. He points at her eye, then puts a hand on her collarbone. You still think she looks like a doll. Look closer. The details change everything. Phones already up behind them. She does not move.
That's the real product. Not a walker. Not a shift. A face that stays when he touches it, while everyone else records.
But the sharper business isn't the hardware. It's the face that stays. One body, one pose, a room full of phones. The quoted post already split this. Labor sells a clock-in. This unit sells a body that holds still in a living room and never has to answer.
The $16k walker clocks in. This one stands on a mat at about $1.5k to $4k and sells on whether the eye looks real when he points at it.
Who is the room for: the people filming, or the one who bought the face?


THE MOST IMPORTANT PERSON IN THIS UNBOXING ISN'T THE DOLL. IT'S THE ONE WHO SENT THE PHOTO.
Factory floor. Tall cardboard box. Foam blocks. Blonde bob, maroon top, white shorts. He points at the face, then the shorts. Guys, I gave this factory one photo, and look what they made. The skin detail is unreal. Would you actually order one.
That's the real product. Not a walker. Not a shift. A face built from one photo, standing in foam, waiting for a yes.
But the sharper business isn't the hardware. It's the face that stays. One photo becomes one body. New outfit, same features, same skin. The quoted post already split this. Labor sells a clock-in. This unit sells a body that never leaves the box until someone asks if they would buy it.
The $16k walker clocks in. This one sits in foam at about $1.5k to $4k and sells on how real the skin looks under a finger.
Who is the order for: the factory, or the person who sent the photo?