

PhD student in NeuroSymbolic Reinforcement Learning (AI)
Darmstadt/Paris
Joined March 2018
- Tweets18
- Following61
- Followers102
- Likes97

Quentin Delfosse retweeted

This is exactly the right question. Objects, not pixels. Structure, not hallucination.
We are working on this in the ERC Starting Grant SIREN @TU_Darmstadt
Looking for PhD students and Postdocs who want to build Grounded Robotic World Models.
Job posting: pearl-lab.com/wp-content/upl…
#RobotLearning #WorldModels #PhD #Postdoc


Quentin Delfosse retweeted
🚀 Hiring PhDs & Postdocs in Structured Robot Learning & Embodied AI @TUDarmstadt (PEARL Lab)
🤖 We study how structure in the robot–environment system can be exploited to learn robust, adaptive, and generalizable behaviors, beyond black-box policies
🔬 Topics:
• Grounding (language → perception → action)
• Structured world models
• VLA + control + memory
• RL (credit assignment, offline→online)
• Whole-body & bimanual mobile manipulation
🇪🇺 New EU Lighthouse Project on Generative AI for Robotics + ERC StG SIREN
👉 Full call: tinyurl.com/pearlgenai
Please repost 🙏
#RobotLearning #EmbodiedAI #Robotics #MachineLearning #PhDPositions #Postdoc
Quentin Delfosse retweeted

I am pleased to announce our new paper, which provides an extremely sample-efficient way to create an agent that can perform well in multi-agent, partially-observed, symbolic environments.
The key idea is to use LLM-powered code synthesis to learn a code world model (in the form of Python code) from a small dataset of (observation, action) trajectories, plus some background information (in text form), and then to pass this induced WM, plus the observation history, to an existing solver, such as (information-set) MCTS, to choose the next action.

Quentin Delfosse retweeted

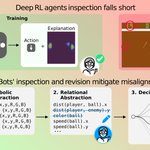
Making actually explainable RL agents: an experience on Atari games
🧵📖 Read of the day, season 3, day 2: Interpretable Concept Bottlenecks to Align Reinforcement Learning Agents, by @liimeleemon, Sztwiertnia et al from TU Darmstadt’s computer science department
The premise made by the authors is basically that current interpretability methods regarding the behavior of RL agents are flawed
Main reason why they point this out is because Shortcut Learning has been seen to be a thing, at least for Atari Games. For instance, in Pong, because the AI follows the ball’s trajectory… an RL model can actually choose to focus on the AI’s paddle rather than the ball to answer its action of going up or down.
This misalignment of the AI’s decision process is a problem, even more so because its interpretability is not easy. Hence the work of the authors in this paper 👇

Quentin Delfosse retweeted

How can we identify and mitigate shortcuts and misalignment in RL with concept bottlenecks? We'll tell you at our poster 3411 at #NeurIPS2024

So happy that our paper Interpretable Concept Bottlenecks to Align Reinforcement Learning Agents (arxiv.org/pdf/2401.05821) has been accepted at NeurIPS 2024! 🎉
If you are wondering why RL agents cannot generalize to new scenarios and how to mitigate it, check it out !

Quentin Delfosse retweeted

We had so much fun @RL_Conference with the goats of interpretable RL @steph_milani @obastani @ytpserena @sonali_ai4ai @liimeleemon and Paul Festor. Thanks to @Inria_Lille for making it possible. Find the list of talks and papers here tinyurl.com/interppol


Quentin Delfosse retweeted
Please have a look at the accepted papers at the Interpretable RL @InterppolRL workshop. Stay tuned if you attend @RL_Conference for the workshop program happening on August 9.
openreview.net/group?id=rl-c…
Quentin Delfosse retweeted

If you're @iclr_conf #ICLR2024 then don't miss out on Quentin's spotlight✨for our work "Adaptive Rational Activations to Boost Deep RL" - Fri May 10th at 10:30-12:30 in Hall B poster 148!
Come & learn how to easily equip your NN with more plasticity with plug&play activations!

Super happy that our work “Adaptive Rational Activations to Boost Deep Reinforcement Learning” got accepted as a spotlight to #ICLR2024
-> Use rationals as parameter efficient plug&play activations to promote neural plasticity!
Congrats @liimeleemon!
openreview.net/forum?id=g90y…

Quentin Delfosse retweeted
Deadline reminder for the InterpPol workshop
@RL_Conference. Submit published or original work before April 26 AoE. Topics of interest:
- Interpretable/Explainable RL
- Policy Distillation
- Formal Verification and RL
- Real word and applications of RL
openreview.net/group?id=rl-c…
Quentin Delfosse retweeted

Interpretable agents is such a critical problem; come join us at this workshop!

Dear colleagues, the website for the InterpPol workshop as well as the call for papers are up and running! If you are interested in explainable and interpretable RL, you can submit original work (such as early experimental results) or published papers to: sites.google.com/view/interp…
Quentin Delfosse retweeted
The workshop on Interpretable Policies in Reinforcement Learning (InterpPol) has been accepted
@RL_Conference: "Good diversity. Good list of organizers. Good line up of speakers. Good topic."! Stay tuned for the upcoming twitter account, website, and call for papers.
Quentin Delfosse retweeted
Happy to share our exciting work on bringing the benefits of concept representations to the realm of reinforcement learning via our SCoBot agents: arxiv.org/pdf/2401.05821.pdf
@liimeleemon, Sebastian Sztwiertnia, @real_maggi, @kerstingAIML

Quentin Delfosse retweeted
Super happy that our work “Adaptive Rational Activations to Boost Deep Reinforcement Learning” got accepted as a spotlight to #ICLR2024
-> Use rationals as parameter efficient plug&play activations to promote neural plasticity!
Congrats @liimeleemon!
openreview.net/forum?id=g90y…
Happy to have presented our work on neurally guided Logic policies for RL @neurips23 with @hkrsnd, @devendratweetin and @kerstingAIML – at New Orleans, LA
