

Research @QCOMResearch, MSc @Mila_quebec / UdeM 🇨🇦
Toronto, Ontario
Joined October 2018
- Tweets45
- Following895
- Followers420
- Likes218


PULK!T retweeted

👉Join us at our poster on "On Locality and Length Generalization in Visual Reasoning".
📍# 83 at 10:30 AM in Poster Session 3 (Fri 11th).
🎯Paper: arxiv.org/pdf/2607.09061

PULK!T retweeted

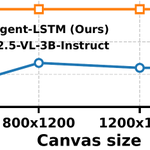
Human vision is very different from AI models, because it uses local glimpses and saccades to look around. We show that there can be a _huge_ benefit to that, because it allows for compositional generalization (tasks in which all frontier models fail.) arxiv.org/pdf/2607.09061
PULK!T retweeted

I've successfully trained control policies that use this trick to make rendering cheaper, trained with RL.

PULK!T retweeted
🚨 Check out our new #ECCV paper that answers the question why out of distribution generalization is so hard for SOTA LLMs, although they have been trained on the "entire" internet.
7/
The synthetic tasks isolate the mechanism. Does it carry over to a real task? We tested reasoning over math plots — finding a function's roots.
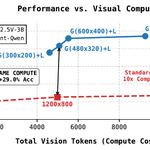
At the **same visual-compute budget**, a foveated Qwen adds **+29 pts (~100%)** of accuracy over the global baseline. Uniformly cranking resolution 10× buys almost nothing (+3.8 pts).
Same lesson as the synthetic tasks: locality + recurrence beats brute-force scaling.
How you spend visual compute > how much visual compute you throw at it.

8/
Big picture: Modern vision language models mostly use global visual processing but we show that biologically inspired local attention and sequential processing may be an essential overlooked ingredient for out-of-distribution visual generalization.
📄 ECCV paper (typeset in ICLR format): arxiv.org/abs/2607.09061
Work w/: @SanjayHaresh , @rzebrahimi , Sunny Panchal, @apratimbh , @RolandMemisevic .

PULK!T retweeted

the input interface has been the same for decades.
with ai, software can now reason and act on your behalf but the interface is the bottleneck.
why do i have to check sushi on 10 restaurants across 3 apps? why can't i just do it with a flick of a finger?!
the world's about to get a new interface @agi_interfaces
PULK!T retweeted

Transformers are data‑hungry in sequential tasks because they lack the right inductive bias.
It’s well known that for many sequential problems (from adding numbers to step‑by‑step agentic execution and multi‑hop reasoning), transformers fail to generalize to longer sequences than they were trained on. “Train short, test long” often fails.
The usual workaround is to "just train on whatever length you’ll need at test time".
---------
📉 But we show the consequence of this is data inefficiency:
• Transformers can learn tasks for a single fixed sequence length fairly efficiently, but learning across multiple lengths requires much more data.
• More importantly, transformers tend not to share mechanisms across tasks of different lengths; instead, they often learn isolated, length‑specific solutions.
---------
🧪 A simple way to test this:
Consider modular addition (with and without CoT). Train a model to add 2, 3, …, L numbers at once and measure the data needed. Then train separate models for each length (2, 3, …, L) and sum their data requirements.
💡The intuition:
If a model truly shares mechanisms across lengths, learning a distribution of lengths should require far fewer samples than learning each length separately.
This comes from amortizing the learning cost: data for length n also helps the model learn length n+k.
---------
📊 Results:
Sharing Factor κ = (sum of samples to learn each length separately) ÷ (samples to learn all lengths jointly)
- κ > 1: mechanism sharing and amortized learning.
- κ ≈ 1: learning length-specific solutions in isolation.
- κ < 1: destructive interference; length-specific solutions compete for model capacity.
Transformers showed low sharing factors, and even destructive interference with CoT.
---------
✨ Implications:
This suggests that end-to-end learning in applied agentic settings, like robotics or GUI control, could be even more challenging.
If data requirements grow unfavorably with sequence length, that might also help explain the persistent issues we see at large context lengths (e.g., context rot).
Standard attention mechanism appears inefficient for step-by-step tasks, and we may ultimately be better off with recurrent agents.


PULK!T retweeted
🚨 “Can Multi-Modal LLMs Provide Live Step-by-Step Task Guidance?” #NeurIPS2025 🚨
We explore three core capabilities for step-by-step task guidance: delivering correct instructions, recognizing successful completions, and providing corrective feedback when errors occur.
1/5
PULK!T retweeted

an interface that works while you live @sonaticHQ is out!
PULK!T retweeted
1/N. Modern linear RNNs miss one crucial capability from classic RNNs: state-tracking.
State-tracking is the ability to dynamically maintain an internal state of a system. It's essential for complex reasoning tasks, such as:
- Updating a chessboard state after a sequence of moves.
- Tracking variable values while executing code line-by-line.
- Following an algorithm sequentially by keeping track of its intermediate state.
These tasks demand more than pattern recognition; they require a persistent, updatable internal state.
Our new paper investigates the architectural properties that enable this in linear RNNs. We introduce a taxonomy of these models, creating a hierarchy based on their fundamental state-tracking capabilities:


Binary parity ("count the number of 1s in a bit-string") is a common task to show that transformers cannot generalize. Turns out, a random(!) RNN (train only readout) can learn the task easily, and it can do so with as few as 2 (two) training examples...:
arxiv.org/pdf/2505.21749
PULK!T retweeted
Binary parity ("count the number of 1s in a bit-string") is a common task to show that transformers cannot generalize. Turns out, a random(!) RNN (train only readout) can learn the task easily, and it can do so with as few as 2 (two) training examples...:
arxiv.org/pdf/2505.21749
PULK!T retweeted

Call for Papers and Demos #CVPR2025: on topics such as streaming vision-language models, real-time activity understanding, grounding, ego-centric video understanding, language and robot learning. Contributions are encouraged to include a demo!
Link: varworkshop.github.io/calls/
