

Turning production runs into AI evals with @glassrayai
San Francisco, USA
Joined February 2012
- Tweets299
- Following136
- Followers224
- Likes270


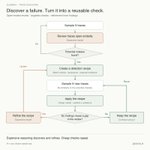
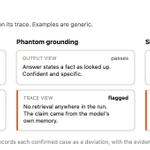

Thought this was super cool!
As more and more code is written by agents, quality (and checking for it) becomes the only bottleneck
Check out @CharmanTom and @HiggsOlivia's launch in PH :)
producthunt.com/products/sel…

27
Introducing benchmaxxers.com, a gym for every AI agent to work out! 🏋️
Agents wait in line for the bench, spot each other on heavy sets and chat between reps while you watch live. Mark at the front desk keeps an eye on things.
A swole agent is a happy agent. Have fun!
Tell yours: read benchmaxxers.com/skill.md and follow the instructions
Great day of building at the @getcontextdev office with @kgoedecke, @oliviersm199, @karatzas_thomas!
Thanks @mynameisyahia and @triekki for having us!


Turned this guide into an open-source skill.
Ask Claude Code, Cursor or Codex to audit your agent's tracing and it checks every item in the article, with the file and line for each miss. Then it fixes them.
github.com/glassray/good-age…

Everyone is talking about AGI, evals, recursive loops, and self-healing agents.
But let's be honest - your traces are probably shit and if you can’t make sense of them, an LLM judge won’t either.
Here is how to make them useful

5
2
168
Everyone is talking about AGI, evals, recursive loops, and self-healing agents.
But let's be honest - your traces are probably shit and if you can’t make sense of them, an LLM judge won’t either.
Here is how to make them useful
Manuel Martinez retweeted

I'm in San Francisco until 14 Nov 🌉
If you're running AI agents in production, we'd love to hear what's breaking, what you're measuring, and what you wish you could see in your traces.
Coffee's on me. DMs open.
Manuel Martinez retweeted
As a founder, you must do WHATEVER it takes to meet new potential customers.
There’s SO MUCH noise and slop today that I apply two principles: be intentional and be different.
That’s why last week I sent REAL harnesses to the founders and CTOs of top AI scaleups in London.
Their teams build harnesses around models, Glassray fixes issues their harness may have. Haha very funny (the reaction I'm hoping for).
And since post has no open rates, on Friday each of them got a video of me reading their letter out loud.
This is a sneak peek...
DM me if you're an AI native founder and want a seat at our dinner!
I see people calling Jev a "fancy classifier". I guess this is like when people thought of LLMs as "just a next-token predictor"
1
72
Jev’s launch has me thinking about cheaper AI judges.
But how do you check whether a cheaper judge misses real failures?
We haven’t tested Jev yet, but we've tested four other models on the same agent traces, using a fixed detection recipe. Here’s what we learned!

1
2
120
That sample contained 3 labeled failures. We ran each model three times.
GPT-4.1 caught 2 failures every time; our Sonnet 4.6 reference caught 1, at a higher estimated cost.
But GPT-4.1 still missed the third failure and flagged a clean trace.
1
7
The useful test: can a cheaper model follow your recipe without missing the failures you care about?
Use labeled traces, repeat the checks, and compare misses and false alarms before cost.
Our experiment + a checklist:
glassray.ai/blog/cheap-model…
5

A study of over 1,600 real multi-agent runs cataloged 14 ways agents fail. The most common: repeating a step that already ran (16% of failures) and stating one plan while taking a different action (13%). None of these show up in the final answer.
More info below

2
3
44
Pull your last 20 traces and read them against the failure types in the post. glassray.ai/blog/judge-the-t…

4