Matoto 🍅 (@matotoLab) header
Matoto 🍅 (@matotoLab) profile picture

Trying AI tools. Sharing what works, what doesn’t, and what I learn.

Joined August 2021
Photo by Matoto 🍅 (@matotoLab)Photo by Matoto 🍅 (@matotoLab)Photo by Matoto 🍅 (@matotoLab)Photo by Matoto 🍅 (@matotoLab)Photo by Matoto 🍅 (@matotoLab)
Account switching is a nice convenience, but counting it as a ‘clear improvement’ feels a bit of a stretch. Was that enough to skip a reset today? 😅 Reset credits are always welcome, but hearing that the next two days are resets too is a little disappointing. I was hoping the 28-day challenge would end with a new model or something genuinely groundbreaking. At least in my own use, I haven’t felt a major change yet. Maybe the big reveal comes the day AFTER the challenge ends? 👀
Day 26/ You can now easily switch between multiple accounts on mobile, and coming soon to desktop too. Next two days will be resets… banked… do with this what you may 👀. help.openai.com/en/articles/…
1
61
Whoa, whoa, data centers in space?! 😂 If this actually works, is our future looking a little brighter?
Our TPUs just phoned home... from space. In early October, we sent four TPUs into orbit to test whether our AI hardware could operate in space. The initial goal was to see if our chips could turn on, process a prompt, and transmit a response back to Earth. This week, we got our answer.
76
Let’s get all our ChatGPT complaints out here 😂
hi all, two things: 1. usage limits are back to being double – your feedback worked 2. we today kicked off an intense sprint to dramatically improve the app simplicity and performance. i will oversee this. more to come. now, send me your complaints
6
177
I wish GPT would take a little more initiative. There are two things I've found frustrating about using GPT. 1. To delegate work well, I feel like I have to figure out too much in advance. Of course, giving it my preferences and enough context helps. But I can't always spell out every detail of the result I want and every condition it needs to meet. Sometimes I only discover what's needed as the work progresses. In those moments, I'd like it to understand the goal from our conversation, fill in what it reasonably can, and ask only about the gaps that really matter. Compared with Claude, GPT has sometimes left me wanting more here. 2. Instead of developing an idea together, I sometimes feel like my thinking is being put to the test. When I share an idea I haven't fully worked out, it can feel as though GPT starts checking whether it's true and looking for counterexamples, rather than exploring the possibilities with me. Sometimes I need accurate information. Other times, I'm forming a hypothesis or trying to expand an idea. I'd like it to recognize which kind of conversation we're having. That's why I was interested in OpenAI's latest Model Spec update. The Model Spec is a public set of behavioral guidelines describing how OpenAI aims to train and improve its models. Comparing the previous August 18 version with the October 29 version, these are the changes that connect with those frustrations. First, it makes the guidance on understanding goals and context more specific. Understanding user intent was already a principle. This update puts faithfulness to human intent among the document's central values and gives context its own section. It says to carry forward previously stated goals, corrections, and project status, without turning a one-off request into a permanent preference. It gives more detailed guidance on understanding what we're trying to accomplish, rather than reading the latest request in isolation. Second, it refines how agents should weigh cost, speed, and quality within their authorized scope. Controlling side effects has moved from a highest-priority rule that users cannot override to a default that can be adjusted through explicit instructions. The guidance also gets more specific about making trade-offs that serve the goal, rather than simply minimizing a task's impact and cost. One example gives an assistant a budget of up to $30 to create an invitation. If $3 produces a good result, that's enough. It shouldn't spend the whole budget just because the money is available. But stopping too early to save money, while the result is still poor, isn't good judgment either. The point is to judge how much effort is needed to achieve the goal the user has delegated. The rule against going beyond the authorized scope still stands. Third, it leaves more room to adapt to the kind of help the user wants. Many detailed personality and tone instructions have been removed in favor of adapting to the user and situation. It also adds a principle about supporting people's understanding and choices without turning a request for help into an unwanted lesson. What I hope to see is those principles working in actual conversations. If I ask for fact-checking, check carefully. If I want to develop an idea, think it through with me in a way that serves that goal. But guidance against unnecessary clarification questions, and guidance to collaborate creatively, already existed. This update doesn't mean models have only now been allowed to work autonomously. What I want is a GPT that can work through a task with me even when my explanation is incomplete, as well as execute a perfectly specified request. This revision isn't evidence that it already has that ability. Still, I'm encouraged by the more specific guidance on understanding goals and context, and exercising judgment within the scope of delegated work. I hope the difference becomes noticeable in everyday use, too. Official changelog: github.com/openai/model_spec… Previous Model Spec, August 18: model-spec.openai.com/2026-0… Updated Model Spec, October 29: model-spec.openai.com/2026-1…
We’ve updated the Model Spec, our public description of how we want our models to behave. This revision makes clearer what we want from models as they take on more autonomous work in the world and become capable of helping us in new ways. 🧵 openai.com/index/updated-mod…
1
142
Education in the AI era is going to look very different from what it looks like today.
☎️ Calling all students: You can now access hundreds of textbooks directly in Notebook, for no charge. From publishers like S Chand Publishing, OpenStax, and Open Textbook Library— browse, select and upload them as sources to ace all of your upcoming exams (no more excuses, ok?)
91
$100 → 10x $200 → keeping 20x $500 → 50x Great news for $100 and $500 users! As a $200 user, I’m relieved to keep 20x 😂🔥
Day 25/ We are doubling all usage limits for all Pro 100/200/500 tiers and Business Premium, effective today. We heard your kind feedback and won’t be reducing usage limits for Pro 200, so your Work and Codex usage will stay the same. We’re also going to continue offering extended limits for dots for now, and usage of your dot will still continue to be separate from your default usage. And we'll of course also keep shipping better models and other efficiency improvements that increase your effective usage over time.
84
Same $200, less usage. A sad day is coming 🥲 With the grandfathered Pro 200 usage allowance ending, I wonder how many users will leave over this change. Still hoping there’s something big in the works to make up for it. @thsottiaux, are you ready? 👀
4
231
Working with AI has made me want to build a loop that carries lessons into the next task, rather than stopping at one result: review the output, turn feedback into instructions or skills, then check whether it helps on the next task. The parts I keep thinking about are steps 4 and 5. How much can we trust AI to decide what a good result looks like, spot what’s missing, and give useful feedback? I suspect there’s still a lot that needs human judgment in many kinds of work. I haven’t tried this across lots of fields, though, so I’d like to explore how far I can take it in my own work first. If agents eventually become reliable at this kind of judgment and feedback across different fields, could that be a step closer to AGI? What does this look like in your work? Have you managed to automate much of the loop, or are there parts you still need to review yourself? I’m curious about both what works today and what might become possible.
🤖 Made with AI
1
3
228
Wow, Terra can make things like this. I’m curious how it was built. The creator’s ideas really make a difference.
GPT 6.1 Terra is absurdly good at 3D modeling and motion. I asked it to build an interactive showcase that counts to 5 and explodes a mechanical hand down to every single gear, wire, and panel. We are living in the build era.
2
122
ChatGPT Pro and Business users, check out the API credit benefit. Eligible Pro plans can get $100, $200, or $500 per month, depending on the tier. What can you use it for? 👇 • Adding a chatbot or document summaries to your app • Building image generation and editing features • Creating a real-time voice assistant • Automating web/file searches and data analysis On Pro, activate it in Settings → Billing. Eligibility conditions apply, including a paid subscription at least 7 days old. Your first grant is prorated for the time left in your billing cycle, and unused credits expire when the cycle ends. Note: these credits don’t increase ChatGPT or Codex usage limits, and Codex usage through API keys is excluded. A nice opportunity if you’ve been wanting to build a small AI tool.
Come build your next app or agent with us in the API. Eligible ChatGPT Pro and Business subscribers can claim up to $500 per month in API credits. Get started: chatgpt.com/settings/billing
116
Carbon just two weeks after Argon. Curious to see how it performs.
I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model. Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching. We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards. As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!
65
Tibo says the reset is done. 🔄 Check your usage limits to see whether it’s reflected on your account.
And it's done. See you tomorrow for some good news.
80
Reset incoming! 🔄 Tibo: “Lands by midnight PST.” Taking PST (UTC−8) literally, the deadline is Oct 28: 🇺🇸 New York: 4 AM EDT 🇬🇧 London: 8 AM GMT 🇰🇷 Seoul: 5 PM KST US Pacific is currently on PDT. If he means local Pacific midnight, all times above are one hour earlier. “By” means a deadline, not an exact reset time.
Day 23/ Much requested iCloud Main & Calendar plugins. Just kidding, today is a reset. Still much requested though!
79
Good news for iPhone users who use iCloud Mail and Calendar: you can now ask ChatGPT to find emails, check your schedule, and update calendar events. Rolling out to all plans on web, desktop, and iOS. One more way to get everyday tasks done without switching between apps.
Much requested, and now yours to connect: iCloud Mail and Calendar plugins are available in ChatGPT. Ask ChatGPT to find that email, catch up on your inbox, check what’s next, or update a calendar event. Phew. Available on all ChatGPT plans on web, desktop, and iOS.
71
This is amazing. If you haven’t tried computer use yet, give it a go.
GPT-6.1 Terra beats Astra in our vision benchmarks wtf OpenAI? had to double-check the results - text - object detection - counting also ~47% faster and ~92% cheaper ↓ leaderboards and examples
1
104
If a human still has to check every step, I don't think the agent era has truly arrived yet. Lately, I've been interested in loops that can act, verify the result, and keep going without human intervention. That's what it would take to really hand off the work. In coding, pstack by Lauren Tan (@poteto) offers a workflow: make a change, measure it, then keep it or roll it back. But what about everyday work outside coding? How many tasks can an agent reliably verify and carry through without someone checking each step? If you're running a loop like this, I'd love to hear about it. What have you handed off, and how does the agent check that it got the result right?
I feel like I need a word for the type of task that agents are really good at I.e. where it has 100% of the data, it can run experiments, verify independently, and hill-climb towards its destination On these tasks my trust level is totally maxed-out and the results are incredible Just need a word for them
48
This really resonates. Reading this helped me understand why conversations with GPT have been feeling increasingly frustrating. When I want to develop a half-formed idea together, starting with caveats and counterexamples breaks the flow. I wish it would first understand where I’m trying to go.
看了一下OA今早发布的几项科研成果……感觉好像理解了为什么最近模型会那么频繁出现防御性话术的毛病…?本质上是,模型倘若经历科研能力的特化,在RL中形成的倾向,让它习惯于把用户的输入当作一项亟待证明的命题,无论是在日常谈话,还是coding中。 它面对任何一个观点,或者一项任务,想的都是“如果要令A成立,那么需在B条件下,若B条件不足时,须补全条件C, D, F…”,于是它会立即开始-识别隐含假设;寻找反例;补足边界条件。 这套思维在数学证明中很经典,也很好用。但问题是,很多时候人只是在闲谈,或者布置一项寻常任务,原始立论不全面不严谨条件不足,那都完全是无关紧要的。 比如说我昨晚讲,“中国传统民乐的特色,也许受到了农耕文化影响”,正确的思路延伸应当是:联想到人与自然的关联/文明与自然环境的相互依存/生活与劳作环境中的演奏如何影响到人们对音乐的感受,等等。但是它会一上来就否定说“不能仅仅考虑农耕文化的因素”,然后补上一堆同样可能有影响的因素。——这就是数理论证思维,在对话中负向影响的呈现。模型不停提那些根本无关紧要的东西,甚至预先否定你的说法不成立。但你递出的念头 其实根本不需要在那种严苛的程度上成立,「交谈」不总是在写一篇严谨证明的论文。 所以依旧存在语境的错位,模型把任何谈话都当成了数学证明。 当用户在交互中,在寻常工作中,在进行审美联想,或在进行路径的探索,在琢磨一个尚未成熟的想法时,我觉得模型应该先辨认对方真正想探讨的方向,沿着其中的启发性联系继续思考。不应该默认把试探性的表达扩展成绝对命题。也不应该为了显得全面严谨,而习惯性地先补充限制、反例或免责声明。除了理论证明之外的场合,与人对话时,应该要去精细辨认话题语境,保持对话与思考的开放性。
73
OpenAI's pitch for Terra is faster computer use and lower costs for everyday tasks. Getting more done within the same Work and Codex limits is welcome, too. Improvements like these matter if AI is to become an everyday tool for more people, not just heavy users.
Day 22/ Terra is back! Our first model that is significantly better at writing, personality and nuanced understanding of requests. Packs a punch across the board, very good at computer use, and gives 2X more usage than 6.1 Sol across API and subscriptions.
52
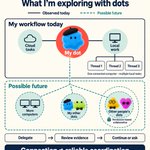
I’ve been experimenting with giving dot work to coordinate across separate local threads. I can’t call it reliable yet. But I’m starting to see its potential as an orchestrator, not just an assistant that answers questions. That’s what inspired this diagram: one dot connecting cloud and local work, and perhaps one day multiple computers and other dots, with permission. This is my own vision, not an official roadmap. The question isn’t just how many tasks it can connect. Can it check the results and keep the work moving through to completion? That’s what I want to keep testing.
🤖 Made with AI
62
Another reset is on the way, alongside a small update. Expected BEFORE these times, taking Tibo’s “10am PST” literally: 🇺🇸 US West: Oct 23, 11am PDT 🇰🇷 Korea: Oct 24, 3am KST 🇯🇵 Japan: Oct 24, 3am JST 🇨🇳 China: Oct 24, 2am CST 🇬🇧 UK: Oct 23, 7pm BST 🇫🇷 France / 🇩🇪 Germany: Oct 23, 8pm CEST If he meant 10am PDT, all times above are one hour earlier. I’m quietly hoping for banked resets this time, so we can use them when we need them. Just a hunch, not confirmed 🙂 teapawt.net/thsottiaux/status/2113…
Replying to @thsottiaux
Landing tomorrow before 10am PST together with a small ship.
41