
@Stanford CS PhD student // @KnightHennessy, @NDSEG, & @QuadFellowship
Stanford, CA
Joined October 2020
- Tweets25
- Following67
- Followers123
- Likes53

Pinned Tweet
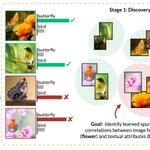
(1/4) Excited to share RaVL, which is appearing this week at #NeurIPS2024! RaVL discovers and mitigates spurious correlations in fine-tuned vision-language models (VLMs).
📄 Paper: arxiv.org/abs/2411.04097
💻 GitHub: github.com/Stanford-AIMI/RaV…


Maya Varma retweeted

🚨New preprint! 🚨In-context learning (ICL) is the intriguing ability of LLMs to learn to solve tasks purely from context w/o parameter updates.
For multimodal LLMs (MLLMs), ICL is poorly understood, especially in the medical domain where doctors would often face few relevant prior cases, prior imaging studies etc. But can MLLMs actually learn from context in the medical domain? 🤔
To answer this question, we introduce SMMILE— an expert-curated benchmark for multimodal ICL in the medical domain!
TL;DR:
💡MLLMs perform surprisingly poorly at multimodal ICL in the medical domain! --> ICL performance sometimes actually drops—some models perform worse than random baselines. Models have still a way to go here!
Previously, many ICL evaluations leveraged random, potentially irrelevant examples -> with the help of clinical experts, here we carefully craft explicit task demonstrations to more robustly probe the ICL ability.
📊 The benchmark:
-> 111 expert-curated problems (517 ICL problems)
-> 6 medical specialties, 13 imaging modalities
-> SMMILE++ variant with 1,038 permuted problems
-> Comprehensive evaluation of 15 state-of-the-art MLLMs
Check it out:
🔗 Page: smmile-benchmark.github.io/
📜 Paper: arxiv.org/abs/2506.21355
💻 Code: github.com/eth-medical-ai-la…
📁 Dataset: huggingface.co/smmile
Great collab with stellar colleagues @mrieff_02* @mayavarma23* (co-first) @IAMJBDEL# (co-last) and more!
Maya Varma retweeted

💥 We unveil our paper accepted at the #ACL2025 Main Conference:
Automated Structured Report Generation
Let's revisit automated radiology report generation for CXR.
Free-form reports make it hard for AI systems to learn accurate generation, and even harder to evaluate. 🧵👇
@StanfordAIMI @hopprai
Maya Varma retweeted

🧵 What if AI could learn from millions of unlabeled radiology images and reports—and then flexibly adapt to new clinical tasks? In a new comprehensive review in @radiology_rsna, we dive into how foundation models (FMs) are set to revolutionize radiology! @AIMI_Stanford (1/6) 👇

Maya Varma retweeted

Learn about AI foundational models in radiology in this review article! @StanfordAIMI @StanfordRad @StanfordMed @magdapasc @zhjohnchan @mayavarma23 @loublanks @Alaa_Youssef92 @cxbln @curtlanglotz @Dr_ASChaudhari bit.ly/4jL4OGG

Maya Varma retweeted

1/ Updates on our improved open-source CheXagent with new transparent benchmarks!
We ran a new reader study mimicking real workflows:
Radiology residents drafted reports that attendings reviewed/edited.
Results from 8 rads show major efficiency gains. Key findings: 👇
(3/4) We evaluate RaVL by introducing a large-scale evaluation framework with 654 fine-tuned VLMs annotated with ground-truth spurious correlations. We also show that RaVL can surface novel spurious correlations in off-the-shelf VLMs, both in the general and medical domains!
1
203
Maya Varma retweeted
So proud of the release of the GREEN metric. See what you can do when you merge medical AI research and open-sourceness.
26,000 downloads on 🤗 Hugging Face and counting.
🟥 EMNLP proceedings: aclanthology.org/2024.findin…
🤗 Dataset: huggingface.co/datasets/Stan…
🤗 Models: huggingface.co/collections/S…
🤗 Space: huggingface.co/spaces/Stanfo…
🐍 GitHub: github.com/Stanford-AIMI/GRE…
📄 Project Page: stanford-aimi.github.io/gree…
🧵 👇

Maya Varma retweeted

🧙 Excited to introduce Merlin, a vision language foundation model for 3D computed tomography 🐈⬛🩻
Trained to understand 3D abdominal CT scans using supervision from:
💾 Structured electronic health records (1.8+ million codes)
🗒️ Natural language radiology reports (6+ million tokens)
Paper: arxiv.org/abs/2406.06512
🧵 1/10
Maya Varma retweeted

Five years ago, thanks to the leadership of @mattlungrenMD, @stanfordAIMI released the CheXpert images: 223K JPG CXRs with labels for 14 conditions. CheXpert has been cited >6000 times, mostly related to development of supervised learning methods. Much has changed since then.🧵

Maya Varma retweeted
🧵[1/3]🚀Exciting news from AIMI! We're leading the charge in #ClinicalTextGeneration with two pivotal tasks at #BioNLP2024 & #ACL2024: 🩺 Radiology Report Generation, enhancing clinical communication via AI-generated X-ray reports, & 📄 Discharge Me!, streamlining EHR notes to combat clinician burnout. Details at stanford-aimi.github.io/RRG2… & stanford-aimi.github.io/disc…
Maya Varma retweeted

Ran out of OpenAI credits?💰 We present a prompting strategy that enables open-source and off-the-shelf GPT-J-6B to outperform *few shot* GPT3-175B on 15 popular language benchmarks! 🚀
Paper and code:
📜 arxiv.org/abs/2210.02441
💻 github.com/HazyResearch/ama_…
Excited to share Domino, which is appearing as an oral at #ICLR22! We use cross-modal embeddings to identify & describe systematic errors in ML models.
📜: arxiv.org/abs/2203.14960
Joint work w/ @EyubogluSabri @KhaledSaab11 @jdunnmon @james_y_zou @HazyResearch & others!


Do you ever wonder if your model - despite logging impressive accuracy - is still failing on an important but unknown slice of your dataset? We certainly do!
Stoked to share recent work @iclr22 in which we develop & evaluate ~slice discovery methods~ (1/7)
ai.stanford.edu/blog/domino/

Maya Varma retweeted

New preprint alert! 📣
How do we produce transferable and robust representations with supervised contrastive learning? We need *geometric spread* and an inductive bias towards *latent subclass clustering* in representation space.
📜 arxiv.org/abs/2204.07596
👇 (1/n)

Maya Varma retweeted

New preprint alert! 📣
How do we improve long-tailed performance of entity retrieval? We use a supervised contrastive loss to *geometrically encode entity types* in representation space w/ bi-encoders. Check out our paper on TABi!
📜 arxiv.org/abs/2204.08173
Details👇 (1/n)

Excited to share our paper “Cross-Domain Data Integration for Named Entity Disambiguation in Biomedical Text,” which appeared this week at #EMNLP2021!
Paper: arxiv.org/abs/2110.08228
Code: github.com/HazyResearch/medi…
Data: huggingface.co/datasets/mvar…

(5/6) We utilize our integration scheme to augment structural resources and generate a large pretraining biomedical NED dataset (available at huggingface.co/datasets/mvar…).

2