





"the mechanism is outside the scope of this report"
This mechanism is block-routed top-k, k=16K. Internal name: DBSA (presumably "dynamic block sparse attention").

Here is the technical report on SubQ 1.1 Small.
subq.ai/subq-1-1-small-techn…
This is the second iteration on our Subquadratic Sparse Attention (SSA) model, and the first to be deployed with design partners in the coming weeks.
The results are compelling and verified by @AppenResearch.
- Near-perfect long-context retrieval up to 12M tokens on the needle-in-a-haystack test, with up to nearly 1,000x attention compute reduction.
- A balance of long-context optimization and general reasoning ability, with strong performance retained across knowledge, coding, and non-coding enterprise agent benchmarks.
- At 1M tokens, SubQ 1.1 Small requires 64.5x less compute than dense attention and runs 56x faster than FlashAttention-2.
These results highlight a significant scaling advantage thanks to the efficiency gains from the SSA architecture.
We included some details and learnings from the development process which may be helpful to the community.
Comment with questions, I’ll try to respond!

Wanted to cancel my @github sponsorship for @ziglang. However the sponsor page just returns HTTP 500: github.com/sponsors/ziglang

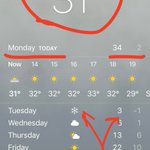
What is Apple thinking? I expected Siri to catch up to ChatGPT/Claude years ago. Meanwhile, on the latest OS, Siri on my Apple Watch can't tell me what temperature chicken should be cooked to
.@matroid not sure who this is on your speakers list, but it's not @aelluswamy

Sergey Serebryakov retweeted

How could #AlphaFold 3 transform drug discovery?
Most drugs are small molecules known as ligands that bind to proteins to change how they interact in human health and disease.
AlphaFold 3 can predict these interactions to atomic accuracy.
There are vast and obvious inefficiencies wherever there was no dedicated optimization effort, and possibly even where there was
Also true for organizations

This post became popular; Few more thoughts / pointers on the topic for the interested reader.
Example of the complexity involved:
@cHHillee has a great post "Making Deep Learning Go Brrrr From First Principles"
horace.io/brrr_intro.html
I was always struck by this diagram from this post. Left to right is time. Look at all these functions stacked up vertically that are dispatched until 30 layers deep you get the actual computation (addition in this example). All of this stuff is PyTorch function overhead. In practical settings this overhead becomes narrow in comparison to the actual computation because the arrays we're adding are so large, but still. What is all this stuff? We're just trying to add numbers.
Second: startup latency.
Open up Python interpreter and try to import the PyTorch library (`import torch`). On my computer this takes about 1.3 seconds. This is just the library import, before you even do anything. In a typical training run you'll end up importing a lot more libraries, so even just starting your training script can often add up to tens of seconds of you just waiting around. A production-grade distributed training run can even add up to minutes. I always found this very frustrating. Computers are *fast* - even a single CPU core (of up to ~dozens on your computer) does billions of operations in one second. What is happening? In llm.c, all this startup latency is ~gone. Right after allocating memory your computer just directly dives into useful computation. I love the feeling of hitting Enter to launch your program, and it just goes. Direct to useful computation on your problem. No waiting.
Third thought: LLM as a compiler.
It feels likely to me that as LLMs get much better at coding, a lot more code might be written by them, to target to whatever narrow application and deployment environment you care about. In a world where very custom programs are "free", LLMs might end up being a kind of compiler that translates your high level program into an extremely optimized, direct, low-level implementation. Hence my LLM Agent challenge earlier of "take the GPT-2 PyTorch training script, and output llm.c", as one concrete example.
Lastly I also wanted to mention that I don't mean to attack PyTorch at all, I love the library and I have used it for many years. And I've worked in Python for much longer. These are a lot more general problems and tradeoffs that are really fun to think through - between flexibility, generality, hackability, security, abstractions overhead, code complexity, speed (latency / throughput), etc. The fun and magic of pareto optimal infrastructure, and of programming computers.


Funding secured enhanced.org/2024/01/29/seed…

You want to build and install an iOS app on your device? Your iOS is too new, an Xcode update is required. To update Xcode, a macOS update is required. This development toolchain is so broken.

Sergey Serebryakov retweeted
Прокуратура обвинила в организации экскурсии по коллекторам, во время которой погибло восемь человек, Александра Кима — основателю сервиса «Спутник».
Ким проходил по делу как свидетель. Его сервис не организует экскурсии
vc.ru/legal/806543

In New York, with a high enough wage, your effective income tax starts to equal marginal state tax, by design. Crazy that it's not talked about more!
bogleheads.org/forum/viewtop…
And California, when taxing nonresident income, applies tax bracket computed from the total income. Amazing.