
Ph.D student at KAIST AI.
Joined October 2020
- Tweets30
- Following84
- Followers216
- Likes106




MiyoungKo retweeted

1/ Pattern matching has been left ambiguous for so long.
Our precise formalization pinpoints its predictive power on composition tasks!
📣 Check out our ICLR 2026 paper:
1️⃣ Sharp sample complexity bound for 2-hop task;
2️⃣ Some unexpectedly hard composition tasks: CoT won’t help.

MiyoungKo retweeted

🚨 Our new paper from @MSFTResearch accepted at ICML 2025!
Can LLaMA be distilled from DeepSeek in logit space, even with completely different vocabularies?
We presents:
“Overcoming Vocabulary Mismatch: Vocabulary-agnostic Teacher-Guided Language Modeling”
[1/5]

MiyoungKo retweeted

🏆Glad to share that our BiGGen Bench paper has received the best paper award at @naaclmeeting!
teapawt.net/naaclmeeting/status/19…
📅 Ballroom A, Session I: Thursday May 1st, 16:00-17:30 (MDT)
📅 Session M (Plenary Session): Friday May 2nd, 15:30-16:30 (MDT)
📅 Virtual Conference: Tuesday May 6th, 20:30-21:00 (MDT)
I'd like to appreciate our coauthors @scott_sjy Ji Yong Cho @ShayneRedford @chaechaek1214 @dongkeun_yoon @gson_AI Yejin Cho @shafayat_sheikh @jinheonbaek @suehpark @ronalhwang @Jinkyung_Jo Hyowon Cho @haebinshin_ @sylee_ai @hanseok_oh @nlee288 @itsnamgyu @joocjun @miyoung_ko @yoonjoo_le2 @hyungjoochae @jay_shin @jang_yoel @SeonghyeonYe @billyuchenlin @wellecks @gneubig Moontae Lee @Kyungjae__Lee @seo_minjoon! It wouldn't have been possible without everyone's feedback and hard work 😀


MiyoungKo retweeted
🚨 New paper alert! 🚨
Isn’t it wasteful to repeat lengthy & complex agent prompts every time?
Introducing "Generative Context Distillation"—a new lightweight method to internalize prompt.
🦾 Powerful performance
💵 Efficient inference
"without the need for a prompt📜"
[1/7]

I'll be attending #EMNLP2024 to present "Hierarchical Deconstruction of LLM Reasoning: A Graph-based Framework on Analyzing Knowledge Utilization"
📍In-Person Poster Session D (Jasmine)
🕐 Nov. 13 (Wed.), 10:30 AM - 12:00 AM
📕arxiv.org/abs/2406.19502
Would love to chat about reasoning, interpretability, and factuality 🌴

MiyoungKo retweeted

🚀 First step to unlocking Generalist Robots! Introducing 🤖LAPA🤖, a new SOTA open-sourced 7B VLA pretrained without using action labels.
💪SOTA VLA trained with Open X (outperforming OpenVLA on cross and multi embodiment)
😯LAPA enables learning from human videos, unlocking potential for robotic foundation model
❗Over 30x pretraining efficiency for VLA training
🤗Code and checkpoints are all open-sourced!
MiyoungKo retweeted

❓Do LLMs maintain the capability of knowledge acquisition throughout pretraining? If not, what is driving force behind it?
❗Our findings reveal that decreasing knowledge entropy hinders knowledge acquisition and retention as pretraining progresses.
📄arxiv.org/abs/2410.01380

MiyoungKo retweeted

I’m happy to share our Janus work has been accepted to #NeurIPS2024 ! Thank you for co-leading this project @suehpark 🥳
See you in Vancouver 🇨🇦


Glad to share our work regarding depth-wise reasoning was accepted by #EMNLP2024 Main track!

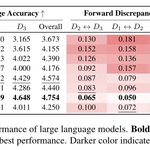
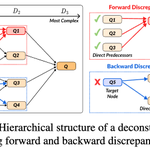
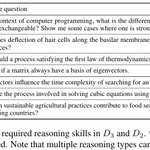
📢 Excited to share our latest paper on the reasoning capabilities of LLMs! Our research dives into how these models recall and utilize factual knowledge during solving complex questions. [🧵1 / 10]
arxiv.org/abs/2406.19502

🚀 Check out our paper for a deep dive into the reasoning capabilities of LLMs and how structured approaches can enhance their performance on complex tasks. [🧵9 / 10]
- Paper: arxiv.org/abs/2406.19502
- Code: github.com/kaistAI/knowledge…
- Dataset: huggingface.co/datasets/kais…
A huge thanks to my collaborators @suehpark (co-lead💪🏻), @Joninneverland, @seo_minjoon for their essential contributions to this research 😊 [🧵10 / 10]