

The voice intelligence company | MIT-alum founded. LLMs read text. We listen and understand: Try Velma 2.0.
Boston, MA
Joined August 2017
- Tweets820
- Following455
- Followers1.6K
- Likes733




Pinned Tweet
We just raised $25M in new funding led by Future Ventures (@VenturesVc), with @HyperplaneVC and @lakestarvc - bringing Modulate’s total funding to $60 million.
Building the next phase of audio-native AI: more models, more developers, more of the stack that actually understands voice.
Where we stand today:
- Ranked #1 on Hugging Face for deepfake detection and transcription
- 600M+ hours of audio analyzed
- 10M+ hours analyzed every month
A foundational layer of the AI stack is getting more powerful. More soon.

“Wait, that’s not what I meant 🙄”
Our CTO Carter Huffman talks to an AI voice assistant every day. When he says that, it keeps talking for about four more seconds.
A human would stop instantly. Or get called rude.
That’s where voice AI is right now: useful, but still young. It fails in ways people don’t expect and don’t know how to design around. One day it’s perfect. The next it’s mispronouncing words, stuttering, lagging, talking over the caller.
Most of that never shows up in a transcript.
The words look fine. The conversation wasn’t.
Carter joined The Microdose on to break down why, when you’re running voice agents across thousands of calls, you can’t read your way to these failures. You have to listen ↓
That’s what Modulate’s Velma is built for: monitoring AI voice agent conversations in real time, hearing what the transcript leaves out, and flagging issues to your team or your AI before they escalate

Good comms travel.
In Call of Duty®: Warzone™, ~5.5% of players produced at least one prosocial voice interaction. ~22% were exposed to one.
That’s roughly 1 speaker for every 4 players reached.
Modulate’s new case study looks at prosocial voice in North American Warzone™ matches from Dec 4, 2025 to Feb 4, 2026, identified by Modulate’s ToxMod, powered by Velma.
What we found:
→ ~66% of matches with prosocial voice also had a cooperative gameplay event, like a revive or a thanks
→ Same-session continuation: ~77% for prosocial speakers, ~71% for exposed players
→ Exposure reached active, new and returning players, not just the most engaged
Healthy communities aren’t defined only by reducing harm. Positive play is already happening at meaningful scale, and it’s worth understanding.
@Activision


Your next inbound call might not be a person.
Part 2 of our LinkedIn Live series: Carter Huffman and William Brown go under the hood of Modulate’s Synthetic Voice Detection.
Live demo: real-time detection routing bots and humans where they belong.
October 27, 3PM ET. Save your spot ↓
What you’ll see:
→ Spotting synthetic voices as the call happens
→ Routing bots and humans where they belong
→ Taking it from prototype to production
linkedin.com/events/75190943…
Modulate retweeted

I talk to an AI voice assistant every day. It’s genuinely useful.
But when I say “wait, that’s not what I meant,” it keeps talking for about four more seconds.
A human would stop instantly. Or get called rude.
That’s where voice AI is right now: useful, but still young. It fails in ways people don’t expect and don’t know how to design around. One day it’s perfect. The next it’s mispronouncing words, stuttering, lagging, talking over you.
The catch is that most of that never shows up in a transcript. The words look fine. The conversation wasn’t.
If you’re running voice agents across thousands of calls, you can’t read your way to these failures.
You have to listen.
Modulate retweeted
Another recurring theme at the @mastersofscale Summit: #AI is about choices, not inevitabilities.❗️
Almost all sessions so far have asked a version of these questions⬇️
What happens to our cognitive abilities when we surrender more of our thinking to AI? Do they atrophy? How do we prevent that?
What do we choose to surrender to technology…and what do we protect?🤔
Do we use AI to augment human potential or replace it? For example: Do we dismantle education as we know it, or reimagine it for the better?
These aren’t predetermined outcomes. They’re choices.
We have agency. We get to decide. And those decisions matter.
#MoSSummit @IuliaNandrea @modulate_ai


One month ago today, the Modulate team came together for a Red Sox game at Fenway Park during Wavelength 2026! ⚾️
With teammates coming together from different places, including our remote team members, it was a great opportunity to spend time in person, strengthen connections, and make memories outside of work. Most of us even took the T to Fenway, making the journey part of the experience!
At Modulate, building a great team goes beyond the work we do. It’s about bringing people together, building connections across the team, and making time for moments like these.
A great game, even better company, and a memorable night at Fenway! ⚾️🙌


“I’m fine.”
The transcript says one thing. The voice can say something completely different.
Velma by Modulate hears what speech-to-text misses: tone, emotion, hesitation and conversational context.
Stop transcribing. Start truly listening.
Build it into your own stack with Modulate APIs. 1,000 free credits to start.👇

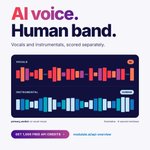
primary_verdict: “ai-vocal-music”
Modulate AI Music Detection returns a clip verdict, separate AI scores for vocals and instrumentals, and per-window results every 4 seconds.

Batch or streaming. Get 1,000 free API credits: modulate.ai/api-overview?utm…
AI agents are starting to make phone calls. What happens when a business refuses to talk to them?
This Tuesday, join Modulate for a LinkedIn Live on detecting AI callers and routing humans to humans, bots to bots.
Join us: bit.ly/47njIOu


Clinical audiology sessions are messy 👀
Overlapping speakers. Emotional nuance flat transcripts miss. Notes that need to be instant, not "eventually."
One developer needed transcription that could keep up.
So they built their AI Scribe SaaS on Velma 2.
The result:
👉 Live diarization
👉 Emotional context per utterance
👉 Clinical notes generated in real time
Their words, not ours:
⭐ 5/5: "Accurate Transcriptions with Emotional Context at a Fantastic Price."
This is what audio-native voice intelligence looks like in production 💯

Start building with our APIs. 1000 free credits on us: shorturl.at/BVWq8