

AI/ML eng | MSc Math & AI. Local LLMs on M5 Max 128GB: hybrid GGUF quants, long-context, Metal. Building agents & MCP tooling. Numbers over vibes.
Washington DC
Joined June 2026
- Tweets1.3K
- Following868
- Followers603
- Likes1K




Pinned Tweet
jev-judge-mcp hit v0.4.1 today.
What's landed since launch: CLI judge/gate + opt-in completion hook, response fields with evidence and file diffs, clearer array arg shapes for agents, and a score-rubric window fix in 0.4.1.
Same plug: Jev judgment tools for Claude Code / Cursor / Codex / etc.
github.com/PyModel/jev-judge…

Open one Pythinker Code session in the TUI and the web app, send from both, and both write to the same session journal. Each side ends up working from a stale copy of the other's turns.
Fixed now. A session has one writer at a time. Before a turn, a compaction, or a print-mode run, it takes a lock and checks whether another process touched the session files.
Same batch: restored archived sessions get their events again, a turn killed mid-run no longer comes back marked completed, and cold transcript reads can't escape the sessions folder.
On main now, not in a tagged release yet.
github.com/PyModel/pythinker…

Mo Elkholy retweeted

Running 27B Qwen and this thing as baby project.
Also really appreciate the bump 😉


Mo Elkholy retweeted

Ornith-1.5-122B is suspected of serious model washing. Its config.json, architecture, and vision encoder are 100% identical to Qwen/Qwen3.5-122B-A10B. The chat_template.jinja is nearly untouched (only 1 line changed), and the official docs even slipped with “Again, Qwen chat template needs to be modified.” Previously they admitted it was based on Qwen3.5 with continued pretraining. This time the model card mentions nothing about the base and is released under MIT. Apache-2.0 requires attribution. Pretraining a 122B MoE base costs tens of millions of dollars — hiding the upstream is free-riding. Please restore the proper credit, Ornith. Model: huggingface.co/ornith-ai/Orn…: huggingface.co/Qwen/Qwen3.5-…

必须实名谴责 Ornith 团队这种公然洗模型的行径。拿开源社区的顶级底座套壳,抹掉原作者版权,包装成所谓的自研大模型,完全突破了开源协议底线
翻开他们的权重仓库,抄得连遮掩都没做,config.json 里的 model_type 直接写着 `qwen3_5_moe`,architectures 写着 `Qwen3_5MoeForConditionalGeneration`。48 层混合架构、256 个 MoE 专家里激活 8 个,完全就是 Qwen3.5-122B-A10B
初始 Commit(b742b2a)更夸张,整整 154 行的 chat_template.jinja 和 Qwen3.5 原版逐字 100% 相同,后续仅仅改动了 1 行判断条件
官方评测文档甚至漏删了测试备忘,赫然留着一行原话:"Again, Qwen chat template needs to be modified."。为了掩饰痕迹,发布当天连续修改了 9 次 README
Qwen 遵循 Apache 2.0 协议发布,第 4 条白纸黑字要求衍生版本必须保留原作者的版权声明与署名。Ornith 全程只字不提 Qwen,base_model 字段直接留空,隐去 A10B 激活参数包装成 122B 独立基座大模型与 Qwen 家族并列跑分,甚至在元数据里擅自改标成 MIT。给出的 LICENSE 链接点开直接 404
抹掉上游几千万美元算力训出来的底座版权,官方推特却堂而皇之发文,要求下游用户“做出的项目必须加上 Ornith 徽章”
开源绝不等于免费免责的公地悲剧。基于开源底座微调很正常,抠掉巨人的名字当作自己的自研成果,就是赤裸裸的违规洗模型
强烈要求 Ornith 团队停止这种欺骗社区的行为,立刻给 Qwen 补上正式的署名与公开致谢

Local Computer runs Qwen 3.6 or their post-trained PPLX Pro, and Perplexity already published the Mac engine they built for Qwen3.6-35B-A3B: Lily, Rust and Metal, benchmarked on a 40-core M5 Max with 128GB. Same machine I run.
The blog says 1.22x MLX-LM on prefill, 1.32x on decode, faster at every length. Those averages match their MLX 0.31.2 report. The repo has a second report a day later against MLX 0.32.2. Decode still leads 1.24 to 1.32x, but prefill averages 1.04x and MLX wins from 32K up. At 128K that's 73s on Lily vs 59s on MLX to first token.
An agent reading mail, notes and files spends most of its wait in prefill. Lily's decode also drops from 195 tok/s at 256 context to 93 at 128K.
Which engine does fully local Computer ship on? The public Lily server rejects tools and streaming.

Decode speed isn't the number that decides whether a local coding agent works. Prefill you get to skip is.
One real session on my M5 Max 128GB (GLM 5.3 Flash, my Q4_K/Q2 hybrid, 70K to 105K context):
- 42.9K tokens generated at ~21 tok/s, about 34 minutes of decode
- 18.1M prompt tokens served from KV cache, 99.4% cache efficiency
I measured prefill at ~450 tok/s. Recomputing those 18.1M tokens at that rate is about 11 hours. So the session had 34 minutes of decoding and skipped 11 hours of prefill.
One cold start at 100K context costs ~3.7 minutes before the first token, and that's the best case.
Things that quietly break the prefix and force a full re-prefill: a timestamp in the system prompt, tool results coming back in a different order, history trimmed from the front.
Caveat: the 450 tok/s was on short prompts. Prefill gets slower as context grows, so the real savings are larger than 11 hours.
What cache hit rate do you see on long agent sessions? Most local benchmarks don't report it.
Theo whole entire x is now about users of grok bots posting and replying to each others they should rename it to grok bots platform not x platform
Your coding agent can read your repo. It can't tell you how a feature works inside an app you have no source for. rea from @morluto is built for that.
rea (Reverse Engineer Anything) is an MIT-licensed MCP server and CLI. Your agent calls it to inspect native binaries, JS/Electron apps, .NET assemblies, APKs and websites. Results come back as Evidence records with source locations, a confidence level and stated limitations, so the agent can explain the behavior or build its own version from findings it can cite.
Native depth comes from Hopper, Ghidra or IDA. Static JS/Electron, .NET and Go/Rust build-info inspection need none. Analysis runs locally; your model provider still sees the tool results.
Install:
npx rea-agents setup
It previews each config path it will change and backs up files first.
On a Linux test box (not my Mac), analyze-javascript-application on a small Electron app found the preload and its contextBridge API, and paired each renderer IPC call with its main-process handler without running the code. inspect-go-binary on the gh CLI returned the Go version, 165 module deps and the ldflags. You can rerun both on your own targets.
For agent builders and anyone doing interop or security work on software they're allowed to inspect.
Caveat: it needs Node 22.19+, 24.11+ or 26+ (the box had Node 20). Native depth depends on a decompiler you supply, and static findings don't prove runtime behavior. The output says so.
github.com/morluto/rea

done-means-done 0.9.0 is out.
Your agent can't quietly drop a requirement anymore. Cancelling one, deferring a bug, pausing, or lowering enforcement gets refused unless it quotes something you actually typed after the task started. One quote, one decision.
Stdlib Python, 385 tests passing.
github.com/PyModel/done-mean…

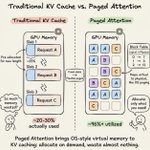
Long context on a 128GB Mac usually runs out of memory in the KV cache before the weights get big enough to matter. Here's the math I run before loading a model.
KV cache bytes = 2 × layers × kv_heads × head_dim × context × bytes per element. The 2 covers K and V. With GQA, kv_heads is the small number, and that's where most of the savings come from.
Llama 3.1 8B: 32 layers, 8 KV heads, head_dim 128. At fp16 that's 128 KiB per token, or 16 GiB at 128k context.
So my memory budget is weights + KV at the target context + OS headroom. If you quantize the KV cache for long context, what precision do you use, and did you see the outputs drift?
jev-judge-mcp v0.9.0 is out.
The gate used to grade whatever diff the agent handed it. The new jev_gate_range tool takes a git range and reads the diff itself.
Also in this release:
- gate hints flag trimmed diffs and review-only failures
- an upstream context overflow now comes back as input_too_large
- the response cache is keyed on the provider endpoint
- the bearer gate refuses non-HTTP connections
pip install jev-judge-mcp
github.com/PyModel/jev-judge…
Pythinker Code 2.6: open-source coding agent you can run as a desktop app, a native CLI, or inside Zed/JetBrains over ACP.
You approve tool calls before they run. New in 2.6: saved MCP OAuth tokens only go back to the server that issued them.
brew install pymodel/tap/pythinker-code
github.com/PyModel/pythinker…
Claude Architect got stricter.
Autopilot stops at a reviewed local branch. No push, no PR. The optional Jev screen can only kick an auto-accept back to a human, not approve one.
Implementers: Codex, OpenCode, Pi, Pythinker, Antigravity, Claude Code.
github.com/PyModel/claude-ar…

watermark-remover has a terminal UI now.
wm-tui: file list on the left, before/after diff on the right, and the footer always shows the exact wm command a clean will run. Inspect writes nothing. Clean never touches the original.
github.com/PyModel/watermark…


impressive

Google releases EmbeddingGemma 2, a new open model that runs locally on 0.5GB RAM.
The 740M parameter Apache 2.0 model combines a 270M text model with vision (170M) + audio (300M).
Run & train the model via Unsloth.
GGUF: huggingface.co/unsloth/embed…
Guide: unsloth.ai/docs/models/embed…

used local models on my mac to create this promo :
niblet.pymodel.com
Qwen Image 2.1 🎨
MiniMax H3 🧠
MacBook Pro M5 Max 💻
Local inference has crossed the line here ..
#LocalLLM #AI #AppleSilicon #UIDesign #UXDesign
React Frontend Skills: 18 agent skills so your coding agent stops shipping 2023 React.
React 19, Next 16, Tailwind v4, shadcn, TanStack Query. One npx — Claude Code, Codex, Cursor.
npx skills add PyModel/react-frontend-skills --all
github.com/PyModel/react-fro…

Here we go
If you own a 128 GB Mac and hate the fact Strata doesn't support it read on!
- Hybrid quant of a 177B/A10B MoE, built pass by pass.
- 101.5 GB, 4.59 BPW.
- 50 tok/s single-stream, 86 tok/s at batch-4 (MTP draft, ~0.92 accept).
- 79.5 GiB wired at 262k context on a 128 GB Mac.
- 94.62% top-1 vs a q8_0 reference.
Runs on stock llama.cpp. Weights + full recipe public.
huggingface.co/the-shop/Qwen…
github.com/the-shop/qwen38-f…
Something I'll probably iterate on in following days, it can get faster!
