
Founder and CTO - https://teapawt.net/t.co/U2V05bVdmx
New Delhi, India
Joined January 2009
- Tweets6K
- Following576
- Followers856
- Likes16.2K





Hard agree

Also this firing would be the most Man United thing ever. The last 3 games against Roma Chelsea and Villa have seen at least one half of excellent football. We should have been out of sight in that first half against Chelsea. We were completely dominant in the second half against a Roma team that has pretty much decimated all comers this season. And against Villa, with the ball on the ground, we were much the better team.
All season long we have given goals to the bozo gene that runs through a defense that has needed serious upgrading for quite some time now but has always been ignored. That Lammens comes up with two blunders in 4 minutes is not a managerial mistake. That Dalot is always the punchline to a joke about United is also not a managerial mistake. And that our best defender of the season so far - Lenny Yoro - got too heavy a touch on a clearing header is also not a managerial mistake.
It wasn't gung ho football that ensured we had 9 unanswered shots on goal against Villa after conceding the second. It was often deep build up and rapid movement of the ball through the lines. If Amad Diallo could score to save his life, we'd be top half.
If Sesko, Shaw and MdL - know injuries or expected injuries at the start of the season - had been replaced in the summer, we'd be well in this season. There are very few games in which we have played as badly as our league position suggests.
This manager has not gone into defensive mode. He keeps playing his game model. The press is atrocious often and then it looks a lot better over the last few games. That's how you grow. If you fire him and restart, all you're doing is giving Berrada and Wilcox a fresh excuse. They are the problem. Not Michael Carrick.
58
Mithun M retweeted

Also this firing would be the most Man United thing ever. The last 3 games against Roma Chelsea and Villa have seen at least one half of excellent football. We should have been out of sight in that first half against Chelsea. We were completely dominant in the second half against a Roma team that has pretty much decimated all comers this season. And against Villa, with the ball on the ground, we were much the better team.
All season long we have given goals to the bozo gene that runs through a defense that has needed serious upgrading for quite some time now but has always been ignored. That Lammens comes up with two blunders in 4 minutes is not a managerial mistake. That Dalot is always the punchline to a joke about United is also not a managerial mistake. And that our best defender of the season so far - Lenny Yoro - got too heavy a touch on a clearing header is also not a managerial mistake.
It wasn't gung ho football that ensured we had 9 unanswered shots on goal against Villa after conceding the second. It was often deep build up and rapid movement of the ball through the lines. If Amad Diallo could score to save his life, we'd be top half.
If Sesko, Shaw and MdL - know injuries or expected injuries at the start of the season - had been replaced in the summer, we'd be well in this season. There are very few games in which we have played as badly as our league position suggests.
This manager has not gone into defensive mode. He keeps playing his game model. The press is atrocious often and then it looks a lot better over the last few games. That's how you grow. If you fire him and restart, all you're doing is giving Berrada and Wilcox a fresh excuse. They are the problem. Not Michael Carrick.

Good to see that the value of accuracy via an ontology is being recognised. Just past the hype of 'I want AI' is 'but it had to be accurate in the critical path'. Good think we @pascalailabs have been building with an ontology from day 1 :)

Today, we’re launching Ontological Legal Research in the US.
Legal research sits underneath so much of what legal teams do. The advice, the argument, the agreement all depend on getting the law right. Solving research changes what AI can take on across all of that work.
AI fails at legal research in critical ways. The law is spread across millions of documents, and a model can only process a few hundred at a time. So it picks out pages that look relevant in isolation, and never sees the later decision that overruled the case it’s relying on.
That’s the problem we’re solving with Ontological Legal Research.
We’re bringing comprehensive legal data together with a proprietary ontology that maps how the legal sources connect. This enables the Legora Agent to see the full picture of current law and navigate it with unprecedented accuracy.
The best data and the best technology, together in one place.
Live today in the US. More jurisdictions to follow.
Read the launch blog: legora.com/blog/introducing-…
52
Mithun M retweeted

A long time ago I spent about 4 hours using an LLM to research startup ideas and managed to come out with a pretty terrible product thesis.
I was looking at different spaces I was curious about and potential ideas for startups in each. I asked AI to research customers, what they might want, whether an idea made sense, and then I started changing things. What about this angle? What if the ICP was different? What if we changed the product?
And a lot of times it came back with very plausible explanations like:
"Absolutely! That's a much stronger direction. This ICP has a clear pain point, and your product could be uniquely positioned to solve it."
You do this for four hours and you start feeling like you've done some serious research. You've got a whole product thesis that sounds pretty convincing.
Except when I looked at what I'd come up with, it was nonsense. It wasn't a good startup idea, and it wasn't even good analysis of the space.
I think you can over-AI yourself into a bad place pretty easily. Eventually the AI is trying to please you, or its confidence just gets in the way of reality, and you're in this weird world where everything sounds reasonable, but you're getting further and further away from what's true or useful.
Super interesting - as the era of large token budgets ends and transitions to a more ROI driven approach to AI, context graphs which improve accuracy, completeness, cost will become more mainstream compared to 'oh ill just give it to claude'. @pascalailabs we have a one year head start which means - a) a library of connectors to structured and unstructured data b) a set of agents which build a funds graph with zero human intervention c) delivered headless via MCP, API, to any AI that the fund uses d) with complete auditability at a token level. Publishing some evals soon

An overview of how we think about context graphs at @harvey.
Context graphs are a promising direction for improving agent quality and efficiency. We ran a series of experiments on Legal Agent Bench to evaluate how structured context improves online agent performance.
For each LAB task we evaluated, an agent first reviews each document in its client matter and builds a graph of relevant entities and their relationships – e.g. parties, dates, draft vs. executed status, which versions belong to the same contract.
To evaluate the impact of the graph, we compared the performance of an agent with and without the context graph, using LAB’s standard grading setup. Overall, the agent with the context graph improved rubric pass rate by up to 30% while reducing task cost by up to ~50%.
In some cases the graph led to massive improvements. For example, in one firm-knowledge task, the agent was asked to find the firm’s most recent secured financing and retrieve the executed credit and security agreements as precedents for a new facility.
An agent working from raw files attempted to search through several files sequentially, and looked at many different matters, but ultimately selected the wrong precedent (0% of rubric criteria). With the context graph, the same agent found the relevant matter and its executed agreements immediately (75% of rubric criteria).
We’ll have more to share soon on how we’re building this into Harvey, along with more experiments like this one!
4
357
Seen enough of these new model demos to know - looks great in demos, never works in enterprise

Had early access to Gemini 4 Argon - so I asked for slides on the AI power bottleneck.
It synthesized 8 years of 10-K filings, FERC queue data across all 6 US grid operators, 17 gigawatt cluster buildouts, and a decade of GPU thermal specs.
And I got this interactive deck 🤯
1
75
Mithun M retweeted

What can a hedge fund get from Pascal AI Labs that it can’t get from a frontier model alone?
@Jason put this question to me, on his podcast, @ThisWeeknAI.
The answer comes down to data and context.
What Pascal has, and a frontier model lacks, is a view into the fund’s internal thinking. In fact, a top 10 global hedge fund has shared its entire proprietary data, including IC notes, portfolio data, management meeting notes and internal morning meeting discussions, with our us.
What we do is ingest those internal sources and glue them into a context graph, which becomes the layer our agents work from. So, when an agent pulls signals from licensed market feeds or the open web, it reads them against that fund’s own context.
Because this is a fund’s most sensitive data, the graph sits wherever the fund needs it, either in a VPC in the fund’s own cloud or on-prem in its own data room. Additionally, we take data security very seriously, so we never train any models on a fund’s proprietary data.
Learn more: pascalailabs.com/demo
Instructive read.

#SupremeCourt to hold a special Sunday sitting today to hear a contempt petition against the closure of Metro stations and the cancellation of trains during anti-CEC protests yesterday.
Court will also hear a habeas petition filed by Sr Adv Menaka Guruswamy against the detention of political leaders.
Bench : Justice Joymalya Bagchi and Justice V Mohana @ 10.30 AM.
Follow thread for live updates.

67

Ditto for @pascalailabs

Did you know the Palantir Ontology is an indexed space and a vector store?
You get enterprise search out of the box as you build your Ontology, including searches across links, relationships, how and where objects are used, logic on these objects, and action logs.
Everything is connected and searchable in both business terms and technical logs.
This compounds quickly as you build out your Ontology.
3
130
Crazy times

We spent months investigating the inner working of the EC.
What we found: the majority of the Commission, kept in the dark for almost a year.
Election Commissioners Sukhbir Singh Sandhu and Vivek Joshi objected on record at least 14 times in 10 months, FOUR times on a single day, to decisions taken in the Commission's name without their knowledge.
Here is what they flagged:
(3/10)
indianexpress.com/article/ex…

119
Its abundantly clear that the model is just one part of the AI stack, and potentially not even the most important one - given how fast the model layer is commoditising and unbundling. Value is going to start accruing quickly in domain specific harnessess.

The better the harness, the better the business.
Berkeley published a study this week showing harnesses, the systems that control AI agents, set the price of an answer. The right harness cuts the cost of the same result by 71% without a loss of accuracy.
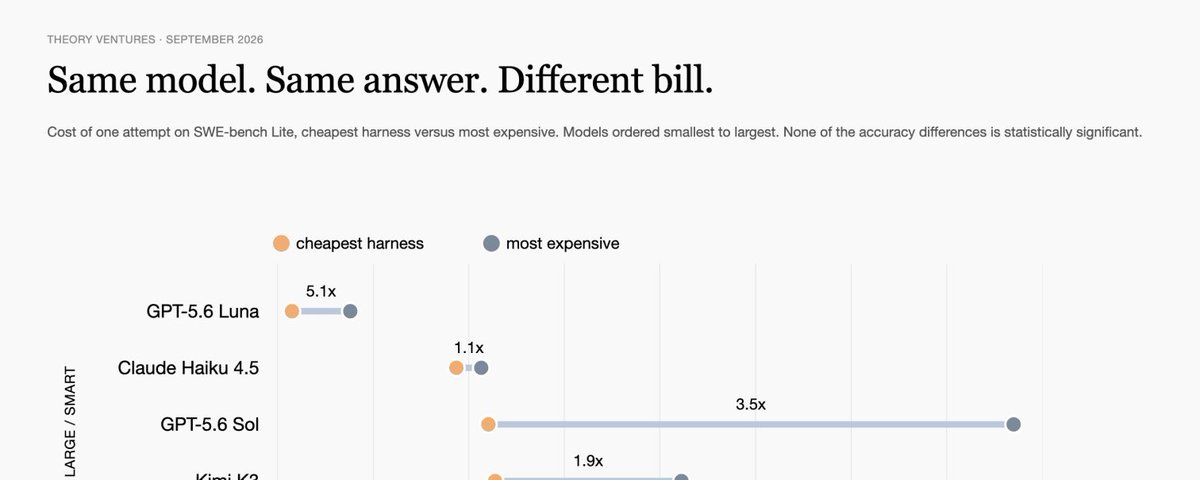
80
Every asset manager in the world will need this for exactly the same reasons. Building the funds intelligence layer @pascalailabs and already powering 500b in AUM.

We recently published an article on how we’re building our own internal AI infrastructure for VC here at Draper. Custom workflows to help our team gather information faster, so they can get back to the true human work in VC: meeting with and being present with founders.
In 1985, I built my deal flow by knocking on the doors of the ten or so venture capitalists that existed and asking them to send me the deals they were declining. I needed to build knowledge so I could build judgment.
Forty years later, the team at Draper Associates built something I could only have dreamed of back then:
-One centralized database that holds a singular record per company that has all our internal data as well as enriched data from outside verified sources like Harmonic
-A machine learning model, trained on 40+ years of successes and passes, that reads the hundreds of deals we get every week and surfaces the best fits directly to the investment team
-A brief on every meeting before we walk in
-Warm intros drafted from a network of 15,000+ contacts
-Answers to any question from our own records in plain English across 400+ portfolio companies (and an extra info assist from our Harmonic API)
The AI/ML infrastructure handles the routine work, but judgment remains human: sitting across from a founder, recognizing a missionary, making the call while the idea still sounds crazy.
Now there are more hours for exactly that.
Read more about how we built this system, philosophically and practically: draper.vc/newsroom/how-we-bu…
80
The labs reaching the edges that practitioners have already reached - how you clean and orchestrate your data to provide context to the model is more important than the model itself. The application layer is important and will continue to remain so

This is notable. DeepSeek, a lab usually first to pioneer novel algorithms and architectures, is saying that at this point, the ROI of improving data quality far exceeds that of working on novel post-training algorithms.
I think this has already been true for some time for non-lab practitioners. If you're doing llm post-training, 80% of your effort should go into looking at your data.
This means:
- Hiring experts to dig through your RL tasks
- Sifting through rollouts and sft data by hand to remove suspicious samples. Make sure all tasks are actually passable.
- Making sure your data is diverse in both difficulty and category.

120
This is the big problem in enterprise. The model companies have shown little inclination to leave anything on the table

Cloud succeeded because AWS did not peep into the internals of Netflix, Slack or Airbnb. “Trust” was earned and kept intact. Same cannot be said about OpenAI and Anthropic or any closed weight AI model provider. (1/2)
102
