
I have a toxic relationship with agent evals
San Francisco Bay Area
Joined July 2017
- Tweets266
- Following396
- Followers122
- Likes1K




Pinned Tweet
Aligning agent evals with your personal judgment is essential for building improvement loops you can trust.
Otherwise, you’ll steer your coding agents towards problems that don’t exist, and miss the ones that do.
A common approach for agent evals is LLM-as-a-Judge or Agent-as-a-Judge that labels your traces. The foundation of the eval is the prompt you define as a rubric. However, most people do not realize the first prompt they create doesn’t cover all cases that their judge will have to evaluate.
Say you want to flag instances where users are frustrated with your agent. What happens if a user is still frustrated after an issue is resolved? If your initial prompt did not include clarification on whether to flag this or not, the judge might or might not label this trace as frustrated. When this ambiguity scales to thousands of traces, you'll be making changes to your agent based on false positives or negatives.
Therefore, having a human in the loop to verify the evals is a natural prereq to creating scalable evals you can trust. This has traditionally looked like the following: hand-label agent traces, compare your labels with the judge’s, and continue iterating on the rubric until the judge aligns with your ground-truth labels.
I work directly with agent engineers who have historically found this tedious and avoided it entirely, but I’d argue that aligning against human-reviewed traces is well worth the time. Labeling even just 10-20 traces will make the quality of your rubric significantly better, allowing you to reliably grade tens of thousands of traces.
I’ve personally seen teams that neglected judge alignment and ended up spending entire sprints’ worth of engineering time making choices based on a false understanding, only to have to do a complete 180 after realizing their evals weren’t giving them accurate insights.
This is why at @JudgmentLabs, we spent a lot of time streamlining this process in our product. Once you provide the ground-truth labels, our agents iteratively refine and backtest the rubric until it matches your labels. The product also reminds you to regularly label new traces so that your judges stay accurate as your agent evolves.
Whether you’re using Judgment Labs or not, aligning your judges’ rubrics will not only improve the quality of their evals, but will eventually help create an eval system you can trust and scale.

Nick Lemoff retweeted

I reached out to @JSCamyre in February after one of the Judgment engineers happened to like one of my linkedin posts
I believed back then that companies would need a dedicated platform to handle the scale of data that agents would produce
Try out what I’ve been a part of for the past 8 months


Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted

Super proud of the team, it's been a grind in the weeks and months leading up to our public launch!! Excited to see what folks build w/ @JudgmentLabs
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted

@andrew_li03 knows the dark arts of having to read traces. a lot of them.

Working on data and evals at Together, I spent a lot of time reading through AI traces. That gave me a real appreciation for how much this data tells us about how AI works, where it fails, and how to improve it.
As long-horizon agents take on more work, the data they generate will far outpace what people can make sense of by hand.
We’re building Judgment to help teams store, process, and analyze that data at scale. Excited to keep building the data infrastructure for a world powered by AI agents.
Nick Lemoff retweeted

second I hopped on the google meet - I knew

I reached out to @JSCamyre in February after one of the Judgment engineers happened to like one of my linkedin posts
I believed back then that companies would need a dedicated platform to handle the scale of data that agents would produce
Try out what I’ve been a part of for the past 8 months
Nick Lemoff retweeted

we've been trialing judgment and it's awesome, highly recommend
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted
The team and product @JudgmentLabs are incredible. We love partnering with them @MonacoGTM
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted

excited to share what ive been working on this past few months!
Judgment Labs is now open for general access ‼️
it's been an insane journey building at the frontier of AI agents. ignore the orange suit at the start (that aint me, trust 😭)
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
we need more fantasy football heads

This is an incredible milestone for the team. We’ve doubled headcount the past year and are growing at a historic rate across all fronts.
If your team is building agents and want to improve them through production data, you can try our platform at judgmentlabs.ai.
And if you’re interested in building the infrastructure for the agent world, send me a dm. We’d love to chat


Nick Lemoff retweeted
Every era of software gets the infra it needs.
Cloud apps got Datadog. You couldn't run prod without knowing what it was doing.
Agents are the next cloud apps. They run in prod and break in prod too. The difference is they generate data faster than any human could ever read it.
That data is how your agent gets better. Most of it ends up in logs nobody opens.
So we're building the infra to actually use it. That's Judgment.
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted

Designed a new website for @JudgmentLabs! Check it out judgmentlabs.ai :)
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted

People are underestimating how much data a world full of agents will produce.
Long-horizon agents doing work everywhere, all the time. Their traces will dwarf the data we're used to handling today.
We've built Judgment for that future.
Today, it's available to everyone.
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted
FREE ICE CREAM TODAY:
11 am - 11:15 pm - 235 Pine St
2 - 4 pm - 515 Alabama St
Thank you to all of our customers and partners who helped us get here.
To celebrate, we’re bringing back the Judgment ice cream truck in SF this Tuesday-Thursday 🍨
Come grab a scoop! partiful.com/e/pBYUGfpk7UgkA…
Nick Lemoff retweeted

the team's been cooking 👀
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted

Working on data and evals at Together, I spent a lot of time reading through AI traces. That gave me a real appreciation for how much this data tells us about how AI works, where it fails, and how to improve it.
As long-horizon agents take on more work, the data they generate will far outpace what people can make sense of by hand.
We’re building Judgment to help teams store, process, and analyze that data at scale. Excited to keep building the data infrastructure for a world powered by AI agents.
Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
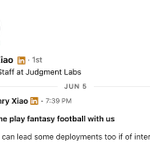
When @henryxiao7 sent me this in June, I didn’t know how serious he was about either offer.
3.5 months into my time at Judgment Labs, he was not joking around.
I’ve worked on 30+ deployments, helping teams build evals they can actually trust for their agents. I’m also 7-0 in our company fantasy league.
Today Judgment is generally available. If you’re building agents, try it out. I’d love to help you get your evals right too.


Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!
Nick Lemoff retweeted

Start today by giving your agents better Judgment.
app.judgmentlabs.ai/
Nick Lemoff retweeted
Connect your agent, send your first traces, and start exploring your data.
docs.judgmentlabs.ai/documen…

Nick Lemoff retweeted
A new prompt can fix one task and break another.
Compare models, prompts, or tools on the same cases, scored by your production Judges. See which cases improve or regress, then use those checks in CI to catch failures before rollout.