

Building continuous diffusion LMs 🚀 Research Intern @Apple MLR; PhD ML @UniofOxford; previously at @MSFTResearch, @EPFL, @imperialcollege
Paris, France
Joined May 2024
- Tweets244
- Following460
- Followers887
- Likes8K


Pinned Tweet
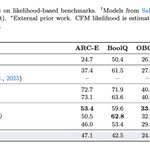
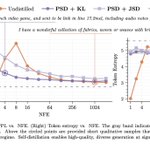
Continuous Diffusion LMs went from niche to contender this year, but the recipe is shaky: why self-conditioning? How to embed tokens? 🤨
Our new work takes your one-hot flow from 4% to 50% on TinyGSM without self-conditioning, and explores the design space of CDLMs. 🔥🚀 (1/6)
Oscar Davis retweeted

🔥 Diffusion LMs promise what autoregressive models can’t: fixing their mistakes.
But new ones often change the noise and the sampler at once. Which matters?
We tested it on the hypersphere. Noise: 0.8 points. Sampler: 25.
We introduce Spherical Brownian Diffusion 🌐 👇🧵
Oscar Davis retweeted

🎉 Excited to bring our book The Principles of Diffusion Models to @NeurIPSConf 2026 as a tutorial—this time, all about diffusion LLMs! 🚀
🔹 How do ideas from continuous diffusion extend to language generation?
🔹 What are the latest advances and open frontiers in diffusion LLMs?
From foundational principles to cutting-edge research. Stay tuned!
📆 Mon, Dec 7, 9 AM AEDT
📍 TikTok Ent Centre (Sydney, Australia)
w/ organizers @ssahoo_ @mittu1204 @StefanoErmon

🎊 Excited to give a tutorial on diffusion LLMs at @NeurIPSConf 2026 with @StefanoErmon @JCJesseLai @mittu1204
📆 Mon, Dec 7, 9 AM AEDT
📍 TikTok Ent Centre (Sydney, Australia)
Topics covered:
> A beginner friendly introduction to diffusion-LLMs
> Designing frontier diffusion-LLMs
> Using Continuous diffusion for LLMs
Oscar Davis retweeted

Excited to announce the follow-up to our NeurIPS 2026 Oral: Improved Training of Strong Stochastic Flow Maps!
We improve the training of SSFMs by unlocking derivative-based losses!
Joint work with @antoniofrancaib @rmincam @ChristianKoke @Niklas_TR and @AlexanderTong7
Oscar Davis retweeted

did a group presentation today with @3blue1brown's manim style transitions. Sharing the template for anyone to build upon
Brought to life with @NarekMaloyan's manim-web + reveal.js + claude + codex
view template: slides.ramith.fyi
view repo: github.com/ramithuh/protein-…
Oscar Davis retweeted

Can a language model be based purely on self-conditioning? 🤔
Yes! Meet LAW 👋 (a.k.a. Loopholing All the Way!)
🧵1/8
Oscar Davis retweeted

1/9 Current optimizers are static during training. What if the optimizer could think and react while the network trains?
We let an agent watch the training dynamics and rewrite the optimizer's source code as training goes: a reactive optimizer.
In every language and image setting we tried that has no tuned recipe, it matches or beats the best recipe one can one-shot, and it guards against loss spikes and overfitting by itself. In the near future, optimization decisions may belong to agents, not humans.
📝 xingjianbai.com/reactive-opt…
💻 Try it on your task: github.com/xingjian-bai/opal
🧵
Oscar Davis retweeted

Can flow language models scale to billions of parameters and handle real generative tasks?
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Oscar Davis retweeted

⁉️ Is model distillation of frontier models like DeepSeek-R1 and Opus 4.6 traceable to how robust each model's distilled family is 🤔?
We find evidence of a completely new phenomenon that we term "Vulnerability Monoculture," where distilled models inherit the security risks of their teacher 😱
🚨 Check out our new preprint where we expose the Systemic Adversarial Robustness (SAR) of open-source frontier models
Punchline:
We show that models distilled from DeepSeek-R1 and Opus 4.6 are systemically less robust! In some cases, 30- 40% collectively less robust 🚨🚨🚨🚨!!!!
📝Blog: leoelm.github.io/blogs/syste…
📄Paper: arxiv.org/abs/2610.27353
w/ @leo_elm @LSzpruch @matthew_wicker
🧵1/7
Oscar Davis retweeted

One fun part of this project was @nscorley @RafiBrent @maxkazman and me sitting late in the office, testing out some ideas in the recurrence space and a week later seeing a paper that echoes our findings. Go checkout @osclsd's recent work, super cool stuff!

Super exciting to see the incredible advances of diffusion for bio too. Of course, with people like @DidiKieran, it's going to keep improving at incredible rates.
Fun to see that self-conditioning is also falling in the protein space! Its days are numbered...

Super exciting to see the incredible advances of diffusion for bio too. Of course, with people like @DidiKieran, it's going to keep improving at incredible rates.
Fun to see that self-conditioning is also falling in the protein space! Its days are numbered...

Avengers assemble: 1 year BakerLab + NVIDIA GenAIR = 🔥 rfd4-proteina.org
Presenting RFD4-Proteina, our latest protein design model, significantly better and faster than everything we compared against, both in silico and in the lab! 1/30
Oscar Davis retweeted

When training agents, you add a length penalty for exceeding the budget/effort level. The fun thing is, every lab (Deepseek, Kimi, ...) uses a different one. We compare which works best in our new paper.
📄 arxiv.org/abs/2610.28409
🧵1/9

Oscar Davis retweeted
🚨 Do you always have multiple rewards but don't know how to steer towards an expensive true reward?
Don't fret, friends; we have the paper for you!
📣 Steered Not Stirred: Effective Reward Tilting using Surrogate Reward Mixing, led by the incredible @alec_sargood28 and team
The Martini Algorithm 🍸
From 007: everyone now has a license to tilt 🤵
📜 Paper: arxiv.org/abs/2610.25502
🔗 Blog: alecsargood.github.io/martin…


🚨Can we steer a generative model towards a gold reward we can't evaluate at inference time? Introducing 🍸 MARTINI — Steered Not Stirred🍸
We combine multiple imperfect reward surrogates from offline values OR preferences to steer without querying the oracle.
Huge shout out to our dream team, brilliantly led by @alec_sargood28, with stellar work from @olivgallup and Noam Ghenassia, plus key input from Georg Maierhofer and @pduckw. A true honour to co-supervise with @bose_joey.
📄 Paper: arxiv.org/abs/2610.25502
🌐 Blog: alecsargood.github.io/martin…
🧵1/10
Oscar Davis retweeted
🚨 New Paper Alert, 🎤 Accepted for an oral presentation at the NeurIPS 2026 STODY workshop!
📣 Introducing: Normalizing Flow Maps (NFM): Combining few-step transport from Flow maps with tractable likelihoods from Normalizing Flows.
This is my first work with my first crop of new PhD students, @francescoshox and @tim_hitge, who genuinely knocked this project out of the park.
📄 Paper: arxiv.org/abs/2610.22711
📝 Blog: the-bose-lab.github.io/norma…
💻 Code: github.com/francescoshox/Nor…
🧵
1/8
Oscar Davis retweeted

More progress on CDLMs: self-conditioning has always been a bit of a crutch, DoubleCat/SemiCat seems to be a principled way to get rid of it🎉
Oscar Davis retweeted

oscar leave some work for the rest of us 😅
very cool idea and exciting to see more principled explorations of self conditioning!
Oscar Davis retweeted

Introducing RSI-Inference Bench from 🍎 Apple ML Research
🌐 rsi-inference.com
💻 github.com/apple-aiml-resear…
Can AI agents improve the systems that run AI?
We spent $100K API tokens, 50K GPU hours to find out. We built environments and benchmark from real-world #vLLM and #SGLang tasks, covering the full lifecycle of model inference engineering:
🚀 Day-0 Model Support
⚡ Inference Optimization
🔧 Bug Fix
→ Unsaturated: best agent at 26.7% pass@1
→ Comprehensive coverage of the inference stack
→ Verifiable rewards: binary and continuous
Watch the video to find out more!

Oscar Davis retweeted

Introducing Langevin Flow Maps
TLDR: Neural Network Potentials that learn their own stochastic pathwise solution for faster simulation.
- Transferable across molecular systems.
- Transition dynamics are preserved.
- No trajectory data are required.
Work together with @sgmccallum, supervised by @AlexanderTong7, and @JamesFosterBath.
Arxiv: arxiv.org/abs/2610.05998
Data: huggingface.co/datasets/nikl…
Code: github.com/sammccallum/lfm
Oscar Davis retweeted

Introducing SCALLOP 💜 Our new paper accepted at NeurIPS 2026 🐨
🚀 A scalable, efficient way to train few-step likelihood-available flow maps, enabling effective Boltzmann generation!
📽️ project page: tonyauyeung.github.io/scallo…
🔗 paper: arxiv.org/pdf/2606.29110