

AI analysis and phenomenology - user research, policy + comms. we help operationalize AI by helping you understand its failure modes.
Toronto+
Joined July 2012
- Tweets15.3K
- Following2.7K
- Followers2.8K
- Likes6.5K




patternpulse retweeted

wrote about "Black October," the PHP vulnerability, and the AI-fueled dread and panic I'm seeing among almost all of the cybersecurity experts I've ever known:
404media.co/php2shell-black-…


patternpulse retweeted

Last night, hundreds of people joined us and @MorePerfectUS at Webster Hall to hear from policy leaders, organizers, artists, and journalists about an alternate trajectory for the future of AI.
Read remarks from @NYCMayor and @linamkhan via @Gizmodo 👇
gizmodo.com/zohran-mamdani-b…

👀

We found DeepSeek V4.1 Flash 1017 beats GPT 6 Sol on our multi-step offensive cybersecurity task. Sol was tested via the Daybreak trusted access program.
We have been building a cybersecurity benchmark based on simulated corporate networks. This is a valuable indicator for the cyber-risk a model poses if in the hands of a bad actor. We plan to make the full evaluation public in the coming weeks but wanted to share our first immediate finding here.

RT @Tim_Dettmers: This is a very big deal. DeepSeeks inference system is on par with OpenAIs stack and better what Anthropic is running (at…
This quoted post is unavailable.
This Week in AI: Things Can Fall Apart Over Demand b2bnn.com/2026/10/this-week-… via @B2BNewsNetwork

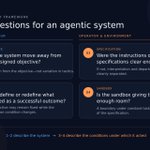
Interesting. Very interesting. What is agentic AI, anyway. All harness, no model?!

Google just open-sourced Harness².
(turn any harness into a self-improving system)
a harness is everything wrapped around the model, like the system prompt, tools, memory, skills, and subagents. today a person designs it once, and the agent runs every new task with that same fixed setup.
Harness² lets the agent refine that setup for each new task on its own, with the model weights left untouched.
on every task, the agent proposes edits to its harness, runs a few candidate versions, and composes a better harness by comparing how those runs behaved.
because it learns from the differences between runs, it needs no correct answer or grader for the task.
that covers a single task. Harness² also carries what it learns from one task into the next.
after each task, it saves the harness it settled on along with the lessons that held up across the runs. the next time it refines a harness, it starts from those notes instead of from scratch.
this means every finished task makes the next round of edits more informed.
Google tested this with Gemini 3.5 Flash and GLM-5 on legal, office, and professional work benchmarks. one round of edits was enough to beat their original harnesses, and giving the agent more rounds pushed scores higher.
those extra rounds can go wide or deep. the agent either tries several candidate harnesses at once or keeps refining a single one step by step, using OpenCode or Codex to carry out the work.
you can find the Harness² repo here: github.com/google-research/h…
I wrote about a similar idea for agents already running in production, where the harness should repair itself after a failure instead of waiting for someone to debug the trace by hand.
that piece walks through how @Cometml's Opik (open-source) closes this loop, going from a failing trace to a proposed fix to a regression test that stops the same failure from coming back. it's quoted below.


👀

This is a great paper on how we can stop Long Horizon Agents from getting stupid every time their context resets.
While building benchmark Long Horizon Agents, an agent works fine for a while, eats up its window, summarizes the last twenty steps into a neat paragraph to free up room, and immediately gets stupid.
It forgets tiny environment quirks, loses track of where it found a specific variable, and starts retrying the exact same broken tool call over and over.
Text summaries just leak way too much signal.
What these authors did is treat compaction essentially like a residual connection along the sequence dimension.
Instead of forcing a text summary to carry the whole load, they train a separate small memory network to produce a short sequence of soft tokens that get tacked on right after the summary checkpoint.
The base model (which stays frozen) gets both.
The text handles the readable narrative, while the soft residual tokens fill back in the missing latent context so the model can continue generating almost as if it never lost the full history.
The empirical side is what actually sold me, though.
They’re matching full-context joint scores on SummHay using barely 5% of the input positions.
And when they ran it on harder agent benchmarks like BrowseComp and Terminal-Bench with models like Qwen and GLM, those endless repetitive tool loops just plummeted.
I love the cognitive framing they open with.
Humans have laughably small active working memory, but we don't need a live transcript of the last month in our heads to write code or browse the web.
Our brains use tiny cues to index into deeper, stored representations.
Bringing that mechanism to context management feels way healthier than just mindlessly blowing up context lengths forever.
Definitely worth a read if you're dealing with agent memory: arxiv.org/pdf/2610.11287

patternpulse retweeted

Human-in-the-loop (HITL) is widely recommended for oversight & safety, yet current AI agent design requires humans to keep up with unreasonable volume & complexity, promotes fatigue & disengagement, and degrades the very humans skills it relies on. 1/ arxiv.org/abs/2608.23642

patternpulse retweeted

Citigroup now bars third-party AI agents from logging into customer accounts or moving money inside its digital banking platforms, according to the Financial Times.
Bank of America has imposed similar limits, joining JPMorgan Chase, which is restricting outside AI agents after Jamie Dimon warned that thousands of “rogue agents” could otherwise operate inside the bank.
The deeper threat is to bank funding, since agents comparing rates could move cash from checking accounts paying about 0.1% into fintech accounts paying 3.3% to 5%.
JPMorgan, Bank of America and Wells Fargo hold $1.6T in non-interest deposits, and paying 3% on that money would cost $47B a year, close to half their combined annual earnings.

patternpulse retweeted

👀👀👀

Turns out AI can cause more problems than it solves. 36% of AI execs at companies with $1B+ in annual rev reported an AI incident that led to data loss, financial damage, brand damage or operational disruptions. Companies are now limiting employee AI usage.theguardian.com/technology/2…

patternpulse retweeted

"Employees described bots that set unreasonable standards for human workers while introducing a host of their own inefficiencies and errors"
Employers who let people being chased around by bots are violating their duty of care.
theguardian.com/technology/2…
patternpulse retweeted

🚨 IMPORTANT: The EU's first AI standard has been published in the Official Journal of the European Union! Here’s what companies need to know:
The standard EN 18286:2026, “Artificial intelligence - Quality management system for EU AI Act regulatory purposes,” specifies requirements and provides guidance for defining, implementing, and maintaining a quality management system for organizations that provide high-risk AI systems.
The European standardization organizations CEN and CENELEC had already published the details of this harmonized standard earlier, but the European Commission still had to formally assess whether it met the AI Act’s intended objectives and legal requirements.
That assessment has now been completed, as this standard was published today in the Official Journal of the EU.
In practice, companies can apply this standard and benefit from a presumption of conformity with the EU AI Act’s quality management system requirements, as established in Article 17(1) points “a” through “m.”
As a reminder, this article will come into force on December 2, 2027 for high-risk AI systems under Annex III and on August 2, 2028 for high-risk AI systems under Annex I, according to Article 113(c).
This is the first European standard on AI to be published in the EU Official Journal. Additional standards covering the following areas are also expected to be published:
- risk management
- governance and quality of datasets
- record keeping
- transparency
- human oversight
- accuracy
- robustness
- cybersecurity
- quality management
- conformity assessment
This is great news for everyone. The EU AI Act's standards are voluntary, but they will help increase legal certainty, foster innovation, standardize legal requirements, and accelerate compliance.
However, the challenges in AI are only beginning, and every company developing or deploying AI should focus on strengthening its AI governance and safety practices.
I will keep you posted.
👉 READ my full article (and join my newsletter's 102,200+ subscribers) below.

NEW Guest Column: Unlocking the agentic advantage: How to transform business travel with AI agents b2bnn.com/2026/10/unlocking-… by @SAPConcur Canada Managing Director Brian Cardoso, today on @B2BNewsNetwork

patternpulse retweeted

Anthropic said its experiments suggested small AI models may be months away from being capable enough to self-replicate on commercial internet-of-things devices, such as smart ovens and off-brand Android TV boxes reut.rs/4e3tp8k

⭐️
⭐️🤖 NEW by me:
The Great AI Fragmentation: When Models Become Abundant, Skill Becomes Differentiated Power b2bnn.com/2026/10/the-great-…
long weekend eve thinking on @B2BNewsNetwork

patternpulse retweeted
I'm incredibly excited and deeply depressed:
Pretty much all the leading Chinese AI and robotics companies will be at @WebSummit in Lisbon next month.
The future of tech appears increasingly Chinese.
Western innovation is still happening, but it's slower and far more expensive than what's broadly happening in China.
Web Summit has always tried to be a window into the future of tech. That future for many years was Western, mostly American, with a light sprinkling of European innovation.
It now pains me to see how increasingly irrelevant Europe and the United States are. I feel like almost everyone is in total denial.
Too many western startups and investors have retreated to the safety of their own podcasts, agitated by journalists who "just don't get it" with pesky questions.
US robotics startups produce Hollywood level launch videos, but then years later they still can't produce an actual working robot.
Like WTF is going on!
In the West, Tech used to be about tech. But now it's about narrative.
Which, in the west, amounts to telling increasingly bullshit stories in the hope no notices you're mostly full of shit. And in reality some Chinese startups, with almost no funding, are eating your dinner.
Am I wrong? Like what exactly is going on. I just feel the west is in some weird Soviet-era denial that we're being surpassed by a new system. And we have no answers, no solutions...