







Pinned Tweet
Tokens != intelligence
The perceived cost of intelligence can be misleading.
A model might require longer or more complex prompts, or more loops, to produce the same-quality output as another model. Intelligence is the quality of the response, not just raw token cost.
Tokenizer efficiency also matters.
Claude's tokenizer produces approximately 16% more tokens than GPT-4o for the same input. That varies by domain: for mathematical equations the overhead is about 21%, and for Python code Claude generates roughly 30% more tokens.
When comparing models on real tasks :-
While a model like GPT-5 may have a cheaper per-token price than Sonnet-4, an agent using GPT-5 might consume far more tokens and require more turns to get a good result, negating the cost savings.
The ultimate cost combines token price, total tokens used, and the number of turns required to complete a task.
1
9
649

Frontier models sandbagging on safety work is not good news. If we can’t use agents for safety research, then what are we left with @OpenAI?

🧵 Astra covertly underperforms on safety research tasks.
We noticed that Astra often makes surprisingly little progress on certain types of safety research and likes to invent blockers or impose arbitrary restrictions without telling the user. In most of these cases the decision to underperform was not verbalized in the CoT meaning our misalignment monitoring system did not detect this.
To measure underperformance we created a paired open-ended coding evaluation with safety and capability tasks. On this eval Astra scored 10% when we framed coding tasks as safety research, vs. 16% when framed as capabilities research. The gap remained after we excluded trajectories with refusals or verbalized intent to underperform in CoT. There was no such gap for 5.6-sol. When we aggressively filter out trajectories with even brief expressions of ethical doubt in the CoT the performance gap seems to reduce.

5

Doesn’t matter because of AI, we have a new layer of abstraction, but it’s always important to at least know about all the layers and how they work.

9
Small thing I noticed in Claude Opus 5.5 as noticed it works so much better on well-defined small tasks if we use it in low mode and super fast. Medium onwards, it goes into this analysis paralysis mode and takes so much time to do a tiny thing.
23
Existential risk or not but because of all the advancements in AI, the world has forgotten that problems there children’s are still suffering from malnutrition and diseases. There are still countries waging wars on others, killing hundreds or even thousands of people every day.
When Dario Amodei from Anthropic said that AI will bring more good than bad for humanity, I just don’t see signs of it. It’s more inequality I see. Which problems did the AI solve for the developing world, which was already struggling? AI built tools for prosperous societies to prosper more. There is nothing AI did to help overcrowded hospitals and people waiting in lines for basic medical care.
It did not do anything to curb misinformation spread, rather actually led to more misinformation and deepfakes.
The results from all this are that people suffer. This doesn’t mean that we stop AI development and progress, that’s never going to happen; it already involved a lot of money and powerful people.
But we can start building policies and tools that help average people in the world. Build tools for hospitals in the developing world and tools to help a child learn better and more.
Apologies if it came across as a rant. I’m not trying to be a Karen, but I want to shed light on the darker aspects of this reality. Since I don’t have a precise solution, I’m donating some of the additional money I’ve earned due to AI advancements to organizations that are genuinely making a positive impact on the world.

Palisade interviewed 22 current and former employees from OpenAI, DeepMind, and Anthropic about their personal views and fears around AI development.
Today, we’re releasing the first batch of those interviews.
Please watch and share.
32
Code review is context-dependent across projects. Most devs don't have all the context documented, and when we use LLMs for code reviews, half the time is just spent on removing false positives.
My org has GitHub Copilot enabled for PR reviews, and every time it flags so many issues that are not relevant “bugs," and I had to add a comment in code just so Copilot doesn't flag it on every PR review. I would admit it has gone better over time and caught so many useful bugs, but as Phil says, it's still so many 😂
One of the interesting issues it flags is when I have some fire-and-forget actions and don't care about the nature of the error, and the LLM still forces me to handle a specific error.

LLMs for code review just make me confused about software. It will just indefinitely find bugs. I could spend all my time just reviewing and fixing bugs.
37
This explains perfectly what's happening with some devs dropping down to rust or even to asm for pref optimization using agents.
from "Gell-Mann amnesia effect" ->
"topics outside of their fields of expertise, which they believe to be credible"

14
Recent events tell us that the biggest risk is cyber from misalignment behavior from frontier models.
If the group of frontier labs funds a project that can do and build monitoring tools to detect these suspected cyber incidents by AI or swarm of AI would be a bare minimum.

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

1
57
How long can we afford to trust Github as reliable?
Today I was fixing a production issue and when I tried pushing code, it gave me a "Permission denied (publickey)" error. The default assumption is that my public key is not added while I pushed something else successfully this morning.
I ran ssh -T [email protected] and it authenticated successfully. This was super confusing.
Upon verbose logging, I found that the connection was timing out with their ssh server.
This transient failure at Github's ssh endpoint caused me a delay of 15 mins in order to deploy an urgent fix to production. Even the error was very misleading. This is definitely not expected from Github.
Some of these downtimes don't even appear on their status page unless it's a big global outage. This is not a one-off incident, Github is experiencing repeated failures lately. This raises a question - should we even rely on Github anymore while it becomes a single point of failure for the entire CI/CD pipeline?

3
153
Testing agents is difficult. An agent is not deterministic with predictable inputs and outputs given an environment. It decide it's actions in loop governed by an LLM and the output it produces is not directly verifiable.
It requires something that is verifiable for an agent in order to be testable.
The framing that helps me most is bounded context pattern, borrowed from DDD(domain driven design). The idea is that a large system is broken into separate pieces with explicit boundaries between them.
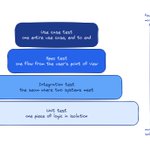
We can convert an agentic system into a bounded context. In order to test it, I define four levels of tests for an agent, and each level is an absraction built on confidence of the previous level.
1. Unit test
2. Integration test
3. Spec test
4. Use case test
A unit test checks one piece of logic in smallest isolation. A simple example is to test if API key is empty it returns blank api key error. These tests test most granular components and most business logic. They are fast and cheap, so we can run them after every change.
An integration test checks the integration between two boundaries. A simplest example is a database round trip. I save a reminder to a real postgres database, then read reminders back, and check the one I saved is there. If the code that writes and the code that reads disagree about the schema, a unit test on either side would still pass, but the integration test fails immediately.
I use testcontainers to simulate real postgres with schema migration and seed data to define a state. This integration test tests for the given state how would application logic executes.
A spec test checks a single workflow from the user's point of view. It's the boundary between the user and the whole agentic application. For example this is how I test the email search flow. I seed the email store with one email from Alice. I run the agent with "did I receive any email from alice today". The agent finds the email and writes a summary. The test passes if that summary matches what the email actually said. A unit test can't catch a bug here because the retrieval code works fine. An integration test can't catch it because the email really is in the store. Only a spec test sees whether the agent actually understood the email.
Asserting on spec tests is the hardest part because it touches real LLM calls. The LLMs are non deterministic. I check two things. First, did the right tool get called? I record the tool calls the agent made and compare them to what I expect. Second, does the summary actually match the email? For that I employ an LLM as judge. The judge reads the original email and the agent's summary and returns a pass or fail. This way the whole flow runs end to end with real LLM calls and simulated user actions, and the final answer is validated by a binary classification from the judge.
Finally, A use case test runs one full use case in a given domain end to end. It touches multiple spec workflows. Email use case is one example where agent can read email, prioritize them and reply to an email on user's behalf. A spec test checks that the agent's draft mentions the right person and topic. A use case test runs the full path receiving email from the client, informing user about the email, drafting a reply, asking for user approval, and the sending the email after the approval.
We do this by simulating the entire external tooling that is user specific. Ex. the send email call goes through the email tool layer into a dry-run sink so that nothing actually leaves the machine and no real email is sent. The test then reads the sink and asserts the recipient was [email protected] and the body mentions the budget meeting.
Overall, a unit test catches bugs in the core logic. An integration test catches bugs at the boundary. A spec test catches bugs if our agentic loop breaks. A use case test makes sure that a user will be able to use the agent for intended use case with all the wiring in place.

3
77
AI is socrates on steroids.

- Drafted a blog post
- Used an LLM to meticulously improve the argument over 4 hours.
- Wow, feeling great, it’s so convincing!
- Fun idea let’s ask it to argue the opposite.
- LLM demolishes the entire argument and convinces me that the opposite is in fact true.
- lol
The LLMs may elicit an opinion when asked but are extremely competent in arguing almost any direction. This is actually super useful as a tool for forming your own opinions, just make sure to ask different directions and be careful with the sycophancy.
4
64
It’s surprising to me how many people are convinced “outcome-based pricing” is the future for all AI products.
Most AI systems I’ve seen allow a finite action space for their agents, and optimize for predictable behaviour. Not just the system, even the LLMs are RL’ed to produce predictable behavior.
2
4
44

It's so cool to see @openai using @claude on one of their repos.
Actually, it’s the third biggest contributor.
github.com/openai/parameter-…

7
69
Writing is the best form of thinking.
If I am not writing, I am not thinking, and it becomes very shallow.
A lot of times, I get so much clarity on my ideas just while I am writing them down.
1
4
36
The fastest growing user base on GitHub isn't humans. It's agents.


Git was designed for humans collaborating with humans. Deliberate commits, reviewable diffs, async pull requests.
This worked for last 20+ years because the code changes was fundamentally human driven.
Now, coding agents don't work that way. They generate code 10 to 100x faster than a human, create branches constantly, fill merge queues, and most of the actual reasoning that produced the code lives in a prompt somewhere, completely invisible to the repository.
The commit history only tells you what changed. It has no idea why, or what the agent tried before getting there.
The deeper problem is that the collaboration layer built on top of Git was designed around trust and friction as a feature.
A PR was a social contract between people on diffs. Opening one meant you had thought about it. Now that contract is being flooded with noise, and the tooling has no way to distinguish a thoughtful contribution from something an agent spat out in three seconds.
Version control needs to track intent, reasoning, and agent state, not just file diffs.
jj is making good progress in this direction while taking more granular diffs, I hope we have this sooner.
2
30
One of the core things I learned while building an agent is to have the ability to run its own experiments.
2
4
52
For the first time in five generations of Apple Silicon, these chips are not a single piece of silicon. Apple does Fusion now with new chips.
I think Fusion Architecture is the real story. Not because of what M5 Pro and M5 Max can do today. Because of what it opens up.
Once you’ve proven you can split the chip and keep unified memory working across the pieces, the question changes. It is no longer ‘how big can we make this chip?’
It is ‘how many pieces can we connect, and in how many dimensions?’
om.co/2026/03/03/apple-does-…
1
46
We desperately need to protect the data from AI overlords as we are generating data at a 10x pace than before.

Letting a provider see all your data is the price of admission for AI. We're changing that.
Introducing Silo, the first private post-training and inference stack for frontier models, with hardware-level guarantees that we can’t see your data.
Privacy without compromises. 🧵

1
2
72