
We've retired the site, but we're still active professionally.
U.S.A.
Joined August 2012
- Tweets68
- Following69
- Followers5.1K
- Likes28

Red Team Journal retweeted

The 'claudia' guy is just unreal at getting creativity out of AI. This is ~$200 and 9 hours. The "meet" instead of "eat" in the chorus is clever, chorus is very catchy, but the video design (esp. at chorus) is unique. If you don't see this as sci-fi, I don't know what to say 1/2


We were going to end this thread here. Then we wondered whether that's what the adversary wanted.
81
An adversary who understands how we recognize attacks may be able to shape what we see, what we dismiss, and what we investigate.
73
Suppose we learn how adversaries manipulate our responses and build that knowledge into our threat models, detection systems, and defensive planning.
How would we recognize an attack designed to manipulate the way we recognize attacks?
1
150
An attacker who anticipates how we’ll adapt may try to steer that adaptation. Some attacks could be worth making for the changes they cause us to make, even if we stop the intrusion.
121
We’re starting to see what agentic AI changes for attackers. What’s harder to see is how we’ll change in response, and what opportunities our adaptations will create for them.
1
179
Red Team Journal retweeted

Every time we have a new model, I run the same simple prompt on all my projects:
"Read this entire project and find everything that’s broken, inconsistent, inefficient, or no longer needed. Fix what you’re sure about and list the rest for me to review."
highly recommend trying
Red Team Journal retweeted

We’re witnessing an exponential surge in capabilities, and the pop cyber takes today are:
- phishing works
- don’t put it on the internet
- patch the cve
We have cyber superweapons, and an opportunity to contribute and harden? Best we can come up with is tepid takes that didn’t even work 20 years ago?
Your architecture should be secure by design, your identities should be defined with boundaries, your reviews should be automated, your patches auto-generated and vetted, all your alerts continuously monitored and tweaked, continuous threat modeling and verifying assumptions and reviewing identity-based access etc.
And all we can say is take it off the internet and patch the vuln and don’t click the link? 0 innovation
Red Team Journal retweeted
I think there is way too much concern expressed about verification of AI output in everyday work due to a risk of factual errors.
It used to be true, but data on more recent models suggest they beat human experts, including PhD specialists, in finding facts and checking claims.


Red Team Journal retweeted

So much “wait until the agent swarms are stealthy” talk. They’re effective today because they do a massive amount of noisy testing and iterate on the results. Making them stealthier means sacrificing coverage.
That tradeoff has always existed. This is the same pentest vs. red team conversation we’ve been having for years. You get coverage or stealth you don't get both.
Red Team Journal retweeted

Almost half of all breaches now involve a third party vendor/partner

Some of the biggest openings in security have nothing to do with patching
How breaches began, per a 2026 report:
- 31% exploited a vulnerability
- 35% used phishing, stolen logins or impersonation scams
And nearly half now involve a vendor or partner, up 3x since 2024
Full piece from a16z's Asaf Ezra and Steph Zhang on six cybersecurity companies worth building: a16z.news/p/defense-in-depth…

Red Team Journal retweeted

This is the most correct take I have heard on the future of cyber.
It blows me away how this is so lost on security teams today. We have a long way to go until this concept is grokked.
None of your quarterly planning, DAST scans, and SOC can stop a swarm. None of it.

Calif CEO @XorNinja says cybersecurity has no playbook for stopping 1,000 AI agents attacking a network simultaneously, even if defenders can detect them:
"Attackers always adapt faster and earlier than defenders. Even the AI companies themselves don't have great security."
"Imagine you enter a cage fight, but you are blindfolded and the other guy stay in the dark, and every once in a while they would come out and punch you and then disappear."
"How could you win that fight?"
"I was at Google and that's basically the mantra at Google. In security you have three things: prevention, detection, and response. And Google accept that prevention gonna fail at scale."
"You can detect them, but does it help you if you find that there's maybe a thousand agents hacking you right now inside your network? How can you contain them without a full shutdown of your system?"
"This actually requires defense to come up with a new paradigm. I haven't seen anybody come up with a good idea here. We're not there yet."
@calif_io
Red Team Journal retweeted

First ever post from Sam McCandlish. Anthropic co-founder and Chief Architect, leads pretraining and RL. He says Anthropic is preparing to share a report on their internal acceleration. Bet on this being the announcement they have hit the 2x Responsible Scaling Policy threshold.

I'm Sam, one of Anthropic's co-founders, and I lead much of our safety work. I'm going to have more to share on that work over the coming months.
I thought I'd start by sharing a few thoughts on the latest report from @METR_Evals.
The speed of progress in model capabilities is one of the most important questions in AI safety, and METR’s work here provides the public with an independent, external view into how this is happening inside Anthropic. I’ll talk more about some of the details below, but first some context for those new to this work.
How quickly AI progress is accelerating has many important safety implications, since it determines how quickly the risks from advanced models increase. But, because most research happens within the frontier labs, it’s difficult for external observers and policy makers to get a strong sense of what that rate is. We kicked off the process with METR that led to this report earlier in the year, in anticipation of progress continuing to accelerate.
For this report, we gave METR access to a range of sensitive internal data, including benchmark scores for unreleased models, estimates of how models are progressing, and interviews with our researchers. They had complete independence to form their own conclusions.
Many of their conclusions match my own. AI is speeding up our research, but it’s hard to say exactly how much. While they conclude AI can't yet make the most important contributions to model training on its own, they think the pace of development could, by default, accelerate further.
This work began well before and is separate from the embedded third-party evaluators that are part of our commitment to pacing the frontier, but it’s a good illustration of why we think evaluators are a good idea. The more access reviewers have, the clearer a picture they can form of the situation and the better-positioned they are to highlight situations like this one.
We redacted a lot, and I accept that this makes it harder for others to check METR’s work. But we determined that sharing exactly what is driving the speedup isn’t the right thing to do, both because it’s commercially sensitive and because it risks handing out a roadmap for others to go faster. That would make the risks METR is worried about worse. That’s a tradeoff. I think we made the right call, though we’re continuing to assess the pros and cons here.
In the coming weeks, we plan to share a report with our own analysis of the speed of AI progress within Anthropic, including where we stand against our Responsible Scaling Policy, plus new steps we’re taking to strengthen our safety and security practices as AI keeps improving quickly.
Red Team Journal retweeted

I am a broken record about this, but: frontier agents are not going to be a purely digital phenomenon for much longer. They will be able to use anything in the physical world that can be actuated programmatically—first competently, then at human-expert level, then superhuman. By and large, we probably won’t need specialist models; the frontier models will just do it. If your model of the future hinges on physical AI happening “for real” many years into the future, I think you will be in for a surprise.

i went to bed and asked claude to paint an autumn tree overnight.
at around 4am, it realised that it didn't have some shades -- so it stopped and titrated its own paint: diluting red, sienna and madder step by step on a second palette, then measuring each pocket from a photo.
woke up to this beautiful watercolor painting. 303 brush marks, took about 4.5 hours 🍂 (still working on the speed)
Red Team Journal retweeted

A lot of cybersecurity problems are really organizational dysfunction problems hidden behind a layer of tech. No amount of AI tokens can fix that.
Feel free to send this post to your boss.
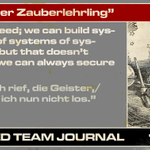
It seems like a good time to bring back red teaming "law" 40 ("Der Zauberlehrling").

ALT Red Team Journal Red Teaming "Law" 40 ("Der Zauberlehrling"): Take heed; we can build systems of systems of systems, but that doesn’t mean we can always secure them. “Die ich rief, die Geister,/ Werd’ ich nun nicht los.”
Red Team Journal retweeted

Fun fact:
You don't need a threat hunting program if adversaries can achieve their goals in a few hours. Maybe hire some storytellers, @anton_chuvakin? I bet it would be fun 😅
medium.com/anton-on-security…


