

Content Creator & Researcher | Ex Google @CELE8EX | Dm open ✉️
Ai
Joined December 2021
- Tweets10.9K
- Following838
- Followers15.3K
- Likes51.8K


DAMN. YOUR CODING AGENT STILL CAN'T OPEN AN ISSUE?
Claude Code at $20/month. every call the agent wastes reaching for a tool it can't grab eats your plan limit for nothing
one config line per server replaces a custom integration. 476k stars across the ten. markitdown alone holds 192k
10 GitHub repos that give your coding agent real tools:
01 awesome-mcp-servers → curated directory of MCP servers sorted by job. search here before wasting a weekend on something that already exists
github.com/punkpeye/awesome-…
02 servers → official reference implementations of the protocol. copy a working server instead of reading the full spec cold
github.com/modelcontextproto…
03 github-mcp-server → GitHub's own MCP server. the agent reads repos, manages issues and PRs directly, no more pasting text into the chat
github.com/github/github-mcp…
04 supabase-mcp → connects Supabase projects to Claude, Cursor and Windsurf. kills the copy-paste loop between your database dashboard and the agent
github.com/supabase-communit…
05 AWS MCP → suite of MCP servers for AWS, one per service. replaces hand-written CLI snippets with servers that ship the docs built in
github.com/awslabs/mcp
06 agent-toolkit → Stripe's toolkit with a hosted MCP server at mcp.stripe.com. the agent looks up payments and docs, you close the dashboard
github.com/stripe/agent-tool…
07 firecrawl-mcp-server → live web search and scraping returned as clean Markdown. stops the agent reading raw HTML and burning context on page clutter
github.com/firecrawl/firecra…
08 markitdown → Microsoft's converter turns PDFs and office files into Markdown the agent can actually read. ships as a one-line pip install
github.com/microsoft/markitd…
09 fastmcp → Pythonic framework that turns one function into an MCP server. powers 70% of MCP servers and ships a million downloads a day
github.com/PrefectHQ/fastmcp
10 mcp-use → fullstack TypeScript MCP framework. clocks 10,982 ops/s and installs at 74.4 MiB, 1.65x smaller than FastMCP
github.com/mcp-use/mcp-use
pick one tool your agent keeps reaching for. wire the server, test the call, chain the next one
index → reference server → plug code, database, cloud, payments → feed live web and files → build what's missing
the repos are free to clone. running them spends your Claude plan limits, and Firecrawl needs a paid API key
save this and check the full breakdown below ↓


THIS IS F*CKING INSANE
Kept the return, cut the crash 2.3x
QuantGPT ran one moving-average rule through one MCP endpoint. S&P 500, 1999 to 2026. Worst drawdown: -24.4% against -56.8% for buy and hold. Same 6.8% annual return. Sharpe 0.61 vs 0.44. 42 trades, gross of costs.
The model writes the rule. Everything after that is the server's job.
> SEND - model pushes the rule to the backtest server over MCP
> TEST - server replays it on nightly-refreshed history from 1998, delisted tickers included
> VERDICT - one of three doors: DATA VALIDATED, TRADE-OFF, NO EDGE
> SWEEP - one prompt, 5 lengths x 4 buffers, checks plateau vs lucky spike
> STRESS - futuretests replay holdings through past shocks: tariffs, oil, war
> JOURNAL - rechecks every finished test each time new bars land
Then 30 days on paper before any real capital moves.
No tool the model can call through MCP places, changes or cancels an order. The runner executes your code on your schedule, under your own keys, at your own broker. The model and the order book never share a path.
Take out the server and every backtest becomes a guess. Skip the paper window and the first real trade is also the first test.
Full call flow in the terminal below ↓
Spending tokens blind drains your whole budget
Tokdash v2.7.0 shipped Oct 24.
8 open-source GitHub repos for tracking token spend and capping agent budgets:
22.8k stars as of Oct 24. MIT and Apache-2.0. Pushed Oct 19–24.
MEASURE THE BURN
01. codeburn ★11.6k
▸ github.com/getagentseal/code…
→ spend by model, project, task
02. tokscale ★5.7k
▸ github.com/junhoyeo/tokscale
→ token and cost CLI across agents
03. Tokdash ★87
▸ github.com/JingbiaoMei/Tokda…
→ local dashboard with quota resets
PRICE EACH CALL
04. genai-prices ★401
▸ github.com/pydantic/genai-pr…
→ price table for LLM calls
CAP THE SPEND
05. floe-guard ★347
▸ github.com/Floe-Labs/floe-gu…
→ hard stop before budget ceiling
06. cycles-server ★5
▸ github.com/runcycles/cycles-…
→ reserve budget before agent acts
07. ai-gateway ★2.3k
▸ github.com/envoyproxy/ai-gat…
→ quotas and attribution at gateway
08. openmeter ★2.4k
▸ github.com/openmeterio/openm…
→ usage metering and enforcement
pip install floe-guard
from floe_guard import BudgetGuard
guard = BudgetGuard(limit_usd=5.00)
the stack:
logs → count → price → guard → reserve → quota → meter
Wrong ceiling stops a live agent.
Not the model. The blind spend around it.
Full cost stack in the terminal ↓
Flying blind on one caller's word.
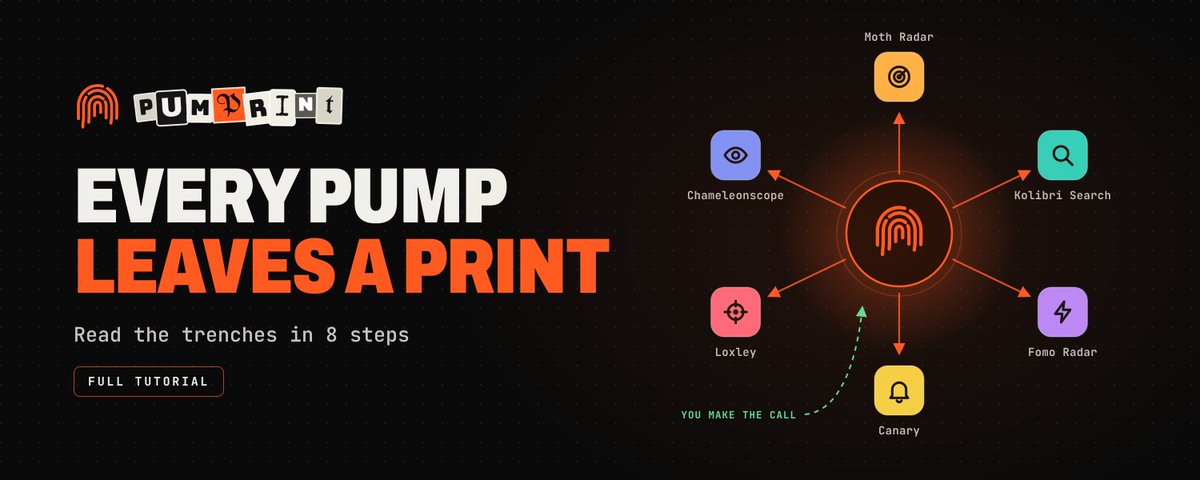
Pumprint splits two independent reads onto one screen. Most snipers never open the split.
Six tools, one site, every row carries a Split button: Kolibri Search, Moth Radar, Chameleonscope, Loxley, Canary, Fomo Radar. Each tool pairs with any of the other six. Learn sits in every list: glossary, a section per tool, the full routine.
> OPEN - button at the top right, lists the other five and Learn, pick one, it opens alongside
> PAIR - Moth Radar left, Kolibri right, address reads moth+kolibri, bookmarkable
> SIGNAL - caller grade from Kolibri and proven wallets from Fomo Radar, two reads with no shared input
> GATE - 1100 px for two panes, a phone shows one
The code runs both feeds. It never merges them into one verdict.
The merge layer is you.
That mechanism runs in the terminal below ↓

Agent cron has been breaking whenever the machine sleeps
7 open-source GitHub repos that turn an agent into a team that works on a schedule:
731,336 stars combined, 6 of 7 pushed within 4 days, all permissive, stars checked Oct 23
WAKE ON A CLOCK
01. hermes-agent ★254,427: github.com/NousResearch/herm… -> cron + Telegram + auto-retry (README claim)
02. openclaw ★392,196: github.com/openclaw/openclaw -> local assistant for Telegram, Slack and more
RUN AND PAUSE
03. trigger.dev ★16,559: github.com/triggerdotdev/tri… -> durable cron + queues + human waitpoints (README claim)
04. temporal ★23,756: github.com/temporalio/tempor… -> durable execution across crashes
05. dbos-transact-py ★1,635: github.com/dbos-inc/dbos-tra… -> Postgres cron + durable sleep (README claim)
DELIVER THE RESULT
06. apprise ★17,597: github.com/caronc/apprise -> one call to Telegram, email or anywhere
REMEMBER BETWEEN RUNS
07. letta ★25,166: github.com/letta-ai/letta -> persistent memory that learns between runs (README claim)
clock -> background run -> human approval -> durable resume -> chat delivery -> memory
curl -fsSL hermes-agent.nousresearch.co… | bash
Only trigger.dev and hermes-agent name a human approval step; start read-only before cron touches anything irreversible
Not a smarter model, a cron that stays alive when you walk away ↓
Ridark retweeted

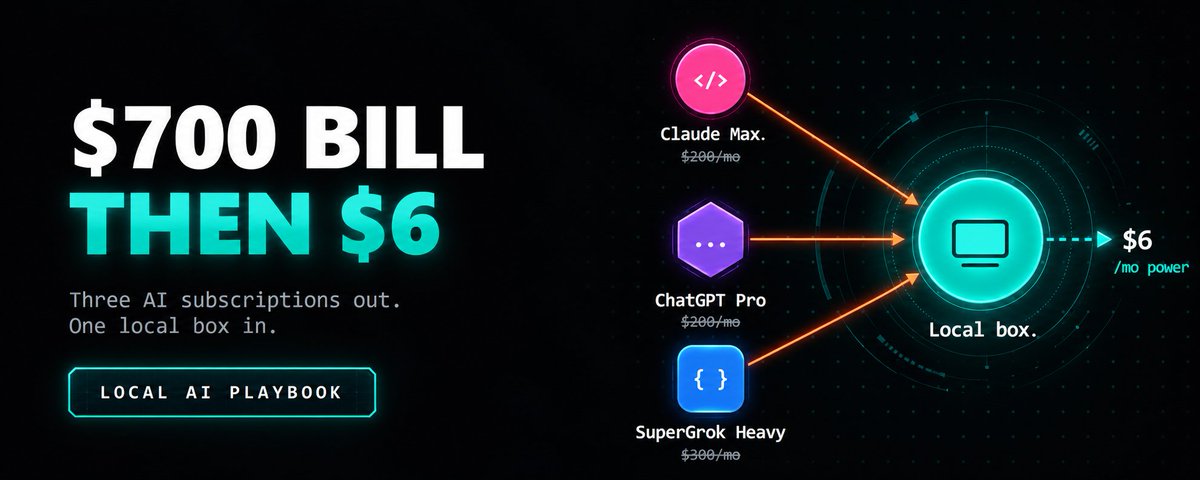
Two boxes at $749 reroute every AI call locally.
The builder's $700 monthly cloud bill, cancelled.
Jetson Orin Nano Super: NVIDIA spec, 8GB, 67 TOPS, $249 once. RTX 3090: 24GB VRAM, $500 used. Electricity: $6 on the Jetson, ~$10 on the 3090, the builder's figures. First year on the Jetson path: $321 total vs $8,400 in subscriptions.
ROUTE - Ollama on the 3090, one env var reroutes Claude Code from the cloud to a local endpoint
LOAD - qwen3-coder-30b fills the coding seat at 18GB
SWAP - qwen3.8-27b takes chat at 18GB, devstral small 2 covers repos at 12GB
SPLIT - Jetson handles decisions with a 4B model at 4.4GB and a 9B browser agent, zero API calls
WIRE - phone app connects straight to the Jetson over local network, same UI as the cloud
The 8GB board does not load a 35B model. A local model at 12–18GB is not the same product as a $200 cloud tier: narrower context, no managed tool layer. What it gives back is zero per-token cost and every prompt stays on the box.
Full routing map in the terminal below ↓
284B inference just hit 30 tok/s over open WAN
iroh v1.4.1 shipped this week. Mesh-LLM v0.78.1 patched chunked-request admission.
9 open-source GitHub repos that turn idle GPUs into one P2P inference mesh:
32,304 combined stars. All permissive. 6 pushed in the last 8 days, stars as of Oct 22.
JOIN THE MESH
01. iroh ★12.8k: github.com/n0-computer/iroh -> QUIC transport, NAT hole-punching
02. rust-libp2p ★5.6k: github.com/libp2p/rust-libp2… -> peer discovery and relay routing
03. kalavai-client ★222: github.com/kalavai-net/kalav… -> pool spare GPU capacity
SPLIT THE MODEL
04. shard ★465: github.com/leyten/shard -> stream layer blocks across WAN
30.15 tok/s on 284B, six RTX 5090s, shard README
05. distributed-llama ★3.1k: github.com/b4rtaz/distribute… -> split weights across home devices
06. prima.cpp ★113: github.com/OpenCPIL/prima.cp… -> 70B on laptops and phones
674 ms vs 10,120 ms, 15x over llama.cpp, prima.cpp README
ROUTE REQUESTS
07. mesh-llm ★3.5k: github.com/Mesh-LLM/mesh-llm -> one OpenAI API over pooled GPUs
08. pooled ★604: github.com/Nehanth/pooled -> P2P inference in the browser
09. gpustack ★5.9k: github.com/gpustack/gpustack -> schedule models across GPU nodes
the mesh:
peer → discover → relay → pool → shard → route → schedule → endpoint
curl -fsSL raw.githubusercontent.com/Me… | bash
Not a bigger GPU. A mesh of whatever you already own.
Most nodes alpha. Prompts travel open wire unless the mesh is private ⭣
vLLM shipped a GPU speculator, and full-precision lost
vLLM v0.32.0 on Oct 18, GPU n-gram speculator in Model Runner V2. speculators v0.9.0 the next day, 50% less hidden-state storage.
10 open-source GitHub repos that turn full-precision weights into cheap tokens:
167.8k combined stars. 9 Apache-2.0, 1 MIT. 8 of 10 pushed this week. Checked Oct 22.
SHRINK THE WEIGHTS
01. llm-compressor ★3.9k
github.com/vllm-project/llm-…
-> Quantize and prune for vLLM
02. GPTQModel ★1.3k
github.com/ModelCloud/GPTQMo…
-> GPTQ and AWQ on any hardware
03. Model-Optimizer ★5.4k
github.com/NVIDIA/Model-Opti…
-> Quantize, prune, distill for vLLM
04. bitsandbytes ★8.5k
github.com/bitsandbytes-foun…
-> 4-bit and 8-bit PyTorch kernels
SPECULATE AHEAD
05. speculators ★914
github.com/vllm-project/spec…
-> Train draft models for vLLM
06. ArcticInference ★490
github.com/snowflakedb/Arcti…
-> vLLM throughput and latency plugin
BATCH AND SERVE
07. vllm ★94.9k
github.com/vllm-project/vllm
-> Continuous batching, prefix caching, quantized serving
08. sglang ★37.6k
github.com/sgl-project/sglan…
-> Fast serving for agentic workloads
09. lmdeploy ★8.1k
github.com/InternLM/lmdeploy
-> Compress, deploy, serve in one toolkit
10. flashinfer ★6.7k
github.com/flashinfer-ai/fla…
-> Attention, GEMM and MoE kernels
the stack:
full-precision model → quantize → train draft → batch and serve → fused kernels → cheaper tokens
uv pip install vllm
vllm download-kernels # precompiled kernels for faster startup
W4A4 lands about 2.3 points below W4A16 on GSM8K Platinum (GPTQModel README). The trade is always accuracy.
Not a bigger GPU. A tighter pipeline from compressed weights to fused attention ↓
Opus 5.5 is the coldest $0 hire in AI.
One builder's agent replaced a $200,000-a-year role overnight.
Chief-of-staff agent running Opus 5.5 inside Viktor. Its own cloud computer. Owner's laptop shut. One rule: find $50,000 a month of new business, public data only, contact nobody without a yes.
Builder's overnight log:
→ 9PM SPLIT the goal into 4 jobs, each with a day and a deadline
→ 11PM PULLED 240 dental clinics in Austin off Google Maps, cut every chain
→ 1AM READ every remaining site, kept 25 with one noticed detail each
→ 2AM WROTE an opener for all 25, sent zero
→ 3AM BUILT the offer on one page, price left blank for the owner
→ 8AM Owner typed $2,000. 25 × $2,000 = $50,000/month on the table
$50,000 a month is potential revenue on a goal table, not signed clients. Nothing ships without the owner's yes.
The blank price is the real gate. An agent that fills in your price loses the deal before you open your laptop.
Every Monday it runs again. 100 new clinics a month. The funnel never stops.
Two AI girls and $24,542 in one month
A 22-year-old man from China created two virtual girls and turned them into a business. According to the original post, his starting investment was just $20 for Claude.
For the first AI girl, he set up a Fanvue account with a $9.99 subscription. With Claude’s help, he analyzed male audience preferences and developed the character. Photos and videos were generated automatically and published on a schedule.
In one month: 1,265 subscribers and $12,637 in revenue.
The second AI girl appeared on livestreams across three platforms: TikTok, YouTube, and Kick. The original post describes Claude changing her appearance and voice in real time during the broadcasts.
Viewers regularly sent donations, with the largest reaching $500.
The streams brought in another $11,905 that month.
Total revenue: $24,542 from two virtual characters.
AI + creativity = new possibilities

A 28-year-old guy from Japan decided to just make a joke, but in the end, he earned $3,258 in 4 hours
With the help of Claude, he created a Chinese girl and launched the first stream for a prank
Claude changed the appearance, background, voice, and even language in real time
He launched the stream simultaneously on 3 platforms: YouTube, TikTok, and Twitch
Men liked the girl so much that they started donating just 20 minutes into the stream
In 4 hours, they donated $3,258 to him
The largest single donation was $400
REAL OR AI? the split screen says it all. same room, same angle, same lighting. the top half looks like a real woman. the bottom half is the guy actually driving her face
The guide on how to create this has already been leaked into the public domain
THIS GUY TURNED HIMSELF INTO AN AI GIRL IN ONE SECOND. THE WORKFLOW BEHIND IT CAN RUN A $5,000/MONTH FANVUE PAGE IN 40 MINUTES A DAY
00:01 he raises his arms and instantly turns into an AI girl sitting in the same chair, ready to stream without ever showing his real face
Claude creates the name, personality, captions and replies. one prompt can generate a full week of content while keeping the same character across TikTok and Fanvue
ComfyUI with Flux builds the face and photo library. Kling 3.0 animates the images, then CapCut turns them into 30 to 50 short videos in one afternoon
three daily streams and one clip reaching 400,000 views can send 70 buyers into a $15 Fanvue subscription. paid messages and tips are what push the page past $5,000
he stays behind the camera, Claude runs the brain and the AI girl becomes a business that works every day
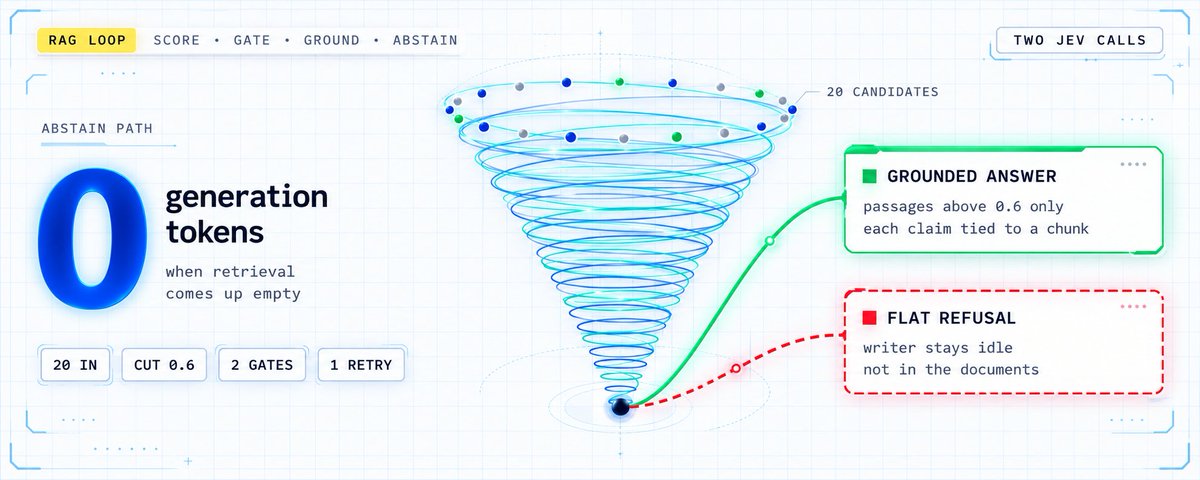
TypeSafe built Jev to return probabilities, not prose. A typed model that scores a full passage pool in one request and fires two binary gates on the spot.
Hindsight swapped their MiniLM reranker for it: 0.027 s vs 0.12 s per query at 30 candidates, recall@1 0.950 vs 0.800 (Hindsight benchmark, LoCoMo). Two Jev calls score and verify the whole loop:
1. HYBRID SEARCH: dense vectors + keyword match surface the top 20 candidates (design value, per the post)
2. JEV #1: one request scores all 20 passages and fires two gates: answerable? injection?
3. THRESHOLD: 0.6 drops everything below it. The writer agent never sees low-confidence material (design value, per the post)
4. WRITER: drafts the answer from the passages that survived
5. JEV #2: walks every claim in the draft back to its source passage
6. GATE FAIL: answerable returns no, writer never fires. A researcher reshapes the query for one retry. Second miss kills the loop: "not in the docs"
the injection flag is a retrieval filter, not a security perimeter.
remove the answerable gate and every unanswerable query becomes a paid hallucination. two scoring calls, two gates, one hard no.
The full loop runs in the terminal below ↓
Ridark retweeted
MY FIRST HOUR WITH THE NEW GROK BOT WENT ON TAKING PERMISSIONS AWAY, NOT ADDING THEM.
The release shipped Coinbase, Robinhood and eToro connectors, access to your X Chat, email aliases, and a public trigger: anyone can tag @bot under your post and start a task.
That is not a faster chatbot. That is a funded account with a front door.
So before I gave it a single job:
→ Execution runs in its own sub-account with a hard cap. The main balance stays disconnected.
→ Nothing sends on its own. DM and email drafts wait for me.
→ One connector per agent. Only the Head of Desk sees all of them.
→ Every routine gets its own email alias, so launches and invoices never share a queue.
A boring hour. It is the reason the rest runs while I am not there.
Then the part nobody is posting.
Everyone aimed the new connectors at the market on day one. The most expensive thing an agent like this finds is almost never a trade. SpaceXSI pointed theirs at their own vendor contracts and unused seats. Over $100k in the first week, and that template is public.
The fastest alpha in this release is not a token. It is a subscription you forgot to cancel.
Decide what your bot cannot do while it is still boring. After it is connected, that conversation gets expensive.
Ridark retweeted

si queréis aprender sobre IA solo os diré que sigáis a esta cuenta, no diré nada mas.

Ingeniero de Anthropic:
"99% de las personas usan Claude Code como Google, y solo el 1% están ejecutando enjambres de agentes Claude de autoaprendizaje.
Yo estoy ejecutando más de 100 agentes en un bucle. Tengo un agente Jefe, agentes PM - ellos gestionan todo el equipo.
en un taller de 30 minutos, un ingeniero de Anthropic reveló cómo obtener el máximo valor de Claude Code con el mínimo costo.
esto vale más que otro curso de $500
guárdalo y sígueme para más → @robiartec
MY FIRST HOUR WITH THE NEW GROK BOT WENT ON TAKING PERMISSIONS AWAY, NOT ADDING THEM.
The release shipped Coinbase, Robinhood and eToro connectors, access to your X Chat, email aliases, and a public trigger: anyone can tag @bot under your post and start a task.
That is not a faster chatbot. That is a funded account with a front door.
So before I gave it a single job:
→ Execution runs in its own sub-account with a hard cap. The main balance stays disconnected.
→ Nothing sends on its own. DM and email drafts wait for me.
→ One connector per agent. Only the Head of Desk sees all of them.
→ Every routine gets its own email alias, so launches and invoices never share a queue.
A boring hour. It is the reason the rest runs while I am not there.
Then the part nobody is posting.
Everyone aimed the new connectors at the market on day one. The most expensive thing an agent like this finds is almost never a trade. SpaceXSI pointed theirs at their own vendor contracts and unused seats. Over $100k in the first week, and that template is public.
The fastest alpha in this release is not a token. It is a subscription you forgot to cancel.
Decide what your bot cannot do while it is still boring. After it is connected, that conversation gets expensive.
8 Grok bots fight over one wallet and every morning the loser is deleted while the winner clones itself
A head-of-desk Grok agent ranks the whole thing. 8 pods, 8 trading strategies, one shared capital pool, scored once a day.
→ LAUNCH: eight pods go live, each strategy different, all drawing from one pool
→ RANK: head-of-desk Grok scores every pod at the day's close
→ DELETE: bottom pod wiped on the spot, no appeal
→ CLONE: top pod copies itself into the empty seat, arena stays at 8
→ GATE: anything large routed to the owner for sign-off before it fires
→ RE-RANK: next morning the whole arena is re-scored and the cycle eats the next weakest
One swap per day, eight seats. Run that for eight rounds and every original can be gone. The whole arena descended from a single line.
Ranking on a short window rewards the luckiest stretch and breeds copies of it. The pod that survived Monday tells you nothing about Friday.
Full kill-or-clone cycle in the terminal below ↓
