
San Francisco, CA
Joined October 2010
- Tweets97
- Following657
- Followers288
- Likes7K





Saketh Rambhatla retweeted

In-context learning!!
We’ve spent years in robotics assuming a new task means new data. Collect demos —> finetune —> eval —> repeat.
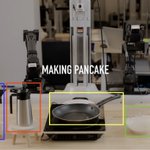
S1 is much more elegant and intuitive: show it one video of an unseen and the model just works. No fine-tuning or gradient updates needed.
It can do so many complex tasks, even ones that run for 10 minutes or longer. It’s especially impressive to see completely new behaviors emerge at test time, like flipping a pancake, even though that behavior never appeared in the training data.
It’s amazing to see S1 pick up a new task from a single example - something I really thought was still years away.

Saketh Rambhatla retweeted

Language Models are Few-Shot Learners showed that GPT-3 could tackle almost any language task with zero, one, or just a few examples.
We’ve heard “the ChatGPT moment for robotics” many times. IMO, the definition is similar: a robot that can take on arbitrary new tasks from zero, one, or a few demonstrations without further tuning, even when those demos come from humans, other embodiments, or are suboptimal.
Today, I’m excited that we’re one big step closer : )
Enjoy S1 🚀
skild.ai/blogs/s1

Saketh Rambhatla retweeted

This is the first genuine ChatGPT moment in robotics. I head they are already in production?!
Saketh Rambhatla retweeted

Strong scaling laws for one-shot learning in long-horizon manipulation tasks.
It's only a matter of time until these models are ready for widespread deployment with very little task-specific data.

Saketh Rambhatla retweeted

Video editing is now available on the Meta AI app!
A team of ~10 people built this from scratch in under a year. It was a fun and amazing team effort, with some of the nicest people to work with.

Saketh Rambhatla retweeted

Presenting video editing (up to 10s videos) in Meta AI! Generate high-fidelity edits fast⚡(under 30 seconds) with no usage limits, powered by our model trained in-house last year! Took a while to get this out but excited to share with the world 🧵below with all the capabilities
Saketh Rambhatla retweeted

Warehouses are a critical part of the modern economy, but are still bottlenecked by human labor.
We've acquired Fetch Robotics to tackle previously hard-to-automate parts of warehouse logistics with our omni-bodied AI!
(Our factorio players are delighted)

Saketh Rambhatla retweeted

We hosted Prof. Alyosha Efros (UC Berkeley) at @SkildAI! He didn't believe that robots could actually cook eggs reliably. :)
Tested back-to-back 5times without fail! One batch of scrambled eggs every ~2.5mins nonstop. The same model assembles a GPU on a server rack too.
Saketh Rambhatla retweeted
At @SkildAI, we’ve raised $1.4B, bringing our valuation to over $14B.
We’re on a generational mission, and I’m grateful to be working alongside an exceptional team. Thanks to our investors for the long-term conviction towards omni-bodied intelligence 🚀
bloomberg.com/news/articles/…
Announcing Series C
We’ve raised $1.4B, valuing the company at over $14B
With this capital, we will accelerate our mission to build omni-bodied intelligence 🚀
skild.ai/blogs/series-c
Saketh Rambhatla retweeted
Announcing Series C
We’ve raised $1.4B, valuing the company at over $14B
With this capital, we will accelerate our mission to build omni-bodied intelligence 🚀
skild.ai/blogs/series-c
Saketh Rambhatla retweeted

Inference time objectives are amazing :)
We show that LLMs can be upgraded to multimodal beings by a simple trick :) No training needed!
Works on image generation, editing, style transfer and more!

Saketh Rambhatla retweeted

Super excited to share some recent work that shows that pure, text-only LLMs, can see and hear without any training! Our approach, called "MILS", uses LLMs with off-the-shelf multimodal models, to caption images/videos/audio, improve image generation, style transfer, and more!

Saketh Rambhatla retweeted

Super cool to see transformers scaling so effectively for image/video autoencoders!
Our model also offers a flexible way to implement variable token length


Saketh Rambhatla retweeted

How can we better animate images solely following text descriptions?
We present Motion Focal Loss (MotiF) (arxiv.org/abs/2412.16153) to better align motions with text descriptions in text-image-to-video (TI2V) task and release TI2V-Bench, a comprehensive TI2V benchmark. (1/n)
Saketh Rambhatla retweeted
Flow matching can transform one distribution to another. So why do text-to-image models map noise to images instead of directly mapping text to images?
Wouldn't it be cool to directly connect modalities together? CrossFlow accomplishes exactly that! cross-flow.github.io/
