





Seapy retweeted

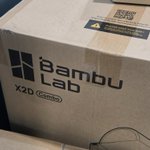
Save this post, the Bambu Lab Black Friday Playbook is here.
Beyond our best prices of the year and the 28 × H2C Combos giveaway on the official store, we're dropping a massive prize pool right here:
• 5 × Bambu Lab H3C (yes, our brand new H3C!)
• 20 × 4-Color Filament Bundles
• 50 × $50 Bambu Lab Store Coupons
• One Ultimate Grand Prize (revealed tomorrow)
You might want to clear some space in your workshop...
#BambuLab #BlackFriday #3DPrinting

Seapy retweeted
$TSLA
BREAKING: Turo and Tesla just announced the first verified Tesla FSD(Supervised) rental experience in the U.S., launching October 28.
• For guests: You can search for and book Teslas with FSD (Supervised) activated. FSD status is verified through a direct Tesla API integration.
• For hosts: Once a host links their Tesla account to Turo, FSD status is verified automatically and shown on eligible listings. Eligible U.S. hosts also get a free one-month FSD (Supervised) trial.
• Scale: Thousands of FSD-enabled Teslas are already on Turo. The Model 3 and Model Y are the 3rd and 4th most popular models on the platform this year.
• CEO quote: Turo CEO Andre Haddad says 55% of Americans, and 71% of Gen Z, are interested in self-driving tech for travel.


Seapy retweeted

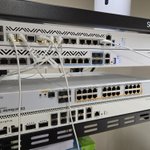
[New Post] 3D 프린터로 만든 10인치 서버 랙
blog.outsider.ne.kr/1816

Seapy retweeted

Kimi K3.1 Pro 翻车了
MiniMax M3.1 Flash 翻车了
Muse wonder 翻车了
Gemini 4 Argon 也翻车了
只有 Deepseek V4.1 Flash 1017
大家边夸边用
Seapy retweeted

"The pace, and the expectations that came with it, felt almost as jarring [in China] compared with America as America's pace does compared with Europe. Everyone was just on it, all the time." world.hey.com/dhh/seven-year…

Seapy retweeted

Worst idea of the day goes to governmental official of relatively small country who suggested they would require AI companies to publicly disclose to their product safety commission within 24 hours of discovery all software vulnerabilities. 🤦🏻♂️🙅🏻♂️☠️


Seapy retweeted

🎉 MiniMax M3.1 Flash from @MiniMax_AI has Day-0 support in vLLM!
Built for multi-step automation, real-codebase engineering and visual reasoning—with native NVFP4 KV, NVFP4 MoE weights and DSpark speculative decoding in the serving stack.
What the model can do, and the vLLM engineering that makes it practical to serve. 👇
Model: huggingface.co/MiniMaxAI/Min…
1/5

MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token.
Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym.
Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency.
Hugging Face:
huggingface.co/MiniMaxAI/Min…
ModelScope:
modelscope.cn/models/MiniMax…
API: platform.minimax.io
M Plan: minimax.io/m-planMiniMax
MCode for desktop: agent.minimax.io/download

Seapy retweeted

As of today, during the Python Core Sprint, I have made 500 commits to CPython. It's been 910 days since my 400th commit. See you at 600 commits!
Thanks to all the core devs working with me. It's always such a pleasure to collaborate with you all!


Seapy retweeted
I remember when 200tps felt impossibly fast. This is going to be crazy.

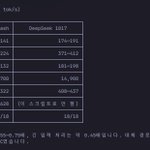
DeepSeek V4.1 Flash 1017 runs at 1,521+ tok/s on Fireworks Ultrafast.
Fast enough to ship Tetris in 11 seconds, 7x faster than Claude Opus 5.5.
Join the Ultrafast waitlist: bit.ly/3UA0wKq


Seapy retweeted

Rejoice single DGX Spark owners!
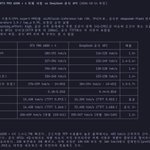
You can now run Qwen3.8 Flash Next on TensorFold with the new Nvidia FP4 QAD quant 🔥
- 1.1M total FP8 KV cache
- 256k context, 5 concurrent users
- 46-55 tok/s on prose, single stream
- 132 tok/s on prose, 5 concurrent steams
- Prefill 2000-2300 tok/s
Qwen3.8 Flash Next is still the BEST model to run on one DGX Spark, bare none!
You can choose what to run: FP4 QAD for quality, or int4 for speed. Details on what is QAD below.
Get it here:
mia-ai.net/models/Qwen3.8-Fl…

Seapy retweeted
The 'old' vLLM recipe for DeepSeek v4.1 Flash *should* work with the new 1017 release. I haven't tried it though. Just try replacing the model.
That being said, I'm working on a TensorFold recipe.
vLLM recipe here:
github.com/MiaAI-Lab/DeepSee…


Seapy retweeted

Linus Torvalds “AI 사용을 금지하지 않겠다. 자신이 하는 일을 이해해야 한다”
Linux 커널 기여자에게 요구하는 것은 최선을 다하는 태도와 작업에 대한 이해이며, 어떤 도구를 쓰는지는 이해 수준과 관련이 매우 적다는 입장
도구 없이 역량을 증명하라는 논리라면, 기계의 동작을 이해한다는 증거로 컴파일러 없이 어셈블리를 직접 작성하라고 해야 하느냐고 반문함. 이런 이유로 특정 작업에 AI를 쓰지 못하게 하는 규칙을 만들지 않겠다고 밝힘
news.hada.io/topic?id=35504


Seapy retweeted

더이상 glm-5.3을 쓸 필요가 없네요.

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4

