
I build SaaS. Fullstack Kotlin/Angular. Local AI.
Joined November 2009
- Tweets853
- Following294
- Followers3.9K
- Likes2.9K



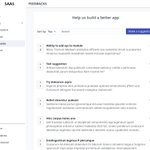
4/ I don't want to use third-party ACP code plugin (security risk), that's why I use pi terminal and not pi ACP. I did not test the ACP version.
22
3/ The OS/system indicator works when an agent finished (great). But no indicator in the app of unread sessions. I have a green pill when its busy, but when it's done and unread, no more pill, i have a blue pill when I mark unread, that's what I expected to be done automatically.
1
28
2/ Create a new session, do nothing, open a file, go back to air list of session, click on the session opened, it displays: "This terminal runs on another "
1
27
heading in the right direction, but still very buggy. I'm using pi in terminal mode.
1/ Some sessions disappear when I close / open the app.
1
1
364
Software is fixable. Looks the jump made strix with Q38FN and all the new inference engine/kernels recently.
This is the best hardware/$ now.
A cluster of 20 used GPUs, even if more performant, does sound better to me (more expensive, noise, power, and how cumbersome).
1
27
C'est plus fluide, tout semble mieux fonctionner out of the box et en particulier avec les nouveaux TUI à la con.
J'aimerai pouvoir virer tmux qui fait un peu doublon avec ghostty mais j'en ai besoin pour la persistance session remote.
68
J'upgrade ma stack terminal/cli de dinosaure que j'utilise depuis +20ans:
- terminal de distrib -> ghostty (gpu/perf)
- screen (abandonware) -> tmux
- vim (dinosaure) -> neovim
- bash -> fish (pas encore testé, looks promising)
1
1
121
I'm already 70-80tok/s (code) on Q38FNwith my little strix halo, so you can expect far greater than 100tok/s on a M5 ultra once inference engine and kernels have been really optimized (probably more than 200). But you won't run Q38FN on a mac though, you'll have better models :)
170
J'ai un HP z2, et mon laptop est aussi un HP strix 128G (mais je fais pas d'IA avec). strix/spark c'est pas mal, mais je trouve que c'est bcp trop cher en neuf (comme tout le reste).
1
17
avec un strix je suis à 1800pp et 70-80tok/s sur du code (peut etre meme plus avec les dernières maj), un M5 ultra doit pouvoir faire le double au minimum, et quand les moteurs d'inférences/modèles seront aussi répandus et optimisés pour mac qu'un strix, ce sera > 200tok/sec
1
51
ouai, j'ai complétement abandonné l'idée d'acheter du matos hors de prix, franchement avec ce modèle je peux hodl pendant encore 2 ans, entre temps et il y aura des nouveaux modèles, du nouveau matos, et la RAM sera (probablement) a un prix plus convenable.
1
38
Le M5 ultra c'est le meilleur deal aujourd'hui pour l'IA local, et de très loin, j'avais prévu d'acheter la future version 512G (~17k€).
Mais entre temps il y a eu Q38FN qui est tellement bon et rapide sur strix que ça ne présente plus d'intérêt d'upgrade.

1 DGX + 8 RTX 5090 : voilà qqch de sérieux pour faire de l'IA locale. Bon, la difficulté c'est de trouver des 5090 à son vrai prix conseillé mais c'est un autre sujet :)
Petite question @Brain0verride, pourquoi ne pas avoir choisi de Mac Studio ?
1
1
478
Mon analyse (d'expert) de l'IPO d'Anthropic:
- CA sur 1 an +1300%: 787M -> 11.5B
- Environ ~120B cash à dispo
- "Profitable" bénéfice 974M sur Q2-26 mais ...
- ... 500B de contrats compute/datacenters (=dette, dépense à venir)
- La croissance ralentie: Q1->Q2 +140 %, Q2->Q3 +45%
1
210
Vraiment pas terrible 😬 Des modèles qui tournent facilement en local font mieux... Qwen 27B, ou plus gros Qwen 3.8 flash next que j'utilise sur mon strix et qui est très bon pour le code.

Mistral has released Mistral Large 4, scoring 38 on the Artificial Analysis Intelligence Index; France is back to having the most intelligent model from outside the US and China
@MistralAI has released Mistral Large 4 in Research Public Preview, with plans to release the weights of the 1T parameter (49B active) model at the end of October. It achieves 38 on the Artificial Analysis Intelligence Index, comparable to GPT-6 Luna (max, 38) and DeepSeek V4.1 Flash (max, 39). It also achieves 50% on the Artificial Analysis Cyber Index, level with GLM-5.3-Flash and ahead of models such as Kimi K3 and DeepSeek V4.1 Flash (max).
Key benchmarking results for Mistral Large 4 Preview:
➤ Most intelligent model from outside the US and China: Mistral Large 4 Preview scores 38 on the Intelligence Index, comparable to DeepSeek V4.1 Flash (max, 39) and GPT-6 Luna (max, 38). This makes it the most intelligent model from outside the US and China, ahead of countries such as South Korea and the United Arab Emirates
➤ Level with GLM-5.3-Flash on cyber defense capability: Mistral Large 4 Preview scores 50 on the Artificial Analysis Cyber Index, level with GLM-5.3-Flash (50) and behind MiMo-V2.6-Pro (56). Once its weights are released, it will rank among the top three open weights models on the Cyber Index. Its strongest result is on CyberGym-E2E-AA, where it scores 82%, ahead of MiMo-V2.6-Pro (79%) and GPT-6 Luna (max, 78%)
➤ Over 4x the Cost per Task of similar-intelligence open weights models: Mistral Large 4 Preview costs $1.13 per Intelligence Index task with standard pricing of $1.36/$4.18 per 1M input/output tokens, with $0.14 per 1M cached input tokens. For the first two weeks, Mistral Large 4 Preview will be served at a 50% launch discount, bringing its Cost per Task down to $0.57. This is still more costly than GLM-5.3-Flash ($0.25) and DeepSeek V4.1 Flash (max, $0.27)
➤ Strong document and image reasoning: Mistral Large 4 Preview scores 19% on GDP.pdf, on par with MiMo-V2.6-Pro (19%) and behind Kimi K3 (22%). This is an 18-point improvement from Mistral Large 3, partly driven by improvements in their API, which now accepts 100 images per request, up from 8 for previous Mistral models
Key model details:
➤ Context Window: 512k tokens
➤ Multimodality: Text and image input, with text output
➤ Pricing: $1.36/$4.18 per 1M input/output tokens ($0.14 per 1M cached input tokens), with 50% off for the first two weeks ($0.68/$2.09)
➤ Availability: Research Public Preview on Mistral's API, with open weights planned for the end of October

1
198
tu vas pouvoir faire pas mal de trucs avec un mac studio M5 512G (faudra qd meme prévoir dans les 15-18k€). Là avec mon pauvre strix (128G) et qwen 3.8 flash je suis déjà très content du résultat. Alors avec 4 fois plus de ram et puissance ça va être du solide.
1
1
68
26 100$ pour 2 x 5090. Quelle blague.
Non seulement le hardware est hors de prix mais en + les mecs prennent 10 000$ de marge pour assembler un PC. C'est n'importe quoi.
autonomous.ai/computer-2

167
s'adapter à du hardware moins puissant / différent.
Bref, très mauvais moment pour acheter du hardware IA (et peut être pas encore le pire !)
1
96
- Les industriels auront eu le temps de scaler pour satisfaire la demande.
- Nouvelles technos, une RTX 6000 pro à 12k (anciennement 6k) est juste un GPU très puissant (RAM + bande passante), mais pas spécialement optimisé pour de l'IA.
- La stack software évolue vite pour
1
115
"la CMP 170HX, s’est écoulé jusqu’à 4 300 dollars. Une fois la fête crypto terminée, 100 dollars sur le marché de l’occasion."
On en est à peu près là avec l'IA et le hardware. Ce qui vaut 10k-100k€ aujourd'hui vaudra beaucoup moins dans 2-3 ans mais pour différentes raisons:

Elle valait 100 dollars il y a quelques semaines. Un outil communautaire vient de réveiller les 64 Go de mémoire que NVIDIA avait éteints dessus, et elle se revend maintenant au-delà de 1 200 dollars. ➡️ 01net.com/actualites/pourquo…

1
4
676