
Research @CapitalOne | prev @Apple, @AdobeResearch Grad @UMassAmherst, undergrad @IITGuwahati
New York
Joined September 2016
- Tweets26
- Following418
- Followers110
- Likes707
Shreyas Kulkarni retweeted

Wrote another post on speculative decoding, this time without a separate draft model.
Covers prompt lookup, REST, SuffixDecoding, and Lookahead. Also went through Lookahead step by step in code.
ayushmansingh.com/posts/how-…

Shreyas Kulkarni retweeted
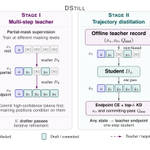
There's still a lot of juice left in existing draft model architectures, just from training them better. DStill keeps the DFlash drafter architecture unchanged and gets up to 28% higher acceptance length and 25% more speedup at the same inference cost. Great work by @shreyask269 and @madhav_kanda_ .
A few training insights from the paper I liked:
1. Running vanilla DFlash for 8 denoising passes lowers acceptance length (4.45 → 3.70 on GPT-OSS-120B), because it only saw fully masked blocks in training. A drafter trained on partially revealed blocks improves with 8 passes (4.50 → 5.31).
2. They distill that 8-pass teacher into a one-pass student with the same architecture. The student is trained to predict the teacher's final block from any state on its refinement trajectory, and recovers 29-36% of the multi-step gain in one pass.
3. Distillation uses a curriculum: the student trains on both intermediate and fully masked states, and the share of fully masked states rises from 0.5 to 0.85 over training. This beats training on fully masked states only.
4. Longer training doesn't explain the gain. DFlash trained for twice as many epochs gets slightly lower acceptance length. The DStill gains over DFlash hold at concurrency up to 32, and the method also improves DSpark (+4.5% acceptance length).

Can diffusion drafters benefit from multi-step denoising while still drafting in a single pass?
Excited to share DStill, our new work on accelerating block diffusion speculative decoding! 🚀
We learn from the drafter’s denoising trajectories during training to improve draft acceptance, while keeping drafting to a single forward pass at inference.
⚡ Up to 6.45× speedup over autoregressive decoding.
📄 arxiv.org/abs/2610.27379
A thread 🧵👇

Can diffusion drafters benefit from multi-step denoising while still drafting in a single pass?
Excited to share DStill, our new work on accelerating block diffusion speculative decoding! 🚀
We learn from the drafter’s denoising trajectories during training to improve draft acceptance, while keeping drafting to a single forward pass at inference.
⚡ Up to 6.45× speedup over autoregressive decoding.
📄 arxiv.org/abs/2610.27379
A thread 🧵👇
💡 Our approach:
Instead of running multiple denoising steps at inference time, we learn from those trajectories during training.
Combined with curriculum learning, DStill improves draft acceptance while retaining a single drafting pass at inference time.
1
2
197
📊 The results:
Compared with one-step DFlash:
• Up to 28% higher acceptance length
• Up to 25% faster generation
Up to 6.45× speedup over autoregressive decoding.
No extra denoising passes at inference.
📄 arxiv.org/abs/2610.27379

3
141
Shreyas Kulkarni retweeted
I'm teaching a course on differential privacy this term. I'm thinking of making the lectures and materials public, but I'm on the fence. Would people be interested in this...? I don't think there's a course on DP with lecture videos online yet. #privacy

A nice blog on introductory private statistics!
Jon Ullman and I are doing a series of educational blog posts on private statistics. Check out Part 1 for some bounds for private mean estimation! Comments/questions welcome. #privacy kamathematics.wordpress.com/…

1
Shreyas Kulkarni retweeted

"The miracle of appropriateness of the language of mathematics for the formulation of the laws of physics is a wonderful gift which we neither understand nor deserve" - Eugene Wigner

Shreyas Kulkarni retweeted
Differential Privacy is named one of the 10 Breakthrough Technologies of 2020 by @techreview, due to its deployment in the 2020 US Census (@uscensusbureau). Exciting time to be working in this space! h/t @Aaroth #privacy
technologyreview.com/lists/t…
Shreyas Kulkarni retweeted

Learnt a lot from @twimlai podcast on #differential #privacy, a way of collecting #data about the population while protecting the privacy of individual users by adding noise to the data 🔏here's the podcast: open.spotify.com/episode/3Mx…
Shreyas Kulkarni retweeted

For someone who has a lot of plans in the next decade, great video to start it.
Randy Pausch Last Lecture: Achieving Your Childhood Dreams youtu.be/ji5_MqicxSo via @YouTube

Shreyas Kulkarni retweeted

I’m moderating #NeurIPS2019 ML with Guarantees panel with @EmmaBrunskill @Aaroth @FeiziSoheil et al. at 5:30pm. Respond to this tweet with questions you’d like to ask! sites.google.com/view/mlwith…

Shreyas Kulkarni retweeted
The first full paper on @pytorch after 3 years of development.
It describes our goals, design principles, technical details uptil v0.4
Catch the poster at #NeurIPS2019
Authored by @apaszke , @colesbury et. al.
arxiv.org/abs/1912.01703