

My 9 to 5 is as Google Developer Experts Lead - Americas. My 5 to 9 is street photography.
Mexico
Joined May 2008
- Tweets23.3K
- Following2.2K
- Followers6.9K
- Likes37.8K





Pinned Tweet
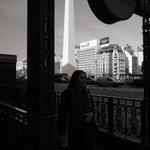
¿Me ayudan con un voto para mi foto "Bajo el toldo de la ilusión" en el concurso nacional #Mexicoenunaimagen? 🔴
👉 Vota aquí: lohechoenmexico.mx/mximg16/m…
¡Muchas gracias por el apoyo y por compartir! 🇲🇽✨

Critical unauthenticated RCE and memory disclosure flaws hit core PHP (CVE-2026-109618/19).
Wild detail: Gemini 4 Argon helped Wiz find and patch them. Google Cloud deployed Cloud Armor edge WAF rules.
Have you checked your PHP clusters today?
Check Google Cloud remediation and Cloud Armor WAF rules → g.dev/cloud/php-core-vulnera…

Framework lock-in is where enterprise AI agent projects go to die.
When platform teams mandate an opinionated SDK, teams using LangChain or custom stacks get boxed out of deployment and eval pipelines.
Today Google opened up the Agents CLI Extension System: bring any framework, keep unified Cloud Run deployment. – at Benito Juárez, Distrito Federal

⚡ Pluggable extension CLI → Scaffold and run LangChain or custom runtimes without touching ADK.
🛡️ Custom policy hooks → Inject automated SBOM scans and security gates directly into pre-deploy phases.
📊 Unified eval pipelines → Benchmark agent trajectories across frameworks with identical test harnesses. – at Benito Juárez, Distrito Federal
Standardizing the agent lifecycle without forcing framework lock-in is a massive unlock for platform teams.
Are you standardizing on a single agent runtime, or building pluggable multi-framework pipelines?
🔗 Full walkthrough: g.dev/ai/agents-cli-langchai… – at Benito Juárez, Distrito Federal

Critical infra and defense cannot export telemetry to public clouds for frontier AI.
Google Distributed Cloud announced air-gapped Blackwell Ultra acceleration, local Gemini, and turnkey ISV apps.
How do you balance data sovereignty with frontier AI compute?
Full architecture & walkthrough here → g.dev/cloud/gdc-sovereign-ai…

Si importar si internet sobrevive o no a la nueva ola de ataques a sitios con PHP, la siguiente semana nos vemos en CDMX - Tech Week Mexico y en Guadalajara - JSConf.
96% of public agencies pilot AI, but only 9% reach production due to compliance siloes.
Gemini for government services brings purpose-built agents grounded in statutes under FedRAMP High.
Can agency-grounded agents solve civil service backlogs?

Full architecture & walkthrough here → g.dev/cloud/gemini-governmen…

No single model wins at every coding task—architectural planning needs deep reasoning, but daily refactoring needs low latency.
Claude Opus 5.5 and Sonnet 5.5 are now live in Google Antigravity IDE & CLI.
Which model tier do you use most for daily coding?
Full architecture & walkthrough here → g.dev/cloud/claude-55-antigr…

Having Opus 5.5 for architectural planning alongside Flash and Sonnet 5.5 for rapid diffs in one IDE under unified enterprise governance is a massive win. ✨ – at Benito Juárez, Distrito Federal

Claude Opus 5.5 and Claude Sonnet 5.5 are now available in @antigravity for @googlecloud customers! g.dev/ai/anthagy #googlecloud #ai #devs
For years, the biggest friction with TPUs wasn't the hardware—it was having to rewrite your entire PyTorch stack into JAX or wrestle with PyTorch/XLA wrappers.
Today TorchTPU went open source at PyTorch Conference: native torch.device("tpu") is officially here, co-developed with Meta. – at Benito Juárez, Distrito Federal
⚡ Native torch.device("tpu") → Debug in eager mode and compile with torch.compile without leaving PyTorch.
🚀 Open serving stack → Drop-in support across vLLM, SGLang, and llm-d for high-throughput inference.
📐 Model Flops Utilization → TorchTitan recipes with SimpleFSDP and Pallas kernels for production MoE scaling. – at Benito Juárez, Distrito Federal
Decoupling model code from hardware lock-in is a massive win for open AI infrastructure.
Are you keeping workloads GPU-only, or testing TPUs now that native PyTorch is live?
🔗 Full walkthrough: g.dev/cloud/torchtpu-open-so… – at Benito Juárez, Distrito Federal

This is seriously funny: 😂 – at Benito Juárez, Distrito Federal

Gemini 4 Argon built a 3D periodic table synced to Tom Lehrer’s song, “The Elements.”
Created in @Antigravity, it animates orbiting electrons, atomic data, and light spectra.
Relying on LLM-as-a-judge without auditing the evaluator is compounding noise at scale.
In production benchmarks, simple option order swaps flip model verdicts 75% of the time, and verbosity bias masks serious bugs. – at Benito Juárez, Distrito Federal
How is your team calibrating automated AI judges against human ground truth?
Three concrete ways to audit model evaluators (adversarial pair swapping, perturbation tests, and Cohen’s kappa consensus):
g.dev/ai/audit-llm-evaluator… – at Benito Juárez, Distrito Federal
