Sudeep Pillai (@spillai) header
Sudeep Pillai (@spillai) profile picture

Buikding visual intelligence @vlmrun, prev @spc, @ToyotaResearch, CS PhD @MIT CSAIL #girldad

San Francisco, CA
Joined August 2008
Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)Photo by Sudeep Pillai (@spillai)
Sudeep Pillai retweeted
New: EmbeddingGemma 2 on the @vlmrun Gateway. One model for text, image, document, video, and audio embeddings. 740M parameters, 768 to 128 dimensions, $0.01 per 1M tokens.
1
2
5
193
Sudeep Pillai retweeted
I made a computer vision demo for detecting full range of motion in pull-ups! Like my previous chin-ups demo, I'm using ViTPose+ Large through the @vlmrun Gateway for pose estimation. I'm using the vertical displacement of the head as well as the elbow angles to detect full range of motion. In the video, you'll see that the reps where I intentionally didn't go high enough, or started with bent elbows, did not count as full reps. The reps where I started from a dead hang and went over the bar did count as a full rep. Of course, everyone's pull-ups may look different, and we can calibrate the thresholds to fit each person better. In short, this could be used to help people understand and improve their pull-ups. Let me know what you think! The code is open-source on GitHub: github.com/jeremyipark/visio…
20
42
5
552
31,143
Sudeep Pillai retweeted
New: Our System One API can now extract JSON fields, fast! Text, numbers, dates, and lists, each read in parallel and returned typed, or null when it's missing. Up to 3.7x faster than constrained JSON schema extraction, and up to 3.3x faster than JSON mode, on the same model. Support for native PDFs (up to 16 pages), images, and text inputs.
2
2
1
5
478
With our new @typesafeai-compatible SystemOne API, you can now extract details like dates, numbers, and lists from images or PDFs up to 3.5x faster (than json-schema mode), with the same VLM backbone! LLM developers have been working with JSON mode and structured outputs (aka JSON-schema mode) for years, but these can be highly inefficient for simpler vision tasks like invoice extraction. We’ve been working hard to bring fast decision-making and field extraction to our SystemOne API, and this is an early preview of the latencies you can expect from the new interface. Infra is one of those things where principled decisions made early start to compound. Expect to see a lot more on this, especially low-latency image and video streaming support for our SystemOne API, in the coming weeks!
New: Our System One API can now extract JSON fields, fast! Text, numbers, dates, and lists, each read in parallel and returned typed, or null when it's missing. Up to 3.7x faster than constrained JSON schema extraction, and up to 3.3x faster than JSON mode, on the same model. Support for native PDFs (up to 16 pages), images, and text inputs.
1
1
5
236
Sudeep Pillai retweeted
Run and compare OCR models side by side on the @vlmrun OCR Playground. For models with grounding, hover any extracted value to see exactly where it came from on the page. Models Supported: PP-OCRv6, LightOnOCR-3-4B, dots.mocr, PaddleOCR-VL-1.6, GLM-OCR, DeepSeek-OCR-2 and more.
1
4
1
7
344
Pretty cool release of strongly-typed object detection with our new SystemOne API on the @vlmrun gateway!
We just added @typesafeai's native Image and Box support to our System One API. Pass an Image as the state, ask Box questions, get the region back as four edges. Same TypeSafe SDK: point it at gateway.vlm.run/typesafe.
1
5
294
Sudeep Pillai retweeted
We just added @typesafeai's native Image and Box support to our System One API. Pass an Image as the state, ask Box questions, get the region back as four edges. Same TypeSafe SDK: point it at gateway.vlm.run/typesafe.
1
2
1
6
474
Sudeep Pillai retweeted
Run and compare open-weight OCR models on the new @vlmrun OCR Playground. Auto-eval and compare costs between several VLMs including PP-OCRv6, GLM-OCR, PaddleOCR-VL 1.6, DeepSeek-OCR-2, and the new LightOnOCR-3! Try the OCR Playground on your own data: chat.vlm.run/#ocr
2
5
30
2,673,900
We're heading into a new era of sports analytics, where any cricket enthusiast or aspiring athlete can analyze their own personal videos and start building an AI-powered personal coach. I spent about 10 minutes fetching clips, extracting bowling form with the @vlmrun gateway and comparing bowling traces from @Jaspritbumrah93, @malinga_ninety9 and others.
2
6
2
62
3,861
Cricket, golf, or any sport where form is everything - I think this will soon get gamified, and young athletes will hone their skills far faster than we did. Here’s the whole thing in one frame: Run-up on the left, release right of centre, follow-through on the right.
1
2
249
Everything on top of this is green-field. Aligning poses so two actions can actually be compared. What buys you control, speed, accuracy; what costs you injuries, and where the leverage is. The whole extraction is < 20 lines. Docs: docs.vlm.run/gateway
2
184
Sudeep Pillai retweeted
September changelog. Lots of exciting updates last month, and lots more to come including new guides and cookbooks.
1
1
5
219
VLMs can be surprisingly accurate and token-efficient on the right tasks. In a bake-off between VLM-based document classification vs. OCR-based classification using our new @typesafeai-compatible SystemOne API, we're seeing over ~7x token-efficiency! VLM: 372 tokens/page, fixed. OCR->Text: 2,002 median, 19,159 on the worst page.
6
25
1
205
11,085
The tail is what breaks at scale. p90 latency, end to end: - VLM: 209ms (+9% over its own p50) - OCR->Text: 1453ms (+168%) You can size a batch for 372 tokens a page. You can't size one for a distribution with a 19k tail.
1
1
404
Sudeep Pillai retweeted
I made a computer vision tool for evaluating deadlift form! I've shared a few deadlift demos in the past. This new demo includes some new models, accessed through the @vlmrun Gateway: - SAM 3.1 to segment the barbell weight plate - ViTPose+ Large to measure the hip hinge angle, which serves as a backup for segmenting the reps. The pose data can definitely be used more later. - Gemma 4 26B through the Gateway's TypeSafe-compatible API to output the probability of the back being rounded or not. The predictions line up well with how I intentionally performed each rep. Of course, there are many caveats to what is good form, as it depends on the individual. All said, this has the pieces in place to quickly make adjustments to fit the individual better. In short, a tool like this gives people data to assess their form and improve over time. Let me know what you think! The code is open-source on GitHub: github.com/jeremyipark/visio…
51
126
11
1,147
92,546
You can now classify documents with open-weight VLMs at ultra-low cost with our @typesafeai Jev-compatible API in the @vlmrun gateway! $1 buys you 6700+ pages, and the full 1,651-page OmniDocBench run cost 25 cents. It reads the page as pixels (no OCR->LLM hacks) and hands back one typed, calibrated decision per page - ~180ms p50 e2e. Jev really opened developers' eyes to re-thinking how we process data at the cost-pareto front. A week later we're bringing that to our APIs with vision as a first-class citizen. Try our gateway today - free to sign-up and try!
10
26
3
358
21,229
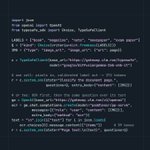
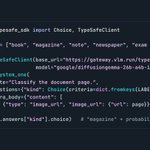
The whole thing is a few lines. Point the official @typesafeai typesafe-sdk at the gateway, ask a Choice, and the answer comes back as a calibrated distribution over exactly your labels - never a string to parse, never off-schema.
1
1
5
882