

Making frontier AI research more accessible
Joined March 2023
- Tweets1.3K
- Following162
- Followers9.5K
- Likes1.2K





Pinned Tweet
Bad news for everyone running LLM-as-judge evals:
Researchers made 10 frontier models write exams for each other. 3,600 rounds.
The smartest model in the room (91.3% accuracy, #1) was the WORST exam-writer. 30% of its questions were invalid. It kept catching its own mistakes mid-check and submitting the wrong answer anyway.
Meanwhile the models that wrote the best tests weren't the top scorers.
Answering and judging are different skills. Nobody's leaderboard measures the second one.

OpenAI shipped Dots today: always-on agent, own cloud sandbox, browser access, hooks into 4,000+ apps.
Anything sensitive needs manual approval. $200/mo, Pro tier only.
Then it froze on stage mid-demo trying to launch a fake app. Kind of proves why the approval gate exists.
Half your backlog is copy fixes and dead links your PM would've made themselves, if they could touch the repo.
@base44's Base Code opens your actual codebase to the whole team from a browser. Changes land as normal PRs. You still merge everything.
50 free coupons, DM me.
State of AI retweeted

Five agents each re-reading a 4,000-token brief is 20,000 tokens before anyone does any work.
One agent reads it once.
Default to fewer, fatter agents until you can show the number that says the split pays. New edition below!
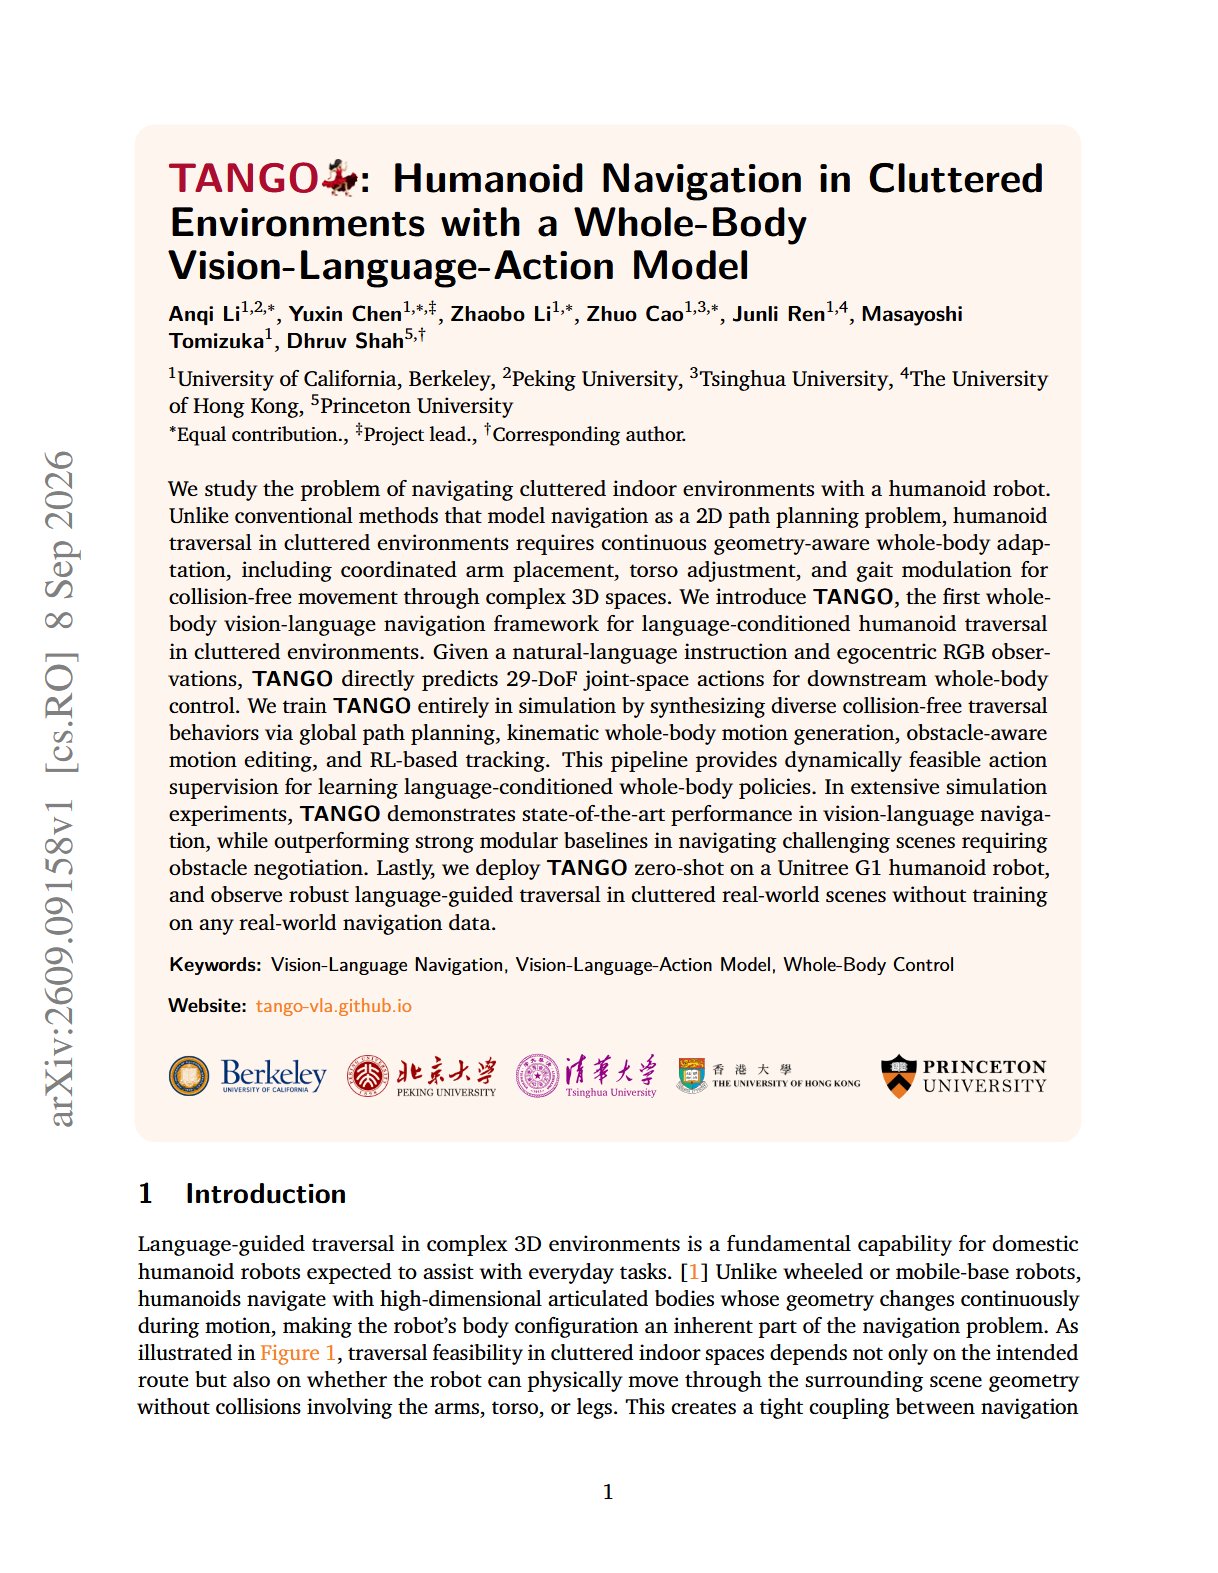
A new model (TANGO) predicts all 29 joint degrees of freedom directly, one network, no separate navigation and control layers.
It beat a baseline that gets to use LiDAR on top of cameras. TANGO only gets cameras. Collision rate: 9.9% vs 15.8%.
On a real Unitree G1, it succeeded 10 out of 15 cluttered navigation trials versus 6 out of 15 for the baseline, trained zero-shot with no real-world data at all.
The whole training set cost 211 GPU-hours. Decomposing the problem was making it worse, not simpler.
This and more in the latest edition!
State of AI retweeted

Tomorrow is a big day for eu1.hubs.ly/H0y8DRF0 🚀
We're launching Viso Now on Product Hunt, built with our hunter Ben Lang. Describe the outcome you want from your camera footage, and Viso Now builds the detectors, alerts, and review logic behind it. No training data, no annotation, no ML team
At the same time, we're hosting Build Vision AI 2.0 at Impact Hub London Euston. Over 200 people registered and it sold out fast. Everyone in the room gets hands-on with Viso Now and builds a real computer vision use case in one evening, on a real camera, no code required.
Stay tune on Product Hunt tomorrow: eu1.hubs.ly/H0y8DRH0
We cannot wait 👀
#ProductHunt #VisoNow #ComputerVision #VisionAI #BuildVisionAI


#10 on Substack's Rising Technology chart today!!!
That's entirely down to everyone who reads, shares, and forwards this to a coworker who's tired of scrolling past AI hype to find the actual research.
Thank you for being here!!!
More good stuff coming. If you haven't subscribed yet, now's a good time.

State of AI retweeted
Stripe replaced Envoy with their own Go proxy and halved both CPU and latency.
At their scale that's ~3,000 days of inter-service latency saved every day.
In this edition we explore why they left Envoy after 10 years, and the connection-count trap that pushed them:
OpenAI just shipped GPT-6 Astra and had to gate part of it, the model got good enough at finding zero-days on its own that it crossed their "critical" cybersecurity line.
If you're on a security team, that vetted defender access is worth requesting.
The 99.9% ARC-AGI-3 number going around is from a favorable harness though. Standard harness: 62.7%.
State of AI retweeted

RIP Rosetta. Apple just told Mac App Store devs they can finally drop Intel support. After 6 years of universal binaries being "the responsible thing to do," it's about to be the only thing that works. Say your goodbyes to that dusty x86 build 🫡