
Stats PhD student at Stanford, formerly at UChicago, interested in causal inference and social science applications
Joined July 2021
- Tweets64
- Following129
- Followers198
- Likes48


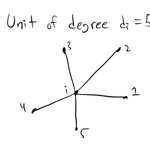
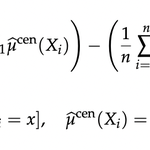



Excited to share a series of blog posts about the work we’ve been doing on AI evaluations @AbridgeHQ!

The second post starts to dig deeper into what we evaluate for our clinical note generation product specifically, including a list of 10 of the 50+ measurable dimensions we use to assess and improve note quality.
tech.abridge.com/blog/what-m…
For more on the rest of the series, check out @cathychen23's thread on some of the other posts!
xitter.cf/cathychen23/status/209…

How do we design evaluations that improve AI for real world healthcare?
I’m excited to share our work tackling this @AbridgeHQ! We’re releasing a series of blogposts to highlight our eval science, with a deep dive into one of our core products: ambient documentation.
1/12

The second post starts to dig deeper into what we evaluate for our clinical note generation product specifically, including a list of 10 of the 50+ measurable dimensions we use to assess and improve note quality.
tech.abridge.com/blog/what-m…
For more on the rest of the series, check out @cathychen23's thread on some of the other posts!
xitter.cf/cathychen23/status/209…
How do we design evaluations that improve AI for real world healthcare?
I’m excited to share our work tackling this @AbridgeHQ! We’re releasing a series of blogposts to highlight our eval science, with a deep dive into one of our core products: ambient documentation.
1/12
Check out the rest of the series for more details on how we evaluate our note generation product, and stay tuned for posts about how we evaluate our other products as well!
(Or take a look at this great thread by @cathychen23 , one of the other awesome authors of this series: xitter.cf/cathychen23/status/209…)
How do we design evaluations that improve AI for real world healthcare?
I’m excited to share our work tackling this @AbridgeHQ! We’re releasing a series of blogposts to highlight our eval science, with a deep dive into one of our core products: ambient documentation.
1/12
The second post starts to dig deeper into what we evaluate for our clinical note generation product specifically, including a list of 10 of the 50+ measurable dimensions we use to assess and improve note quality.
tech.abridge.com/blog/what-m…
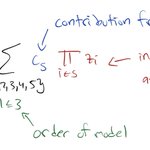
Excited to share new work with @jugander, Matt Eichhorn, and Christina Lee Yu on combining experimental design and outcome modeling for causal inference under network interference
arxiv.org/abs/2405.07979

More broadly, these results suggest that rather than asking “what is a good estimator for a Bernoulli design” or “what is a good design for an IPW estimator” we should be asking “what are good estimator/design pairs”
See the arXiv draft for more theoretical results, simulations showing how our bounds can be used to inform experimental designs, and comparison of complete randomization vs. Bernoulli randomization!
arxiv.org/abs/2405.07979