

Research Scientist @NVIDIA | CS PhD @IllinoisCDS | MSCS @ucsd_cse | BSEE @Tsinghua_uni
Joined October 2019
- Tweets94
- Following877
- Followers1.4K
- Likes651



Shaowei Liu retweeted

📣 NVIDIA is releasing a collection of open model weights: Nemotron-Labs-Sigma — 14 checkpoints at 3B/8B.
Language models have stayed discrete. We bring continuous diffusion to language as in vision.
Smooth ODE trajectories (16-D) unlock distillation and steering: 8 TPFs for math, 4 TPFs for code, with accuracy and diversity preserved. 🧵 1/

Shaowei Liu retweeted

Tired of waiting for your diffusion models?
🚢 We just shipped a major FastGen update:
- new models: H3, LTX-2.5, LingBot-World, Cosmos 3, FLUX.2
- new methods: PDD, AYF, AnyFlow, Causal Forcing
- new features: multimodal distillation, image editing, camera conditioning, KV cache management, ComfyUI
🔗 Try it out here: github.com/NVlabs/fastgen
Shaowei Liu retweeted

Avengers assemble: 1 year BakerLab + NVIDIA GenAIR = 🔥 rfd4-proteina.org
Presenting RFD4-Proteina, our latest protein design model, significantly better and faster than everything we compared against, both in silico and in the lab! 1/30
Shaowei Liu retweeted

🚀 Huge congrats to Hao AI Lab @ UCSD on FastH3 Omni!
Achieving up to 12× lower latency on NVIDIA Blackwell using NVFP4 QAD and FastGen PDD + DMD.

As promised, FastVideo open-sources @MiniMax_AI FastH3 Omni, training code included! 🚀
- Real-time gen @ 12x faster on NVIDIA Blackwell
- NVFP4/FP8 for Spark + RTX!
- ComfyUI day-0
Collab with @NVIDIAAI , Nuva Lab @nuvalab and Reactor @reactorworld
Open source must win! ♥️
Shaowei Liu retweeted
The latest result of our amazing collaboration between FastVideo and FastGen: FastH3 Omni
- 12x faster reference-to-video (image, video, & voice references)
- distilled using our new combination of PDD & DMD
Blog: haoailab.com/blogs/fastvideo…
PDD: teapawt.net/julberner/status/20825…
As promised, FastVideo open-sources @MiniMax_AI FastH3 Omni, training code included! 🚀
- Real-time gen @ 12x faster on NVIDIA Blackwell
- NVFP4/FP8 for Spark + RTX!
- ComfyUI day-0
Collab with @NVIDIAAI , Nuva Lab @nuvalab and Reactor @reactorworld
Open source must win! ♥️
Shaowei Liu retweeted
Check out RVM: simple, effective RL fine-tuning for diffusion models ⚡
Roll out (no grads) → compute rewards → re-noise → reward-weighted velocity regression + anchoring
Unifies previous approaches and scales to video models with SOTA performance!

Shaowei Liu retweeted

💫 Large Language Continuous Diffusion Models
Presenting Sigma, the first large-scale (3B/8B) continuous diffusion LM (dLM) trained with likelihood.
📈 Comparable with discrete dLMs and AR on math and coding
🎛️ Enables meaningful study of inference-time interventions
Jointly led with Wei Guo (@WeiGuo01), Jean-Marie Lemercier (@jm_lemercier), Simon Welker (@_cobalamin)
Team: @YongganFu @mmkamani7 Sajad Norouzi @julberner @tomasgeffner @karsten_kreis @YongxinChen1 @MoleiTaoMath @jwthickstun @PavloMolchanov Ante Jukic @ArashVahdat @MardaniMorteza
Shaowei Liu retweeted
Excited to collaborate with @RekaAILabs on real-time steerable video generation using FastGen! 🎬
Check out our FastGen repo - we will also drop new models and methods soon: github.com/NVlabs/fastgen


Together with @nvidia , we've built a real-time version of our video generation model: 30B parameters, steerable mid-stream in natural language, 720p at 24fps.
11.8x faster on a single H100, no major quality drop in our blind eval.
We're one step closer to World Language Action Models: AI that doesn't just generate the physical world, it acts within it.
Closed beta open now, contact us for access.
reka.ai/labs/research/real-t…
#RekaLabs #NVIDIA #AIResearch #VideoGeneration #WorldModels
Shaowei Liu retweeted
Having worked with many distillation methods for accelerating diffusion & flow models, I’m still blown away by the simplicity of Parallel Decoding Distillation (PDD).
1️⃣ State-of-the-art quality and diversity with variable NFE
2️⃣ First to scale trajectory-distillation to few-step video generation
PDD is about as cheap and simple as it gets:
🎯single, regression-based MSE loss using 1 student & 1 detached teacher forward
❌NO data required
❌NO adversarial loss or alternating training
❌NO JVP or finite-difference approx.
❌NO additional time-embedding or trainable models (e.g. fake score, discriminator)
❌NO stabilization tricks (e.g. normalization, clipping, warm-up)
Shaowei Liu retweeted
⚡ Video diffusion is slow. PDD changes that.
🚀 Introducing Parallel Decoding Distillation, our latest work on accelerating video diffusion models.
Paper: arxiv.org/abs/2607.26004
Page: research.nvidia.com/labs/gen…
By @shaulneta, @julberner, and Chao Liu.
Below PDD on LTX-2.3 🔊
Shaowei Liu retweeted
Flex-Forcing trains a single model to do both autoregressive and bidirectional generation, letting you choose from the range at inference based on your compute budget!

Our research team just released Flex-Forcing: a video generation method that lets a single model switch between generation methods at inference time.
Right now there are two main approaches to video generation. Bidirectional diffusion models attend to every frame at once, holding structure well at the cost of speed. Autoregressive models generate frame by frame, so they stream fast and scale to long clips, but accumulate error and drift over time.
Flex-Forcing trains a single model to do both, letting you choose from the range at inference based on your compute budget.
Shaowei Liu retweeted

1/n Thrilled to open-source DFD (Data-Forcing Distillation) — a one-line fix that restores diversity and fidelity in DMD for few-step video distillation. No GAN, and just 100–300 finetuning steps. It improves on three video generation tasks: text-to-video, image-to-video, and autoregressive video generation. The core idea is to learn from the scores of real data during distillation. DFD further improves frame coherence and physical plausibility.
Everything is public: paper, code, pretrained model, and data.
Paper: arxiv.org/abs/2606.18478
Project page: csy2077.github.io/dfd-projec…
Code, model, and data: github.com/csy2077/data-forc…
#VideoGeneration #DiffusionModels #AI #OpenSource
Shaowei Liu retweeted

What is missing to bring real-time motion research into AAA games and real-world robotics?
We present MotionBricks, a step toward bridging this gap with two key components:
- a single generative latent motion backbone covering 350,000+ motion skills, running at 15,000 FPS with 2 ms latency and substantially improved quality and reliability.
- a unified smart primitive interface for locomotion, object / scene interaction, with fine-grained control over generated behaviors.
Webpage: nvlabs.github.io/motionbrick…
Code: github.com/NVlabs/GR00T-Whol…
Paper: arxiv.org/abs/2604.24833 (ACM TOG / SIGGRAPH 2026)
Shaowei Liu retweeted

We scaled up Lyra to generate explorable 3D worlds! 🚀
Introducing Lyra 2.0 — turning a single image into a 3D world you can walk through, look back, and even drop a robot into 🤖
Code and Model available today!
🌐 Website: research.nvidia.com/labs/sil…
(1/N)
Shaowei Liu retweeted

MoRight tackles a core problem in controllable video generation: disentangling camera motion from object motion.
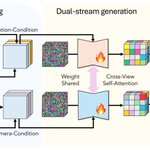
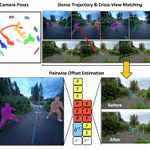
Unlike prior methods that rely on dense future-frame tracks, MoRight uses only first-frame reprojected trajectories + camera poses, yet achieves comparable quality and better motion control.
Shaowei Liu retweeted

When doing motion-conditioned video generation, we think the key is in understanding motion causality (what action will lead to what outcome) and camera-motion decomposition (camera changes shouldn't entangle with object dynamics).
MoRight is the first step towards this goal. We support three functionalities:
1. "Simulation": Users provide the action (e.g., moving hands), and the video model generates the consequences (e.g., cups moving and pouring water)
2. "Planning": Users specify the outcome (e.g., balls moving), and the video model generates the action that drives the outcome (e.g., moving legs)
3. "Disentanglement": Users can independently control the camera change and object dynamics, all along with the motion causality mentioned above.
Come and check it at research.nvidia.com/labs/sil…
P.S. Shaowei is in the job market; you shouldn't miss him!

📢MoRight: Motion Control Done Right
"What if your video model actually understood cause and effect?"
Existing motion-controlled video models entangle camera and object motion, and treat everything as kinematic displacement. MoRight changes both.
🔥 Motion Causality — MoRight decomposes motion into actions & consequences. Give an action → MoRight predicts consequences (aka motion simulation) . Give a desired outcome → MoRight recovers the driving action (aka motion planning). Not merely displacing pixels.
🎬 Disentangled Control — MoRight separates camera and object motion, allowing users to independently control each of them. No entanglement.
Project Page: research.nvidia.com/labs/sil…
Paper: arxiv.org/abs/2604.07348
Shaowei Liu retweeted

🕹️We are excited to introduce "ChronoEdit: Towards Temporal Reasoning for Image Editing and World Simulation"
ChronoEdit reframes image editing as a video generation task to encourage temporal consistency. It leverages a temporal reasoning stage that denoises with “video reasoning tokens” to "reason" on physically plausible edits.
See the attached video for results.
Project Page: research.nvidia.com/labs/tor…
Arxiv: arxiv.org/abs/2510.04290
Code and model are coming.
Shaowei Liu retweeted

[1/N] 🎥 We've made available a powerful spatial AI tool named ViPE: Video Pose Engine, to recover camera motion, intrinsics, and dense metric depth from casual videos!
Running at 3–5 FPS, ViPE handles cinematic shots, dashcams, and even 360° panoramas.
🔗 research.nvidia.com/labs/tor…
Shaowei Liu retweeted
We are excited to share Cosmos-Drive-Dreams 🚀
A bold new synthetic data generation (SDG) pipeline powered by world foundation models—designed to synthesize rich, challenging driving scenarios at scale.
Models, Code, Dataset, Tookit are released.
Website: research.nvidia.com/labs/tor…
Shaowei Liu retweeted
🚀Excited to introduce GEN3C #CVPR2025, a generative video model with an explicit 3D cache for precise camera control.
🎥It applies to multiple use cases, including single-view and sparse-view NVS🖼️ and challenging settings like monocular dynamic NVS and driving simulation🚗.
Project page: research.nvidia.com/labs/tor…