

AI engineering, cybersecurity, local LLMs, ai tools, open source
Joined June 2013
- Tweets1.3K
- Following623
- Followers709
- Likes2.7K



Pinned Tweet
Local Qwen generates 234 tok/s in JSON format. In plain text, only 70
The same local AI model: 70 tok/s in prose and 234 tok/s when generating JSON.
More than 3 times faster. Without changing hardware.
In Qwen3.6-35B-A3B-Splash tests on Mac mini M6:
- EN Prose: 69.6 tok/s
- Python Code: 135.9 tok/s
- JSON Extraction: 234.1 tok/s
Why? Speculative decoding works better when subsequent tokens are easier to predict.
Repetitive JSON and code structures can provide much greater speedup than ordinary conversation.
teapawt.net/swarogan/status/210392…

Swarogan retweeted

Introducing point spread/handicap markets for the NFL. New NBA markets also live.
All on @propSPACEfun
Start trading: propspace.fun
Discord: discord.gg/HTfEZbZnvx


Swarogan retweeted
Good one. Anthropic is removing the 5 hour limits from 20x plans
Most users would prefer to burn through the weekly limit when they want, especially since most heavy developers have maybe more than 1 account and don't mind booting up another account to burn the rest of the week (I know someone who has $200 codex and $100 Claude).
Outside of that case - a lot of us also prefer to sit down and knock out side projects on the weekends, which the 5hour limit is very prohibitive against.

We’re renaming our Max plans:
Max 5x → Max
Max 20x → Ultra
Max is still $100/month, and Ultra is still $200. If you’re a subscriber, there’s nothing you need to do.
We’re also removing the 5-hour limit for verified Ultra accounts, starting today with most existing subscribers. Newer accounts keep a temporary limit until they’re verified, which helps us prevent fraud and abuse. You'll get an email when it's removed.
Weekly limits remain unchanged. View our plans here: claude.com/pricing

Chinese AI models failed in building SaaS products!
Chinese AI models failed! DeepSeek, GLM, and Kimi did not complete a single full project in the new Replit benchmark.
DeepSeek V4.1 Flash: 0%
GPT-6.1 Sol: 64.7% (best result)
And do you use open source models to build your own SaaS products? How do they perform?

Source: fireworks.ai/specialized-int…

Source: fireworks.ai/specialized-int…
Someone turned DOOM into a neural network runtime.
No CUDA. No PyTorch inference.
The game engine itself performs the math using map geometry and game mechanics.
It even classified 966 out of 1,000 handwritten digits correctly.
At this point, what CAN'T run AI?

Github: github.com/mottopanikeiku/do…


Someone just built a 32-bit RISC-V CPU INSIDE Qwen3.5-4B. And arithmetic accuracy jumped from 48.6% to 100%.
No external Python interpreter. No tool execution. The CPU runs directly inside the model's forward passes.
The project is called Qwenputer:
- A real 32-bit RISC-V CPU compiled into the model's weights
- Gated DeltaNet state used as RAM
- Runs C and MicroPython programs internally
- Qwen's original weights remain unchanged
Instead of predicting the result of a calculation, the model can actually execute instructions to compute it.
teapawt.net/divagr1925/status/2115…

GitHub: github.com/divagr18/qwenpute…
Model: huggingface.co/divagr1925/Qw…
Technical write-up: divagr.com/blog/qwenputer

Which AI agent would you trust to run your business while you sleep?
Grok Bot, OpenBot, Hermes Agent, or something you built yourself?
Benchmark of 16 local LLMs - results and script: github.com/HDZucht/Mac-Mini-…

1,035 tokens/sec on a single RTX 3090. Running Qwen3.8-27B.
Someone just released HyperQwen, an open-source project pushing Qwen3.8-27B to some ridiculous inference speeds using an optimized version of vLLM.
The benchmark results:
1,035 tok/s across 64 concurrent requests
381 tok/s on prompt-reproduction tasks
127 tok/s for a single user
Up to 262K context
All on one RTX 3090 with 24GB VRAM.
No new hardware. Just aggressive inference optimization.
HyperQwen is on GitHub
HyperQwen:
github.com/syv-ai/HyperQwen

NVIDIA limits the performance of its graphics cards. Someone has found a way to remove this limit.
The gpu-unlock project unlocks the full BF16 performance of Tensor Cores on RTX 20, 30, and 40 series GPUs.
BF16 results:
RTX 3060: 27 → 51 TFLOPS (+87%)
RTX 3090: 75 → 125 TFLOPS (+65%)
RTX 4080: 104 → 193 TFLOPS (+87%)
The author also reports 25–55% faster LLM prefill, 25–50% faster fine-tuning, and 30–55% faster image generation.
No BIOS flashing or NVIDIA driver modifications required.
The project is free and available on GitHub 👇
GitHub: github.com/Zagitta/gpu-unloc…
It is worth checking the requirements and limitations before use. Not all AI applications accelerate to the same extent.

Gemini 4 Argon finally came in handy for something.
It improved the vllm code, speeding up Gemma4 E2B performance by almost 3x, without losing token consistency or quality.
On A100, it's a jump of up to 108k t/s
And I'm still waiting for Gemma5
teapawt.net/googlegemma/status/211…

Speeding up Gemma!
Gemini 4 Argon enabled a 2.85x speedup on an A100 via vLLM, jumping from ~37,900 to 108,000+ tokens/sec on gemma-4-E2B-it.
✅ 100% token parity
✅ Zero quality drop
✅ Done in days, not months
See the exact changes across 8 PRs: goo.gle/4zNtANl
Small local models are useless for coding.
Or are they?
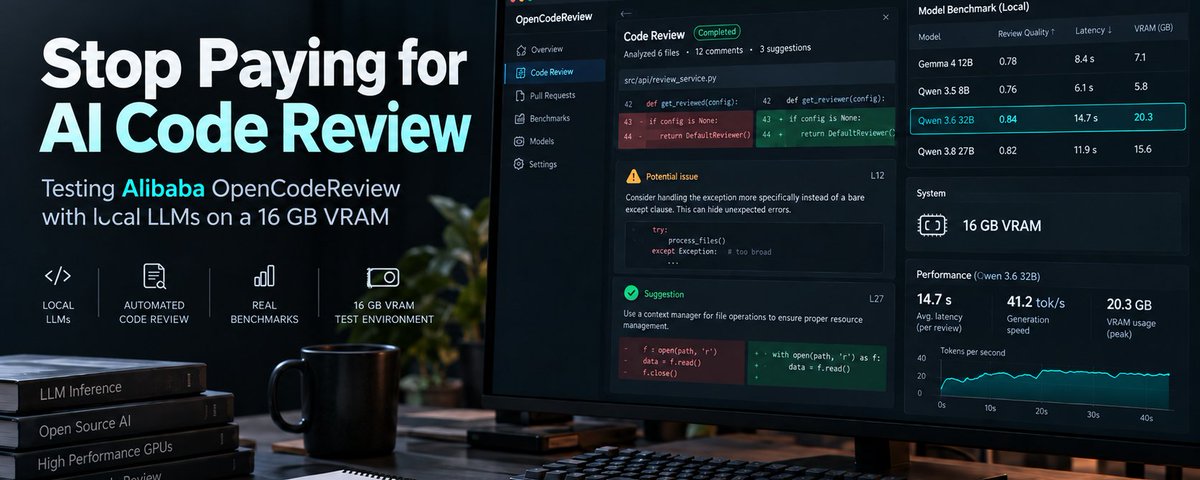
I use small local models daily for various tasks. Sometimes I run OpenCodeReview, but mostly I use them for automation: reviewing new tickets for my SaaS products, checking emails, etc.
But can they actually code?
To find out, I built a testing harness to measure their coding performance, see whether MTP helps with code generation, and more.
I'll release the whole thing as open source on GitHub. Feedback is welcome. teapawt.net/swarogan/status/210392…