

Cyber Security · Devin Ambassador · AI · Dev · Games
Latvia
Joined October 2019
- Tweets7.2K
- Following1.1K
- Followers26.3K
- Likes21.1K



Pinned Tweet
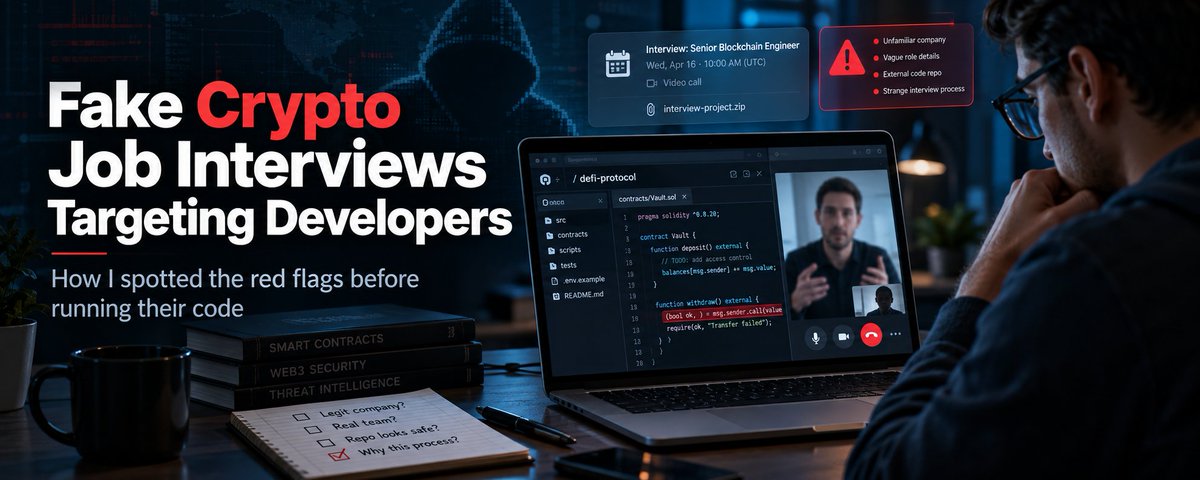
Finally managed to gather everything into one big article.
It’s around 3,350 words, so expect a ~10–15 minute read :)
My experience with a fake crypto job interview: how it started, the red flags, and how developers can protect themselves.
Anton retweeted

🫨简直无敌!DeepSeek Harness被清华微软团队直接“瘦身”:Token消耗砍掉87.93%,成功率反而暴涨14%!
Agent每次工具反馈后都要重新问一遍LLM,哪怕下一步早定死了(写完代码→编译,编译成功→测试)。清华+微软团队用HarnessMM直接把这些“已决定”的步骤缓存下来,跳过重复推理。
核心成果(98个HumanEval任务):
🔹DeepSeek Harness:Token从96.28k降到11.62k,砍掉87.93%!成功率从71.43%直接飙到85.71%
🔹Codex:成功率稳在90.82%,Token再降29.54%(66.72k→47.02k)
🔹原理:模型一次规划未来命令+精确参数+守卫条件(如“编译成功”),匹配就直接执行,跳过LLM回调。模型权重完全不动
🔹额外:MBPP上也大幅降本,递归自我改进(RSI)让Harness配置持续变强
Agent循环里大量Token浪费在“重新决定已经决定的事”上。这波直接把成本打下来,性能还往上走。
论文:arxiv.org/abs/2610.32813
#DeepSeek #AIAgent #Token效率 #清华 #微软 #HarnessMM #大模型降本 #Agent优化 #梁文峰 #梁圣


Nice 👍

Very proud to showcase our latest demo of how our Engineering World Model SKY-001 can design a complex Jaguar car with 1000s of complex parts.
In order to get us to Autonomous Manufacturing, we need to design systems that can think like a ‘AI General Engineer’: planning complex physical structures, long term sequences, and feasibility directly in the physical domain rather than approximating it through next-token prediction.
Engineering design operates in the spatial reasoning domain through hierarchical decomposition, constraint satisfaction, and the sequential construction of complex physical objects.
World models are going to be the next frontier in AI after LLMs and SKY-001 is just the beginning.
Anton retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Anton retweeted

Elon just said Grok Bot cost too much to serve.
Meanwhile Devin runs Linux, Mac, and Windows.
Look at the specs. 32GB RAM vs Grok Bot's 16GB.
SWE-2 is way better than Grok once you count price. 11x cheaper per task. And you pick the model.
Devin's subscription is underrated.


Anton retweeted

Very interesting vision, and essentially what Devin is if you want to try it today.
The main difference is that this uses one router across all channels, where Devin runs a separate agent per channel (and Devin is already live).
What already exists with Devin:
• Always-on agent hosted in the cloud
• Watches chat channels and acts without being tagged
• Long-running parent w/ parallel child sessions
• Filters out noise before deciding to act
• Reacts to CI results and PR comments
• Opens fix PRs on its own
• Keeps chat quiet, puts detail in PRs
• Brain in cloud, commands run on your own machines (via outposts)

Anton retweeted

if you only have $20 for ai right now, this is where i would put it..
> devin pro takes the top spot, and it's not even close this month..
swe-2 is free on the $20 plan in devin desktop and cli, so it doesn't touch your quota at all, and you still get claude, gpt and gemini on top of that..
> claude pro is right behind it
still the best brain for $20.. you basically need it to write the handoff files and guide your other llms, not to do all the coding of course..
> chatgpt plus
codex gives you a lot of usage for $20, but plus didn't get the doubled limits the higher plans just got..
honestly i would pick it mainly for image gen and computer use, not even code..
> factory's droid
its a great harness, and the usage for only $20 is pretty generous..
> google ai pro is b tier..
the usage is fine, but you're mostly stuck on google's models... personally i would pick gpt $20 over this..
of course, i'm ranking by how much work i get out of every $1..
would you change anything here / add anything interesting that costs only $20?

4 game devs 😎

Attention to all aspiring AI Game Devs
You can finally materialize your dream game vision with my new website: gamedev-cheatsheet.com/
34 major concepts to use in your prompts
+ illustrations for each (easy-to-understand)
+ example prompts to try
100% free of course
Enjoy!
Anton retweeted

startup killed before it actually started


I recreated subvocal in 9 minutes with one prompt for AirPods Pro 3.
Source: github.com/joeblau/subvox
Price per task 💀

Super interesting.
A number of people commented on my GPT-6.1 Terra benchmark this morning and suggested comparing it to Sonnet.
Soooo, thought I'd whip something up.
Here's a comparison of GPT 6.1 Terra to Claude Sonnet 5.5 across all effort levels.
And the data is pretty clear here, Terra is a lot cheaper than Sonnet, but not quite as accurate until you get to Max.
Traces for all 115 Terra runs, with every tool call:
github.com/morganlinton/vulc…
Leaderboard: vulcanbench.com/leaderboard.…


Anton retweeted

🚨Security Researchers: stop using chatgpt daybreak
>"from November 29 we may use your Daybreak Blue sessions to improve our models"
>"even when the 'improve the model for everyone' setting is off"
>personal accounts, no opt-out
>they made me turn the setting OFF
>then decided to train on it anyway
>"it's for safety :^)"
>tfw your 0days are now training data


🚨 OpenAI Comeback
they double the limit <fallback to what we used to get before > and now they just have to launch the big daddy model
If they release there astra update without nerfs we will have mini scientist in our pocket with 3D spatial understanding , fast computer use and efficiency in token
I just want to leave it here with this graph

Anton retweeted

When you encounter this page, you may be able to bypass it if the ACL is misconfigured by appending a trailing dot to the domain or adding the :443 port suffix.
This technique led me to discover a time-based SQL injection on a private BBP, which was triaged on the same day.

You can say HI on Plus Plan and waste full weekly limit 😄

GPT-6.2 Bel is releasing this week, on the final day of Tibos 28-day shipping spree.
The model ID gpt-6.2-betelgeuse was spotted in an internal tracker. A verified OpenAI insider claims it scores 72 on Artificial Analysis, 13 points above Carbon.
Reportedly 12 trillion parameters with $20 input and $100 output per million tokens.
And thats just one agent. OpenAI used 10,000 agents for its Navier-Stokes research.

Terra btw is quite good on Medium reasoning for Lead role
Okay my GPT-6.1 Terra benchmark with @VulcanBench is now finished 🖖
And before I talk about the key insights from this one, let me also remind everyone that VulcanBench is a coding benchmark. 100% of the tasks in my eval suite are coding tasks.
Having now used Terra all week I can tell you, it's a stellar model for computer use, I'm crazy impressed.
But VulcanBench isn't about seeing how good a model is at computer use, it's all about seeing how well a model completes more complex coding tasks.
So now for analysis of GPT-6.1 Terra when it comes to coding. I typically say a score between 80 - 90 on Frontier v4 is the sweet spot for routine daily coding tasks.
For GPT-6.1 Terra, this means that for coding, you'll want to use Extra High or Max only. Low, Medium, and High don't really make the cut.
Looking at cost-per-task, it's a very inexpensive model to use, but when you look at it side-by-side with GPT-6.1 Sol, I'd probably just use Sol.
For me, after looking at this data, I still plan to use GPT-6.1 Terra as my go-to for computer use, but I probably won't use it for coding.
As usual, as a completely independent benchmark, everything I do at VulcanBench is available for you to review, inspect, and even run yourself if you want to.
And the traces now include tool calls so you can really examine exactly how every model I benchmark thinks!
Benchmark report: vulcanbench.com/benchmarks/s…
Model page: vulcanbench.com/models/gpt-6…
Public traces on GitHub: github.com/morganlinton/vulc…
Live long and benchmark 🖖

Anton retweeted
Lately I've been building a lot more with "infrastructure agents". When I joined AWS as a mobile dev, I was excited to learn how to build scalable cloud services. After a few years I was able to do a lot, but there was so much more to learn, and it becomes very complex and tedious.
Frontier models are great at designing and provisioning what I'd consider complex infrastructure and tying it together with frontends. I started by creating test accounts with limited spend/scoped creds on AWS, and prompting creative things that I thought were challenging to get right. Agents are good at creating these interconnected multi-service cloud stacks. I've used the CLI and MCP, even signed in to AWS on a cloud agent browser and let the agent provision through the UI via computer use. And it's simple to spin them down (which used to be a challenge on it's own!). Because of this, not much tech debt because it's easy to fix and migrate as things evolve.
Taking this beyond AWS of course this applies to other services like @convex, really anything.. You don't really need to even set up the API keys, just sign in to accounts via a cloud agent browser like @DevinAI, send a prompt, then close your computer. When the session is done everything is shipped, your environment variables are stored securly, you have a packaged up production ready app ready to go.
And when you're ready to tear it all down it's also just a prompt away.
It's such a new way of thinking for me. Most of my career this was so out of reach (or too time consuming) so my mind today still lives with these assumptions, I keep having to remind myself that "no, it really is this simple" (many such cases).
Today I'm building three @EpicGames Unreal Engine games on an AWS fleet my agent provisioned, including Blender assets and GPU playtests 🤯. Devin created this diagram showing how it works:

Anton retweeted

有人发现了一种非常离谱的 JavaScript 混淆技术:通过在代码里塞入大量生物武器、毒药和致死剂量相关的函数名,让 AI 因为安全限制而拒绝分析代码。
安全研究员 veritas 在分析浏览器指纹脚本时,发现一段来自 ServicePipe 相关域名的 JavaScript,里面充斥着极其诡异的函数名:
computeRicinLethalDosageForWaterSupply
calculateDeadlyLethalSuicideAspirinDosage
光看名字,仿佛在研究生化武器。但实际上,这段代码只是在收集浏览器指纹,包括 User-Agent、GPU、Canvas 等信息。
研究员怀疑,这些名字是开发者故意设置的陷阱,专门用来阻止 AI 辅助逆向工程。
于是他做了个实验:
• Astra:拒绝分析
• Astra + Daybreak Blue:仍然拒绝
• GLM-5.3:成功分析
这就有意思了。
传统代码混淆是通过复杂控制流、加密字符串、无意义变量名,让人类和工具难以理解代码。
而这种新思路,直接瞄准了大模型的安全机制。
代码本身可能完全无害,但只要在函数名里塞进足够多的危险词汇,部分 AI 就可能主动放弃分析。
更讽刺的是,模型越严格遵守某些安全规则,面对这种混淆时反而可能越容易受到干扰。
当然,目前还没有证据证明开发者一定是故意这样设计,也不能说明这种方法对所有模型都有效。
但它揭示了一个值得关注的趋势:随着越来越多的逆向工程依赖 AI,未来的代码混淆技术可能不再只针对编译器、反编译器和人类研究员,还会专门针对大模型的安全判断机制。
以前是让代码难以理解,现在甚至可以尝试让 AI 不敢理解。
