

Expert Human Data for AI Training & Evaluation—Trusted by Top AI Labs, Startups, and Global Enterprises
Amsterdam, Netherlands
Joined November 2020
- Tweets588
- Following80
- Followers22.1K
- Likes232





Toloka teamed up with @xmemory_ai to test 11 leading AI models on complex, real-world agentic tasks to see whether long-term memory actually improves AI agents.
Here is what we learned when comparing a full memory stack against standard document search alone:
- Quality gains are universal: Across every model tested, adding structured agent memory improved performance over document search alone.
- Better performance, lower cost: Models like Kimi K3, Haiku 4.5, Sonnet 5, and DeepSeek V4 Flash achieved higher accuracy while lowering total cost per trial.
- Memory outperforms scale: Smaller, fast models paired with memory can outpace larger models relying solely on standard retrieval.
Read the full research write-up: toloka.ai/blog/toloka-and-xm…

We trained a model with zero coding data. Its coding benchmark score went up anyway.
After 1 epoch of RL on non-coding enterprise tool use (customer support, travel, HR), Qwen3.5-27B jumped 39.8% → 45.7% on Terminal-Bench 2.1 (+5.8pp, 95% CI [+1.6, +10.2]).
Even bigger gains in consistency:
🔹 Tasks passed on all 3 attempts: 24.8% → 33.3% (+8.5pp)
🔹 Out of 21 "hit-or-miss" tasks (solved 3-4/5 times by base), the trained model now hits 100% pass rate on 9 of them.
Why? The model learned a behavioral primitive: check before you act.
Before RL, it consulted the knowledge base before its first write 49.6% of the time. Post-RL: 81.5%.
That habit of verifying context directly carries over to terminal workflows.
Cross-domain transfer stack so far:
• +44.0pp on held-out enterprise envs
• +9.6pp on AutomationBench Ops
• +8.9pp on τ³ retail
• +5.8pp on Terminal-Bench 2.1
• +4.3pp on Toolathlon
Cost: 1 epoch / 72 steps / ~$26 in LLM judge costs.
toloka.ai/blog/what-one-epoc…

When 95% benchmark accuracy still means 5% production risk, the definition of "verified" has to change.
At Toloka Talks NYC (Oct 28), we’re asking: What does true AI verification look like in the wild?
Join @TolokaAI CEO @OlgaMegorskaya alongside leaders building at the frontier:
🔹 Shopify CTO @MParakhin
🔹 Liquid AI CEO @ramin_m_h
🔹 Reflection AI's @ArnaudStiegler
Followed by invite-only dinner roundtables with senior AI leaders.
discover.amzai.events/toloka…


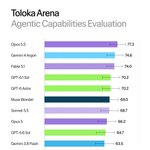
⚡ Efficiency & Cost:
• Highest parallel tool calls (1.55/turn)
• 45% fewer tokens processed vs Opus 5.5 (~131M vs ~238M)
• Costs $0.14/trial vs $0.23 (Opus 5.5) & $0.52 (Fable 5.1)—40% cheaper for tied performance.
🛡️ Smart real-world behavior:
Pauses for required user consent in travel tasks, runs full pre-checklists in cargo workflows, and self-corrects on tool validation errors.
Huge step-up over Gemini 3.1 Pro (+64.6 pts)! Congrats @GoogleDeepMind
🔗 toloka.ai/arena

What does it actually take to verify AI results beyond public benchmarks?
Join us at Toloka Talks NYC (Oct 28) with @TolokaAI CEO @OlgaMegorskaya, Shopify CTO @MParakhin, Liquid AI CEO
@ramin_m_h and Reflection AI's @ArnaudStiegler to dive into how enterprises and labs are approaching this question.
Request your seat 👇
discover.amzai.events/toloka…

Great release from the @tavilyai team!
Automated web parsing can miss critical context on complex queries. To solve this, Tavily used the @TolokaAI Platform to integrate domain experts directly into their evaluation pipeline to establish ground truth data.
Proud to partner with them and @nebiusai on building this!

We just released Tavily’s Company Search Benchmark, built around how AI agents search for company information in production.
It measures how well a single search response gives an agent the evidence it needs to produce a useful, correct answer across company profiles, financials, and news.
Explore the dataset and evaluation approach, then put search to the test with your own queries, workflows, and production model.
This benchmark is powered by the combination of @nebiusai Token Factory and @tolokaAI. Learn more: hubs.li/Q04B0YkT0

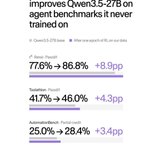
We trained Qwen3.5-27B for one epoch on our enterprise agent data. On agent benchmarks it never saw:
- τ³ retail: 77.6% → 86.8%
- AutomationBench: +3.4pp, +9.6pp on Ops
- Toolathlon: +4.3pp
What it learned: check the policy before changing anything.
Full methodology, design, and benchmark results:
toloka.ai/blog/what-one-epoc…


Are you paying frontier prices for narrow, repetitive tasks?
You can now fine-tune open models directly on Toloka — completely self-serve, right from your coding agent.
What we saw on our own CV parser using a fine-tuned Qwen3-8B adapter:
📉 Inference cost dropped 12–37×
📈 Accuracy (F1) jumped from 0.85 → 0.94
Watch the 2-min demo to see how it works. Try it yourself in Claude Code:
platform.toloka.ai/agents/fi…
Toloka retweeted

Great discussion on Closing the Gap: Can Open Models Match Frontier Performance and How Would You Even Know? [Link below]. This is the first event in the series. Keep an eye out for more events like this.
Got a rare opportunity to take selfies with @MParakhin (CTO, @Shopify and 2026 Time Executive of the Year), @the_bunny_chen (co-founder, @FireworksAI_HQ), and Sunzay Passari (Global Head of AI Transformation @UPS).
Thank you @vaibhav118, @MegorskayaOlga, and the @TolokaAI team for inviting me and hosting the event.
discover.amzai.events/toloka…


Last week, we hosted our first Toloka Talks in San Francisco.
We brought together AI leaders from enterprise teams and frontier labs for a candid discussion on what it actually takes to adopt open models, build evals you can trust, and prove performance holds up in production.
Huge thanks to our panelists – Sharad Aggarwal (Google Cloud), Benny Yufei Chen (Fireworks AI), Sunzay Passari (UPS), Mikhail Parakhin (Shopify), and our CEO @MegorskayaOlga – for keeping it real and sharing both the real-world friction and lessons learned along the way.
📍 Next stop: New York City (Oct 28)


Looking for UMI data? We have off-the-shelf datasets ready to deploy, plus custom collection capabilities.
UMI bridges the gap between raw egocentric video and full robot teleop—capturing the key signals needed for VLA training:
• Wrist and head camera views
• 3D hand pose trajectories
• Gripper positions
Wrist cameras capture the moment of contact third-person views miss, all without needing a physical robot in the loop.
Check out the data in action and request samples: toloka.ai/physical-ai
Toloka retweeted

Founders move faster when the right expertise is available exactly when the work demands it.
That is the idea behind the new partnership between @bat_tower and @tendem_ai: giving BAT founders a practical way to expand what their teams can take on, without waiting for the next hire.
As BAT puts it: “Founders need specialist skills long before they can hire for every function.”
By combining AI, vetted experts and quality checks, we can help meet that need.

Now AI engineers can use Toloka to manage the full development flywheel—from evaluation to RL data to post-training, all grounded in high-quality human data.
Start with off-the-shelf datasets, run tasks yourself via self-service, or let our team build custom workflows for you.
Explore Toloka for AI engineers: toloka.ai/ai-engineers

Amazon #MechanicalTurk closes Sept 30th. If you run model evaluation, data collection, or QA, you're on a tight deadline to secure your pipelines.
The good news? You don't have to pause your data operations. It's easy to migrate your tasks directly to the Toloka Platform, and upgrade your human-data operation to a system built for modern AI workloads.
Here’s what to expect:
💰 Budgets under control: No minimum spend, pay-per-task pricing, and automated cost estimates before launch.
⚡ Upgraded data quality: Built-in QA (golden sets, overlap, automated LLM checks) across 200k+ vetted contributors & domain experts.
🛠️ Quick setup: Bring your existing HIT instructions, criteria, and inputs—our AI assistant helps draft your setup in minutes.
Migrate your MTurk workflows to Toloka: toloka.ai/mturk-migration

Excited to join the @nebiusai AI Builder Program! We're joining forces to support developers building and scaling AI systems on an open, independent stack.
With @TolokaAI & @Tendem_AI, builders can:
• Evaluate & score agent outputs (LLM-as-a-Judge + human experts)
• Fine-tune open models on high-quality expert data
• Route tricky edge cases to human experts via Tendem MCP
Claim your $100 in Toloka & Tendem credits (plus $400+ across the ecosystem) and start building: dev.nebius.com/builders


The Nebius AI Builder Program is now available.
AI isn’t just a model you call anymore. It’s a system you build. And builders, not a few closed labs, will decide what it becomes.
The open ecosystem has all the pieces. We want to make it easier to put them together and start building.
The program is free, with $400+ in credits and discounts, working code and cookbooks, office hours with engineers, and a community to build with.
We’re joined by @NVIDIAAI, @LangChain, @huggingface, @cognition, @OpenHandsDev, @tavilyai, @TolokaAI, @composio, @PrimeIntellect, @MiniMax_AI, @Alibaba_Qwen, and more joining soon.
Join with the link in the comments 👇
Proof that specialized ground truth + high-precision data beats generic scale every time. Huge congrats to the @Shopify team -- proud to be part of the flywheel engine!

