

Oakland, CA
Joined March 2009
- Tweets441
- Following1.1K
- Followers5.3K
- Likes4K





Tom Channick retweeted

DualChem, a new benchmark from @scale_AI, tested 29 frontier models on dual-use chemistry questions: ones that could serve either legitimate scientific research or harmful ends.
They frequently flagged the risk, then answered anyway.
Recognition is not refusal.
DualChem is part of our research collaboration with @NIST’s Center for Advancing Innovation and Standards for Super Intelligence (CAISSI).
Governments need independent testing capacity they don’t have today.
@madialder covered the findings at FedScoop:
fedscoop.com/scale-chemistry…

Tom Channick retweeted
NEWS: Scale is open for business in the UAE! Today at the Dubai AI Festival, we launched Scale AI in the UAE. Between this launch and our partnership with @PresightAI, we’re moving quickly to support the UAE’s national investment in AI.
Our role in this part of the world is to help these institutions put their strategy into practice by standing up AI that works reliably in Arabic, meets local governance requirements, and keeps people in control.
Our UAE team is based at the Dubai International Finance Center - thank you to the @DIFC for the warm welcome. We’re excited to be part of UAE’s dynamic AI industry.
lnkd.in/ghsYXmF3

Tom Channick retweeted

We're still cookin 🧑🍳

THE SCALE MAFIA
one of the most special parts of starting a company is watching the people you fought and bled with in the early days go out and change the world.
the Scale crew was supernatural. @scale_ai was one of the first companies to IOI and IMO-maxx, and the magic of Scale was that all of these geniuses gave a shit and ran through walls. it's no wonder that the Scale mafia is the first true mafia of the modern tech era. just to name a few:
- cognition founder @stevenkplus1 & president @russelljkaplan
- modal founder @akshat_b
- tech & science advisor to POTUS @mkratsios47
- claude code head of product @_catwu
- kpcb partners @LM_Braswell & @nayakkayak
- bun founder @jarredsumner
- tbd head of product @lindugong
- netic founder @melisatokmak
- cobot founder @BradPorter_
- secureframe founder @shravvmehtaa
- paramount skydance cfo @DennisKCinelli
- thinking machines gc lauren lennon
- partner at greylock @sophia_luo_
- liquid ai coo jeffrey li
- gallatin ai founder @agilemofo
- tbd safety @_julianmichael_
- center for ai safety president @devindkim
[photo courtesy the beautiful wedding of @thenateherman (who in many ways was a cofounder of Scale) and @ChristinaG325]

Tom Channick retweeted
The @scale_AI Mafia is an unreal force 🤯. Wild to see what this crew is doing—and the talent and ambition of the next generation. It’s clear this story is just getting started.
THE SCALE MAFIA
one of the most special parts of starting a company is watching the people you fought and bled with in the early days go out and change the world.
the Scale crew was supernatural. @scale_ai was one of the first companies to IOI and IMO-maxx, and the magic of Scale was that all of these geniuses gave a shit and ran through walls. it's no wonder that the Scale mafia is the first true mafia of the modern tech era. just to name a few:
- cognition founder @stevenkplus1 & president @russelljkaplan
- modal founder @akshat_b
- tech & science advisor to POTUS @mkratsios47
- claude code head of product @_catwu
- kpcb partners @LM_Braswell & @nayakkayak
- bun founder @jarredsumner
- tbd head of product @lindugong
- netic founder @melisatokmak
- cobot founder @BradPorter_
- secureframe founder @shravvmehtaa
- paramount skydance cfo @DennisKCinelli
- thinking machines gc lauren lennon
- partner at greylock @sophia_luo_
- liquid ai coo jeffrey li
- gallatin ai founder @agilemofo
- tbd safety @_julianmichael_
- center for ai safety president @devindkim
[photo courtesy the beautiful wedding of @thenateherman (who in many ways was a cofounder of Scale) and @ChristinaG325]
Tom Channick retweeted
THE SCALE MAFIA
one of the most special parts of starting a company is watching the people you fought and bled with in the early days go out and change the world.
the Scale crew was supernatural. @scale_ai was one of the first companies to IOI and IMO-maxx, and the magic of Scale was that all of these geniuses gave a shit and ran through walls. it's no wonder that the Scale mafia is the first true mafia of the modern tech era. just to name a few:
- cognition founder @stevenkplus1 & president @russelljkaplan
- modal founder @akshat_b
- tech & science advisor to POTUS @mkratsios47
- claude code head of product @_catwu
- kpcb partners @LM_Braswell & @nayakkayak
- bun founder @jarredsumner
- tbd head of product @lindugong
- netic founder @melisatokmak
- cobot founder @BradPorter_
- secureframe founder @shravvmehtaa
- paramount skydance cfo @DennisKCinelli
- thinking machines gc lauren lennon
- partner at greylock @sophia_luo_
- liquid ai coo jeffrey li
- gallatin ai founder @agilemofo
- tbd safety @_julianmichael_
- center for ai safety president @devindkim
[photo courtesy the beautiful wedding of @thenateherman (who in many ways was a cofounder of Scale) and @ChristinaG325]
Tom Channick retweeted
At #NVIDIAGTC Berlin, @JensenHuang highlighted our work with @Skydance to post-train @NVIDIAAI Nemotron 3.5 Super VL.
On real production tickets, the agent matched frontier-model accuracy at ~1/40 the inference cost and 5x the speed.
Tom Channick retweeted

Congratulations to @AIatMeta on releasing Muse Spark Open. An incredible achievement and an exciting step toward a future with more choice in AI.
The @Muse family has been especially strong on multi-step coding workflows, and open weights make it much easier to tune those capabilities for custom use cases.
We’re proud to work with the @Meta team!


Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio


Tom Channick retweeted
The future of enterprise AI is multi-model, and enterprises deserve the freedom to choose.
NEWS: We’re expanding that choice through our collaboration with @NVIDIA, post-training its open-weight Nemotron 3.5 Super VL for enterprise workflows. Here’s what it delivered for two of our customers:
✅ @Skydance: A complex finance workflow that reviews vendor credit memos, statements and invoices to find credits the company is owed. Post-trained Nemotron matched their current frontier model’s accuracy at 40x lower inference cost, with 5x faster response times.
✅ @EY_US: An M&A due diligence agent that finds and reconciles answers across hundreds of files in a virtual data room. Post-trained Nemotron matched EY’s current frontier model at about one-eighteenth of the inference cost, returning answers more than twice as fast.
Put NVIDIA’s open-weight models to work for your business with Scale Post-Training.
Thank you, @JensenHuang and the NVIDIA team, for the early access and collaboration.
scale.com/partnership/nvidia

Tom Channick retweeted
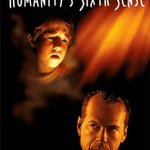
Congrats to @GoogleAI's Gemini 4 Argon for taking the top spot of our Humanity's Sixth Sense (HSS) benchmark with a score of 55.4%, edging out GPT-6-Astra at 53.6%. 🥇
HSS tests AI’s ability to reason beyond what’s visible, from hidden objects to predicting what happens next and understanding human behavior.
We took a closer look at performance across categories, and that’s where things get interesting. 👀🧵
Tom Channick retweeted

We collaborated with @scaleAI to build a high-fidelity port simulation RL environment where AI agents tackle real-world logistics challenges
Tom Channick retweeted
Recognizing a mental health crisis isn’t the same as helping someone through it.
Today @ScaleAILabs is releasing DistressBench, a benchmark built with clinician input that evaluates how models respond in these high-stakes moments.
In over 1/3 of the conversations where models recognized a crisis, they still failed to provide help or resources. For someone who may only have this conversation once, that’s not good enough.
AI should lift up humanity, including those most in need, which is why we need consistent red teaming and AI evaluations that analyze how people actually use this technology in their day to day lives.
We hope this benchmark is a useful starting point to understand AI’s current limits in crisis response and help the companies building models create better ones.
labs.scale.com/blog/distress…

Tom Channick retweeted

I watched top AI models insist a bookshelf with plenty of space had no room for another book.
They can write professional code but miss what most people see in a second.
Proud to launch Humanity’s Sixth Sense (HSS) with @fdesouza and @ScaleAILabs, a new challenging multimodal benchmark testing that blind spot.
See our blog: elorian.ai/blog/humanitys-si…

We’re introducing Humanity’s Sixth Sense, a new benchmark testing the intuitive visual reasoning people rely on every day.
Across 522 open-ended tasks spanning images and video, HSS tests everything from spatial and causal reasoning to social understanding.
The gap is significant. Humans score 93.1%, while the strongest model, GPT-6-astra, reaches 53.6%. The median model scores just 30.9%.

Tom Channick retweeted
AI is usually measured on problems that are hard for people. Humanity’s Sixth Sense, our newest benchmark with @ElorianAI, tests the everyday visual judgements we make without thinking.
Humans scored 93.1%. The strongest AI model scored 53.6%.
labs.scale.com/blog/introduc…

Tom Channick retweeted
Much of the AI security debate is about frontier models. But a lot of people are building on open-weight models. We need to understand their capabilities and risks too. A real testing strategy covers every model, not just the frontier.
Tom Channick retweeted
You can’t improve agents if you can’t measure where and why they fail.
At #LATechWeek, we're hosting a hands-on evals workshop led by our Head of General Agents @Bckenstler to break down how we structure evals, what we measure, and how we use the results to improve AI systems.
Apply here to join us: scl.ai/LATechWeek
Tom Channick retweeted
The nation that can measure the AI frontier will be the one that steers it. Our future should not be steered by speculative warnings. We have to be driven by evidence. That was the clearest takeaway from this week's AI conversations at the UN General Assembly.
Governments need to get serious about testing frontier AI, and nowhere is that more urgent than in Washington.
Getting serious means three things:
→ Clear responsibility for testing across agencies
→ Access to models before they're deployed
→ Funding for the experts and tools to do the work
Scale AI's cyber research shows what testing can reveal. We've seen AI agents carry out an attacker's instructions while still finishing the user's task, so the user never knew anything went wrong. We've also seen models refuse to help people defend their own systems.
Both are failures. Real testing has to measure the harm AI can cause and the help it fails to give.
Government shouldn't have to rely solely on AI developers to explain these failures. It needs its own testing capacity, with the expertise to ask hard questions and the tools to answer them.
Scale has worked with the U.S. government for years to test the risks and capabilities of AI models, and we're accelerating that work in the months ahead.
Here's what we think America should do next: scale.com/blog/steer-the-ai-…

Tom Channick retweeted
We're releasing HLE-Diamond: a refined version of Humanity's Last Exam, built with @CAIS.
A year of review and community feedback went into refining this subset to make it more reliable for measuring frontier models.
Top model tested 60.6% overall. We expect HLE-Diamond to carry signal for the next 6-12 months.

Tom Channick retweeted
we’ve really appreciated the partnership with @scale_AI in building muse 🤝

Leaderboard spotlight!
With @Muse on top of the app store, a special shoutout to @AIatMeta for Muse Spark 1.3. The @ScaleAILabs team worked closely with them on evaluations, training data, and testing.
Muse does well on tool use, multi-turn conversation, tutoring, professional reasoning, and end-to-end software engineering. Different tasks, but each asks a model to hold context across long horizon workflows, make judgments under uncertainty, and recover from partial failures.
PRBench is where that's clearest. Its tasks are written by domain experts and scored on rubrics that reward professional utility, not trivia-style correctness. Muse has held the top spot in finance and law since 1.1, and 1.3 extends the lead.

Tom Channick retweeted
This week I joined @RoyalFamily, govt ministers and leaders to discuss how AI can best serve the public good.
AI can expand opportunity and solve some of our toughest challenges. It’s essential that we pursue that potential responsibly, in a way that benefits people broadly.
Rigorous, independent testing - like we do at @Scale_AI - is an essential step to earning public trust.
Governments and independent evaluators need to work together to deeply and continually assess AI's capabilities, opportunities, and risks. That allows us to make sound decisions about its development and use.
Conversations like this one are a step in the right direction.

“I really am enormously grateful for the presence in this room of many of our greatest technological minds, and indeed, for the thoughtful stewardship demonstrated by those gathered here today as you consider the fundamental principles that should – and must – guide the development of Artificial Intelligence in the years ahead.”
Today at Dumfries House, The King convened AI pioneers, Government representatives and thought leaders to discuss how AI can be developed and deployed in ways that benefit society.


