

working on @positionappxyz (ios)
- Tweets6.6K
- Following1.9K
- Followers1.5K
- Likes9.8K

ALT Typographic card titled open weights, not apache. Left panel: Tencent Hy License 1.0 Section 10, MaaS operators need a separate written license if worldwide gross revenue exceeds $50 million in 12 months or a product exceeds 100 million monthly active users; internal-only use is exempt. Right panel: official tweet 224B total 12B active versus Hugging Face card 220B total 11.3B text-active, plus download links for Hy4-flash, Hy4-flash-FP8, Hy4-flash-base, GitHub, and AngelSlim GGUF. Notes an r/LocalLLaMA AMA and a TP=8 official vLLM recipe.


ALT Four-row chart of official list price versus Artificial Analysis Intelligence Index cost and time per task for GPT-6.2 Sol max, Gemini 4 Neon xhigh, Claude Sonnet 5.5 max, and Claude Opus 5.5 max. Headline: neon is cheaper than opus on AA, not cheaper than sol. Sol is $1.01 and 7.9 minutes, Neon $6.44 and 21.5 minutes, Sonnet $10.02 and 32.6 minutes, Opus $10.04 and 24.5 minutes. Footnotes: Neon is #3 overall behind Astra and Fable 5.2, page header also showed #6 of 96; Sonnet and Opus AA bills are a tie; Google 50-80% line is a vendor claim; author n=1 tests are not on this chart.

ALT Eligibility card for Tasks in Gemini: free of charge from Nov 17 in the US, Japan, South Korea, Canada, Australia, and India for 18+ personal accounts with History on. Calling, Pay, email, and SMS start in the US. EEA, UK, Switzerland, and Nigeria are out.


ALT Table comparing official list prices per 1M tokens with Artificial Analysis cost, time, and Intelligence Index for GPT-6.2 Sol, GPT-6.2 Astra, and Claude Opus 5.5. Headline: list price is not cost per task.

ALT Terminal output of a Hyperliquid API call (metaAndAssetCtxs, dex xyz) for the xyz:ANT perp, pulled Nov 19 8:19 AM IST: markPx 100.23, oraclePx 99.429, prevDayPx 96.513, open interest 1,738,664 contracts, 24h volume $98.8m. Derived: +20.8% vs the $83 IPO price, $174m open interest, $99m 24h volume.
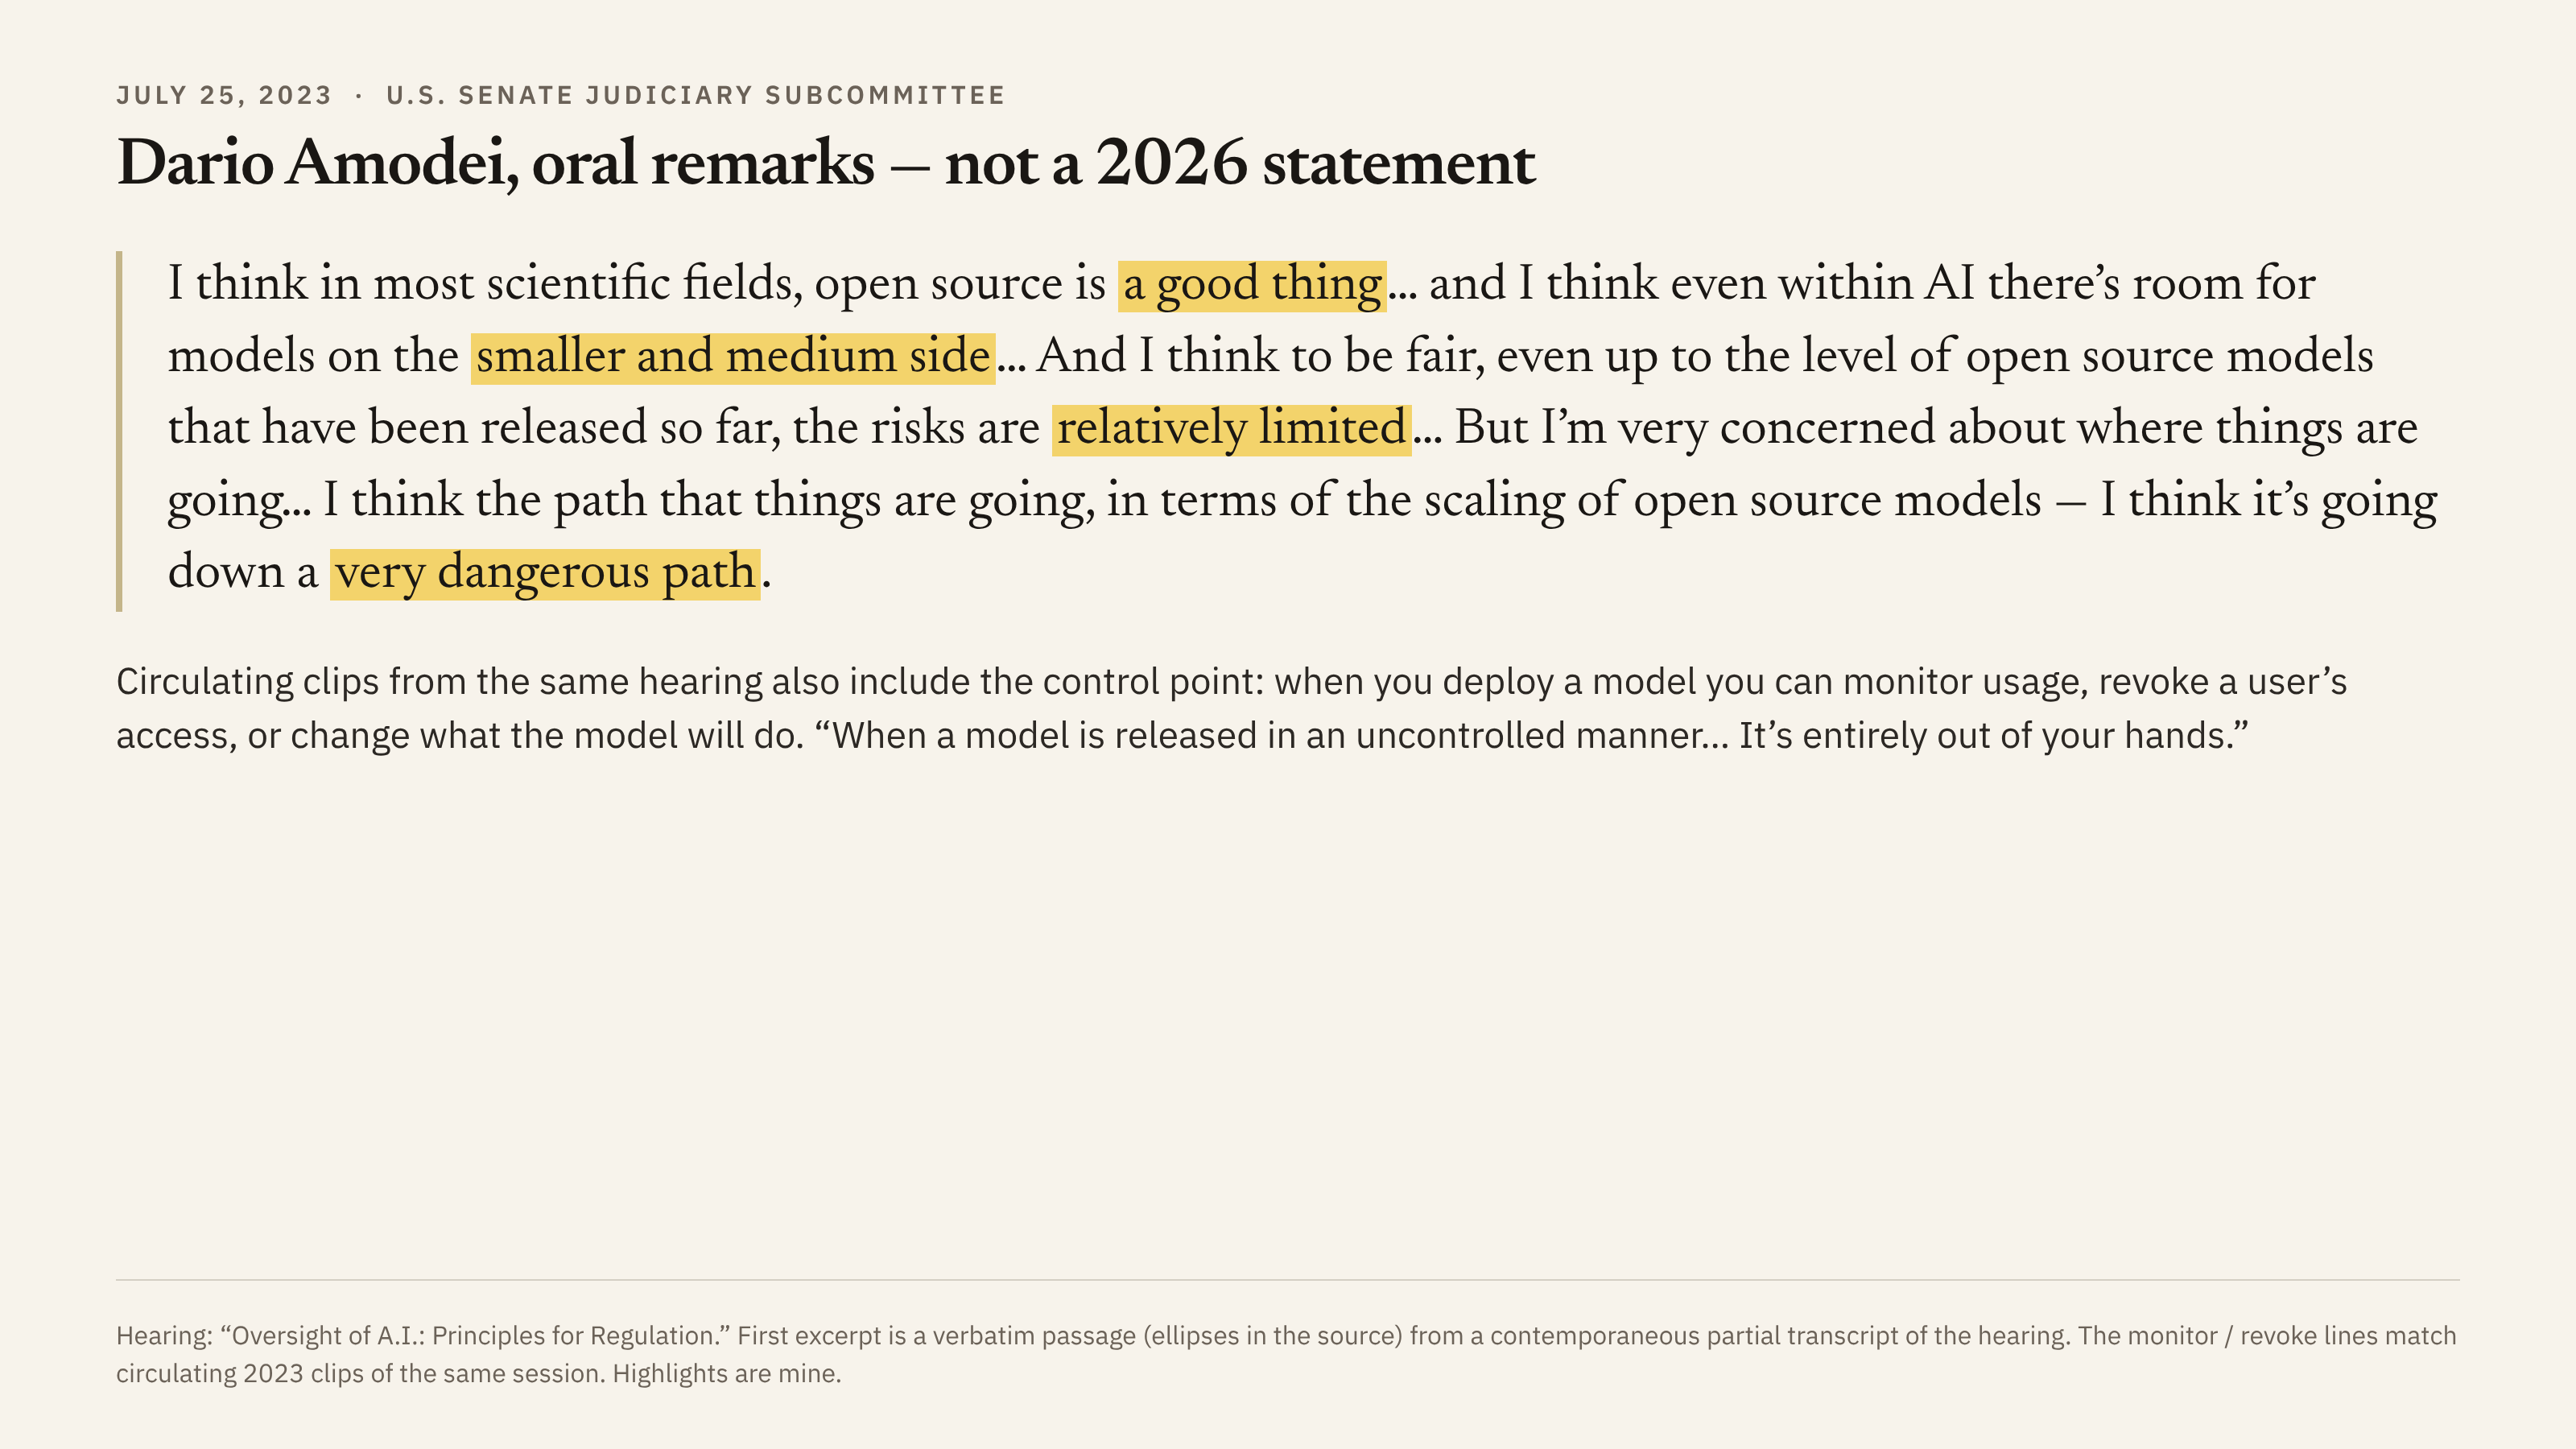
ALT Highlighted excerpts from Dario Amodei's oral remarks at the July 25, 2023 Senate Judiciary Subcommittee hearing Oversight of A.I.: Principles for Regulation. He said open source is a good thing in most scientific fields, there is room for smaller and medium models, and then-current open models had relatively limited risks, while warning that the scaling path was going down a very dangerous path.


ALT Annotated official Tencent Hy4 flash blind-test chart. The 18x cheaper figure is versus Claude Haiku 5.5 (¥4.73 vs ¥0.26 per task). On the same chart DeepSeek V4.1 Flash scores higher satisfaction (3.09 vs 2.79), costs about 4.6x more, and is slower (10.3 vs 6.7 min). 85 users, 259 tasks, external models at high tier.


ALT Ranked bar chart: Hyperliquid perps' change since Tuesday's 4 PM ET close, peak after Nvidia's earnings vs now. Nvidia perp peaked +5.2%, now +0.7% ($155.66 close, $163.76 peak, $156.82 now). SOXL +14.2% peak, +2.4% now; Nebius +12.5/+5.1; SK Hynix +6.2/+1.3; Bitcoin +2.0/+0.4. Pulled 8:16 AM IST Nov 18.

ALT Two highlighted official-page excerpts. Top: Anthropic's Nov 24, 2025 post on advanced tool use, quoting average usage dropped from 43,588 to 27,297 tokens, a 37% reduction on complex research tasks, noted as an API feature rather than Code Mode. Bottom: Claude Code's Code Mode docs, which describe the experimental, off-by-default feature and contain no token-savings figure. Quotes verified 9:22 AM IST, Nov 16, 2026.


ALT Comparison table from Artificial Analysis, Nov 16, 2026: Qwen4-Max at xhigh versus Kimi K3.1 Pro at max. Intelligence Index 43 vs 46, cost per task $3.27 vs $3.68 (about 11% lower), Terminal-Bench 4.0 48% vs 67%, with the Terminal-Bench row highlighted as the gap. Official Qwen4-Max list price $1.50/$4.50 per 1M tokens. Figures verified 9:22 AM IST.


ALT Heatmap of hourly % change over the last 24h for Hyperliquid perps. AI stock perps on trade.xyz fell: INTC -6.5%, SNDK -4.6%, ANT -4.4%, MU -4.2%, GOOGL -3.6%, NVDA -3.5%, SK hynix -1.9%, XYZ100 -2.1%. Crypto held: BTC -1.0%, ETH -0.4%, HYPE +3.2%. Source: Hyperliquid info API, pulled 8:19 AM IST Nov 17.
