
Local LLM V100 96G & enjoy Omarchy; Tday https://xitter.cf/t.co/P6K9F7LvIO ; CODELF (Github star 14k); MIHTool (Mentioned in Google I/O'13)
Los Angeles, CA
Joined January 2008
- Tweets4.6K
- Following392
- Followers2.5K
- Likes1.2K





Pinned Tweet
We just hit 300 members today—woke up to 100+ new people joining overnight. Come join these top DIY hackers using extreme optimization to make old hardware run Qwen3.8-Flash and GLM5.3-Flash. 🚀xitter.cf/i/chat/group_join/g209…


Just a bit of insight: people are eager to build their own rigs for local LLMs, the same way we were obsessed with building gaming PCs 30 years ago. xitter.cf/i/chat/group_join/g209…


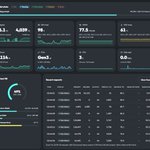
You guys keep asking about the power cost of my 4×V100. I asked Strata + Qwen3.8-Flash to build me a dashboard—here’s the daily, weekly, and monthly bill. Don’t be surprised 😎


DeepSeek V4.1 Flash “cheated” by checking Qwen’s previous work from memory, then ate up the 70 minutes I’d planned to sleep—plus $3. But I forgive you. The quality won me over. Take my knees—SOTA King! 🙇

