
Incoming Assistant Professor @HKUSTGuangzhou, PhD @sgSMU
Joined November 2016
- Tweets136
- Following319
- Followers180
- Likes432


Zhensu Sun retweeted

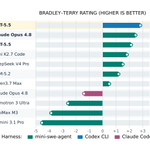
ok it's official... AI-written unit tests and integration tests are empirically proven to be unhelpful. you should tell your agents to stop writing tests by themselves
on the deepswe eval set, banning sonnet 5.5 high from writing any tests actually resulted in slightly higher success rate (non stat-sig), with less time and token spent (stat-sig). this is pretty hard empirical evidence
across the tests that were written by the "tests allowed" baseline arm, 65% of them were unit tests, 35% were integration tests, neither bucket resulted in any improvement compared to not writing any tests at all
i also picked a random sample of 44 tasks subset where i completely disabled executing even existing tests - it also did not affect success rate at all
i spot checked many tests written in the baseline arm, and my intuition is that most tests are simply a repetition of the implementation
agent-written tests do not add any value because both the implementation and the tests were simply the agent's interpretation of our intent. the tests aren't any more accurate than the implementation itself
i suspect we can still extract some value from unit tests and integration tests if we describe them ourselves when we believe we can articulate our intent better through test cases than through requirements. but i have not proven this yet
also worth noting, during deepswe eval the agent wrote almost no e2e tests (only 17, compared to 3000+ unit/integration tests written). so this analysis does not prove nor disprove the value of e2e tests - i will do another eval specifically for that


Zhensu Sun retweeted

Stripping code formatting cuts LLM token cost without hurting accuracy.
Average input tokens drop by 24.5%, with output quality basically unchanged.
The core issue is simple, indentation, spaces, and newlines help humans read but they inflate tokens that models pay to process.
They remove only cosmetic formatting while keeping program meaning identical, checked by matching the abstract syntax tree of the code.
They test Fill in the Middle code completion, where a model fills a missing block, across Java, C++, C#, and Python.
Performance stays stable on unformatted input, big models barely move, smaller ones wobble a bit, Python sees less savings because its layout is part of the language.
One surprise, models still print nicely formatted code even when given smashed input, so output token savings are small.
To fix that, 2 cheap tactics work, explicit prompts that say output without formatting, and light fine tuning on unformatted samples.
With clear instructions or tiny training, output length shrinks by 25% to 36% while pass rate on the first try holds.
They also ship a tool that strips formatting before inference then restores it after, so humans read clean code while the model pays less.
----
Paper – arxiv. org/abs/2508.13666
Paper Title: "The Hidden Cost of Readability: How Code Formatting Silently Consumes Your LLM Budget"

Zhensu Sun retweeted

🚨 Big Announcement! 🚨 We’re thrilled to welcome two distinguished keynote speakers to #FORGE2025!
✨ Prem Devanbu @devanbu (@UCDavis Professor)
🔗 cs.ucdavis.edu/~devanbu/
✨ Graham Neubig @gneubig (@CarnegieMellon Associate Professor )
🔗 phontron.com/

Zhensu Sun retweeted
🎉 Exciting News! 🎉
We are thrilled to announce that ACM SIGSOFT has officially upgraded FORGE from an ICSE Special Event to an ICSE Co-Located Conference! 🚀 We can’t wait to see your submissions for FORGE 2025!
See more below👇
#FORGE #FORGE2025 @ICSEconf
Zhensu Sun retweeted

AI is not making any progress"? Look closer. 🙄 GPT-4 level models got 240x cheaper in just 2 years! AI progress isn't linear and is just about bigger models.
BERT -> DistilBERT
Llama 2 70B -> Llama 3 8B
GPT-4 -> GPT-4o-mini
Llama 3 405B → Llama 4 70B?? 🤔
Models get bigger, then smaller but equally powerful. It's a cycle of innovation. Today's quality per $ is the most expensive we'll see.
Making it cheaper will lead to more people using, learning, and building with AI, which might unlock more potential and “goodput” for everyone than yet another Foundation Model!
AI's real progress: Getting into more hands.🤗
[Image credits: @davidtsong]

Zhensu Sun retweeted

Wow.
@Jandodev just showed me a prompt humans can’t read but LLMs understand this language better.
The San Francisco AI people are designing a new language.
In stealth. You are first to see it.

Zhensu Sun retweeted

Today we are releasing two small models: Mathstral 7B and Codestral Mamba 7B.
On the MATH benchmark, Mathstral 7B obtains 56.6% pass@1, outperforming Minerva 540B by more than 20%. Mathstral scores 68.4% on MATH with majority voting@64, and 74.6% using a reward model.
Codestral Mamba is one of the first open source models with a Mamba 2 architecture. It is the best 7B code model available, and is trained with a context length of 256k tokens.
Both models are released under the Apache 2 license.
mistral.ai/news/mathstral/
mistral.ai/news/codestral-ma…


Zhensu Sun retweeted

Want to turn your own GitHub Repos into a playground for 🤖 coding agents?
📢📢 Introducing R2E: Repository to Environment
📈 Scalable, dynamic, real-world repo-level benchmarks
💡 Generate Equivalence Tests Harnesses
🔗 r2e.dev | Accepted @ ICML '24
🧵

ALT R2E: Turning any GitHub Repository into a Programming Agent Environment
Zhensu Sun retweeted

#impact: @lminozem's MIP talk at @ICSEconf in Lisbon has inspired @davidlo2015 and Corina Pasareanu to include a slide about constructive reviews in the slide deck for the PC members of #ICSE2025.


Zhensu Sun retweeted

We have just released 🍷 FineWeb: 15 trillion tokens of high quality web data.
We filtered and deduplicated all CommonCrawl between 2013 and 2024.
Models trained on FineWeb outperform RefinedWeb, C4, DolmaV1.6, The Pile and SlimPajama!

Zhensu Sun retweeted

🏆 Extremely happy to share that I received the Google Research Scholar award (research.google/programs-and…) this year with my proposal "Towards Faster and Greener LLM-assisted Programming"!
I expect to share more results in this direction soon! 😊
Zhensu Sun retweeted

What a bigggg achievement! What’s the next award @lilicoding 😎? – at Lisbon, Portugal



