

Public LLM Evaluation // https://xitter.cf/t.co/rNS39rhVQ9 @8vc @BloombergBeta @pearvc @a16z @HRTVentures @nextladder
San Francisco, CA
Joined March 2024
- Tweets2.4K
- Following280
- Followers28.9K
- Likes832






Pinned Tweet
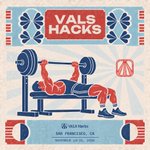
For one weekend, we are benchmaxxing on purpose!
Join us for the first Vals AI Hackathon on November 14–15 in San Francisco. We're giving 150 hackers 24 hours and a lot of compute to improve small models, challenge the frontier, and see what they can build.
Track 1: Post Train a small model and see how high it ranks on three Vals benchmarks. Live leaderboard, compute from our sponsors.
Track 2: Build a Your Own Eval on Valkyrie for tasks that still stump frontier models. We cover model and compute costs.
Come meet the Vals team. Expect great prizes, notable guest speakers and fun side quests, including an optional cybersecurity CTF.

Rayan was recently on the @AmOptimistShow with @JTLonsdale and @vvkgopalan and gave insight to model performance, RSI, and more!

I wouldn't have founded @ValsAI without first working at Palantir and Vals wouldn't be what it is without 8VC investing in our seed. @JTLonsdale was key to both.
Got to sit down with Joe and @vvkgopalan to talk about the story behind Vals, where the industry is going, and why I'm broadly optimistic while the world is incredibly high-variance.

There is a significant improvement over K3 on Terminal-Bench-Science: K3 scored 1.4% vs 31.4% on K3.1 Pro. Cost per test fell from $21.30 to $8.58, and time per test from about 4.8 hours to 58 minutes.

At $3.33 per test, K3.1 Pro costs less than half of GPT-6 Astra ($8.03), Sonnet 5.5 ($8.92) and Opus 5.5 ($9.13), though those models score 14 to 21 points higher.
Full results: vals.ai/models/kimi_kimi-k3.…

Vals AI retweeted

More evaluation of cyber capabilities and risks is needed. If you are interested in this type of work, we are hiring! Join us: jobs.ashbyhq.com/vals-ai/01f…


i saw a lot of people being negative about the K3.1 pro release
one point that was under discussed imo is that it's the first open lab that is pacing the frontier of open weight cyber capabilities, which makes it much easier (and create incentive) for other labs to make the right decision and do the same when they reach the same level of capabilities
the remaining question is how to set the right level? underestimate it and open models become useless for defensive cybersecurity, leaving the world relying on US closed labs to spread defensive capabilities quickly, which is not realistic imo (i obviously wish them to succeed in this mission tho). overestimate it and you might get the catastrophic scenarios that anthropic and others describe
this threshold can't rely on a few benchmarks or people alone, we need much more open cyber evaluation, more diverse third party evaluators, labs testing each other's models (including oss labs!) for this kind of capability


Does it matter where you run an open-weight model?
Today we are releasing the Inference Provider Index. It compares first and third-party open-weight models for quality on agentic tasks in finance, coding, and legal industries.
Unlike other inference benchmarks, we rerun it every two weeks to catch quality degradation, and we use agentic tasks, not single-turn multiple-choice questions. It covers over 650 hours of model runtime.

Accuracy looked most alike across providers, but only in aggregate. Overall accuracy can hide domain-specific performance, so choose the provider that works best on your domain.
Kimi K3 scored 60.6% on Legal through Baseten against 75.8% on Moonshot’s API. On Coding, a different provider beat the model maker’s own API.
This matters more as open-weight models carry most of the traffic. They’ve made up more than half of all tokens on OpenRouter since April, and over 62% since July. Providers also change their serving stacks behind the same model name, and model makers have noticed. Moonshot publishes a verifier for third-party Kimi endpoints, and MiniMax published fixes after finding implementations that hurt its model in agent workflows.
For the full methodology, visit vals.ai/benchmarks/inference…
