
Multimodal AI Research Engineer | @huggingface Fellow & Builder 🤗 | @openai Codex Ambassador
Seoul
Joined January 2022
- Tweets85
- Following180
- Followers63
- Likes244
this is on a whole other level 🚀

Previewing Ultrafast mode for @OpenAI's GPT 5.6 Sol, powered by Cerebras.
GPT-5.6 Sol Ultrafast generates responses at up to 750 tokens per second. That's the full, GPT-5.6-Sol model -- up to 14× faster than the same model on Standard processing.
It speedran Humanity’s Last Exam in 11h 11m, nearly 7× faster than Claude Fable 5 with comparable accuracy.
woojun retweeted

In the 19th century, railroad companies spaced their tracks differently, so whenever two lines met up, passengers and freight had to get off and on. Labs build and ship their models similarly today, and that's what happens when people are moving fast and doing good work. The trouble is, checkpoint formats can vary in how they're named, the shape of their weights, and more. Somebody had to write a conversion script to make it work, and then again for the next model that named its weights something else.
Transformers stopped doing it this way. The dynamic weight converter lets a model say what it looks like once at load time, and the whole ecosystem reads it from that same definition. No more fussing around with trying to get a model to work with separate tools and labs can go on shipping models in their native format.
How Transformers is quietly standardizing the model ecosystem: stevhliu.com/2026/how-transf…

woojun retweeted

Not every agent task needs a frontier model.
@Thom_Wolf (Co-founder of Hugging Face) on routing work to smaller open models for repeatable sub-tasks, evaluation, and cost control, matching compute to the value of the work.
Join us in the Token Billionaires Lounge by @cerebras and @aiDotEngineer.
woojun retweeted

Thinking Machines' Inkling is out: first ever open and large (1T), text, image and audio in, text out.
One thing I find quite striking is how much easier accelerating models has become.
We replaced the model's causal Conv1D with the `causal-conv1d` kernel. One line changed, +4% tokens per second.
We then replaced its attention implementation with FlashAttention-4. Another single change, another +11%.
That's a total throughput improvement of about 15%, without changing the model architecture or retraining anything.
And we haven't touched the MoE layers yet, which should offer some of the largest opportunities for optimization.
This is what makes the `kernels` effort so exciting to me: enabling model developers to find and integrate the best optimized kernels almost as easily as they would change a model configuration.
Kernel developers can focus on building the fastest implementations. Model developers can test and adopt them quickly. Everyone using the model benefits.
Two light updates for 15% on a 1T model is a pretty good start.

woojun retweeted

OpenAI Build Week Community Event – Seoul, South Korea.(Workflow Show & Tell)
We’ll be sharing an article soon.
Huge thanks to all our volunteers, presenters, and attendees. ❤️
LFG! 🚀
@OpenAIDevs @OpenAI


Excited to keep building with the Codex community 🙌

OpenAI is nothing without its community and Codex Ambassadors.
Very glad I got to meet our Codex Ambassadors in Seoul last week ✌️
@w00jun_ , @swhan0329 , @realsigridjin , @bongbonggg97


woojun retweeted

OpenAI is nothing without its community and Codex Ambassadors.
Very glad I got to meet our Codex Ambassadors in Seoul last week ✌️
@w00jun_ , @swhan0329 , @realsigridjin , @bongbonggg97
woojun retweeted

Excited to announce OpenAI Build Week!
A week full of excitement, joy and dedication to pushing what's possible with GPT 5.6 and Codex
We're introducing a Global challenge starting July 13 and over 40+ events across the globe to bring this experience closer to you
Kudos to our Codex Ambassadors for putting together such tremendous experiences across the planet from SF to Tokyo in the coming week!!
Sign up now and excited to see what you build!



woojun retweeted
Transformers v5.4.0 is live with 13 new models!
Key highlights:
• VidEoMT: 160 FPS video segmentation
• Document AI suite: UVDoc, SLANeXt, PP-OCRv5
• PI0: Vision-language-action model for robotics
• Mistral 4: Unified instruct/reasoning model
• Jina Embeddings v3: Multi-task text embeddings
• CHMv2: Forest canopy height mapping
~10 new model architectures contributed by the PaddlePaddle team 🤯
Plus major performance improvements and Flash Attention 4 support!
woojun retweeted

perhaps time to switch from antigravity to codex for my course

Meet Codex for Students.
We're offering college students in the U.S. and Canada $100 in Codex credits.
Our goal is to support students to learn by building, breaking, and fixing things.
chatgpt.com/codex/students
woojun retweeted
PyTorch Conference Europe is happening next month, and many of us from the Hugging Face team will be there
We'll be talking about Kernels, Transformers, Audio models, processors, Diffusers, Transformers.js among others
We'll be sharing a few sneak peaks of what's coming next 🤫
woojun retweeted

We just brought our community work into one place, making it easier to find events and programs like Codex Ambassadors and Codex for OSS.
There are 15+ community-led events coming up around the world, with more to come!
Where would you like to see a Codex meetup next? 🌏

woojun retweeted
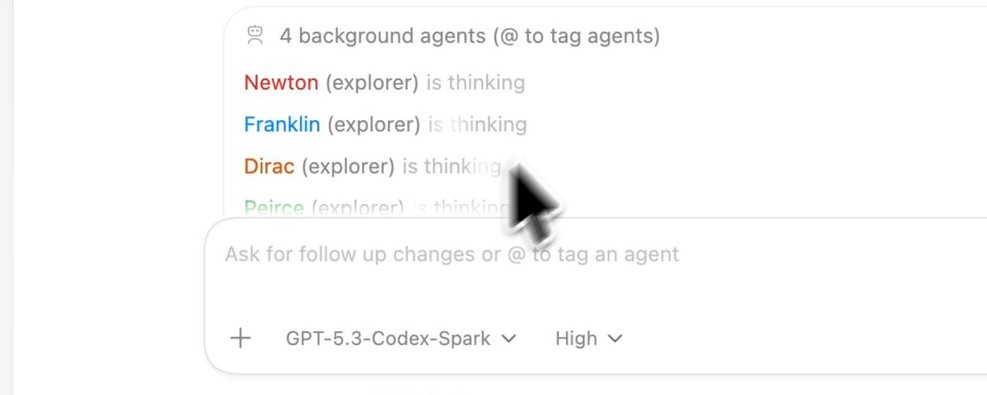
Subagents are GA in the Codex App and CLI, it's positively changed the way I work - go give it a shot now!!

woojun retweeted

Defuddle now returns Youtube transcripts!
Paste a YouTube link into defuddle.md to get a markdown transcript with timestamps, chapters, and pretty good diarization!
...or if you just want to read it, try the new Reader mode in Obsidian Web Clipper powered by Defuddle.
woojun retweeted
On March 11, at the OpenAI Codex Community Meetup – Seoul, I edited and uploaded the presentation video “Effective Harnesses for Long-Running Codex: The Era of AI Coding Through the Night” by speaker Goobong Jeong.
Since this is a video I edited myself, there may be some rough edges, but I hope it helps those who were curious about the talk.
If you're interested in the #Ralphthon recap or learning practical approaches for maintaining long-running Codex sessions with effective harnesses, I highly recommend checking out the video below.
▶ Video:
youtube.com/watch?v=tjEVBcPT…
English subtitles (CC) are available in the video.
@OpenAIDevs @OpenAI
woojun retweeted
On March 11, at the OpenAI Codex Community Meetup – Seoul, I edited and uploaded the presentation video “OMX — Hacking Codex (Demo + Dev Story)” by speaker Yeachan Heo. (@bellman_ych )
Since this is a video I edited myself, there may be some rough edges, but I hope it helps those who were curious about the talk.
If you're interested in how Codex was extended and customized through OmX, or if you're building your own agent harness, this talk is definitely worth checking out.
▶ Video:
youtube.com/watch?v=XwFoegzi…
English subtitles (CC) are available in the video.
@OpenAIDevs @OpenAI
woojun retweeted
> Seoul’s three Codex Ambassadors (@swhan0329, @w00jun_, Junho Kong) — for organizing two (!) community meetups, where builders traded notes on everything from agent loops to OSS Codex extensions to CI workflows, and for helping connect us deeply with the local community.


