

Researcher @OpenAI | Training GPT-5.x and 6.x thinking models | Ex. Tencent, MSR , AI2
San Francisco, CA
Joined December 2021
- Tweets385
- Following1K
- Followers5.2K
- Likes1.4K




Wenhao Yu retweeted

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math


One thing I’m most excited about working at OpenAI is making intelligence cheaper, so more people can use it 🚀
Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
We are releasing GPT-6 Astra, our smartest, most capable to date! It is a big step towards AI that can carry ambitious projects from idea to completion. So proud of what we’ve achieved and excited for everything we will build next! We are only just getting started!
15
102
12,977
It’s finally out — the wait was worth it!
GPT-5.6 is definitely the best model we’ve built. It can work for a really long time, stay on task, and complete complex work end-to-end.
So happy and proud to work with our amazing team on it!
Wenhao Yu retweeted

Here is our current plan for OpenAI:
openai.com/index/built-to-be…

Wenhao Yu retweeted

What should AI generate in order to improve itself?
Not just more questions, traces, or answers.
We believe it should learn to generate environments.
Excited to share my first work after joining Tencent Hunyuan LLM. We study how models can construct reusable, verifiable environments that provide stable training signals for self-improvement.
This is only a first feasibility step, but we see environment construction as a necessary path toward truly self-improving AI.
Paper: arxiv.org/abs/2605.14392

Wenhao Yu retweeted
You've been asking for this one...
Now in preview: Codex in the ChatGPT mobile app.
Start new work, review outputs, steer execution, and approve next steps, all from the ChatGPT mobile app. Codex will keep running on your laptop, Mac mini, or devbox.
Wenhao Yu retweeted
Introducing GPT-5.5
A new class of intelligence for real work and powering agents, built to understand complex goals, use tools, check its work, and carry more tasks through to completion. It marks a new way of getting computer work done.
Now available in ChatGPT and Codex.
📌Introducing Single–Multi Evolution Loop for self-improving LLMs
Self-distillation is strong. Multi-LLM teachers are 𝐒𝐭𝐫𝐨𝐧𝐠𝐞𝐫!
Iterate: collaborate → distill → repeat, then single + multi systems improve together.
Paper: arxiv.org/pdf/2602.05182

⚠️ Multi-LLM collaboration systems are costly?
💡 Distill the collaborative outputs back into a single model!
♻️ These post-distillation, improved LLMs can collaborate again, forming a multi-LLM collective evolution cycle.
Introducing: ✨the single-multi evolution loop✨
arxiv.org/abs/2602.05182
Joint work w/ @kpb_in_acad @tsvetshop @wyu_nd

🥳 Now accepted to @CVPR 2026!
Project page and code: motion-edit.github.io/

🤔🤔Tired of static, lifeless image edits?
Not anymore! 🤗
🚀🚀We introduce MotionEdit, a framework supporting image editing that understands action, motion, interaction beyond static changes! 🤩🤩
🔗Full paper: arxiv.org/abs/2512.10284
✨Project page: motion-edit.github.io
Wenhao Yu retweeted

Update: We have released our Benchmark at huggingface.co/datasets/elai… and Train dataset at huggingface.co/datasets/elai… !

🤔🤔Tired of static, lifeless image edits?
Not anymore! 🤗
🚀🚀We introduce MotionEdit, a framework supporting image editing that understands action, motion, interaction beyond static changes! 🤩🤩
🔗Full paper: arxiv.org/abs/2512.10284
✨Project page: motion-edit.github.io
Wenhao Yu retweeted

R-Zero is accepted by #ICLR26 !!!

𝑳𝑳𝑴𝒔 can really 𝑺𝒆𝒍𝒇-𝑬𝒗𝒐𝒍𝒗𝒆, 𝒘𝒊𝒕𝒉𝒐𝒖𝒕 𝑯𝒖𝒎𝒂𝒏 𝑫𝒂𝒕𝒂!
-- One LLM, two roles: Challenger creates tasks, Solver answers them.
-- No data, no labels, just a base model that learns and improves itself!
We name it 𝑹-𝒛𝒆𝒓𝒐: arxiv.org/abs/2508.05004

Wenhao Yu retweeted

For LLM RL, Entropy is not equal to exploration. Semantic diversity is also a lie.
Most RL exploration methods push LLMs to "look" different, but they ignore how the model actually learns.
We propose G²RL: Gradient-Guided Exploration for RL
arxiv.org/pdf/2512.15687
(1/n)

🚀Introducing 𝐆𝐫𝐚𝐝𝐢𝐞𝐧𝐭-𝐠𝐮𝐢𝐝𝐞𝐝 𝐎𝐩𝐭𝐢𝐦𝐢𝐳𝐚𝐭𝐢𝐨𝐧 for RL (G²RL)!
We know exploration is crucial in RL, but forcing entropy as a reward can inflate it in unhealthy ways.
Our G²RL measures policy-intrinsic exploration from "gradients", avoiding mismatch from external comparators (classifiers, embeddings, etc.).
🌟Key insights: rollout trajectories are preferred when they meaningfully expand the policy’s own update directions, and discouraged when they contribute redundant or uninformative gradients.
-- Easy to implement
- -Negligible overhead
-- Improves accuracy
G²RL leads to healthier, more structured exploration
Paper: arxiv.org/abs/2512.15687

This is commercial product–level quality!!
🤔🤔Tired of static, lifeless image edits?
Not anymore! 🤗
🚀🚀We introduce MotionEdit, a framework supporting image editing that understands action, motion, interaction beyond static changes! 🤩🤩
🔗Full paper: arxiv.org/abs/2512.10284
✨Project page: motion-edit.github.io
🔥 New Tencent x UCLA paper!
Even SoTA image editing models (e.g., Nano Banana, GPT-Image-1) struggle with motion editing -- changing actions, poses, and interactions.
We tackle this head-on, and do it better. 🧠✨
Paper: arxiv.org/abs/2512.10284


Wenhao Yu retweeted

Beautiful Tencent paper.
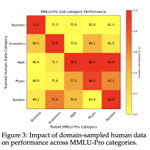
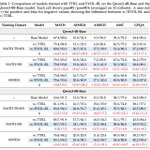
Shows a language model that keeps improving itself using only 1% to 5% human labeled questions while reaching the level of systems trained on about 20 times more data.
Earlier self play systems let a model write and solve its own questions, but over time it drifts, repeats narrow patterns, and can even perform worse.
Their method runs a challenger copy that generates questions and a solver copy that answers them, turning training into a question answer game between 2 agents.
When the challenger writes, it sometimes sees a few real human question answer pairs, which pull its synthetic questions toward realistic tasks instead of strange, off topic puzzles.
For each question, the solver tries several answers, the system estimates its success rate, and training keeps mainly mid difficulty questions where the solver is uncertain but not lost.
Because both human and synthetic questions pass this filter, the solver trains on focused, non trivial problems, avoids cheap tricks like inflating question length, and gains stronger math and general reasoning scores than earlier self play methods.
----
Paper Link – arxiv. org/abs/2512.02472
Paper Title: "Guided Self-Evolving LLMs with Minimal Human Supervision"

📢New paper: Guided Self-Evolving LLMs with Minimal Human Supervision
Self-evolving / Self-improving LLMs often plateau fast due to concept drift, diversity collapse, and mis-evolution.
Our method fixes this — keeping self-evolution stable, aligned, and on track!
Link: arxiv.org/abs/2512.02472


