
AI/LLM researcher. Exploring language, knowledge, and intelligent systems.
Shanghai
Joined April 2013
- Tweets111
- Following158
- Followers563
- Likes527


Xipeng Qiu retweeted

Try Nex-N2.6 for one week FREE
via MOSS API ↓ @MOSS_Global

Nex-N2.6 is open sourced - multimodal agentic LLM
With stronger computer use and more token-efficient in long-running tasks
Create a 3D keyboard model from one photo in Blender.
It builds the model, matches its materials, sets the lighting, and renders an animated product showcase.
A multimodal agentic model that can directly see and operate real computer interfaces.
Try it now.
⭐GitHub: github.com/sii-nex/Nex-N2.6
🤗HuggingFace: huggingface.co/nex-agi/Nex-N…
🔗OpenRouter API: openrouter.ai/nex-agi/nex-n2…
🔗MOSS API: platform.moss.cn/docs/models…
Xipeng Qiu retweeted
Watch Nex-N2.6 turn a single keyboard photo into an animated 3D showcase in Blender. ⌨️
Try it for free via the MOSS API 👇 teapawt.net/NexEcosystem/status/21…
Xipeng Qiu retweeted
Nex-N2.6 is open sourced - multimodal agentic LLM
With stronger computer use and more token-efficient in long-running tasks
Create a 3D keyboard model from one photo in Blender.
It builds the model, matches its materials, sets the lighting, and renders an animated product showcase.
A multimodal agentic model that can directly see and operate real computer interfaces.
Try it now.
⭐GitHub: github.com/sii-nex/Nex-N2.6
🤗HuggingFace: huggingface.co/nex-agi/Nex-N…
🔗OpenRouter API: openrouter.ai/nex-agi/nex-n2…
🔗MOSS API: platform.moss.cn/docs/models…
Xipeng Qiu retweeted
Meet the team behind MOSS-Image.
The @ComfyUI -Org/MOSS-Image repo on Hugging Face is over 6.3M downloads in the past month.
See what the model they trained can do. 👇 teapawt.net/ting_/status/212081531…
Xipeng Qiu retweeted

Switch from Claude Code to Codex, Cursor or your own harness, and Nex-N2.6 still calls only the tools that are actually there. The open-weight 321B multimodal agentic model from Nex-AGI is built on GLM-5.3-Flash for computer use, coding and long-horizon tasks. 📜 Apache 2.0 🤖 modelscope.ai/models/nex-agi…
🛠️ Harness-agnostic tool use: 100% valid tool selection across 956 real-world contexts, matching GPT-6-Sol and up from 80.56% for Nex-N2.5-Pro.
🔁 Far less looping: reasoning repetition drops 90%, from 16.0% to 1.6%, on 698 real failure cases replayed from the exact point where the previous model stalled. Fewer wasted tokens on long runs.
🖥️ Stronger computer use: 83.0 on OSWorld, 5.0 points above its GLM-5.3-Flash base, while holding 84.1 on Terminal-Bench 2.1.
⚡ Ready to run: 256K context via API, or self-host the FP8 weights on SGLang behind an OpenAI-compatible endpoint with low, high or max reasoning effort.


Xipeng Qiu retweeted
Meet Nex-N2.6, our latest multimodal agentic model supporting text, image, and video inputs.
Open-sourced by Shanghai Innovation Institute, the model has performed strong benchmark results:
⚡Compared with Nex-N2.5-Pro, the reasoning repetition rate falls from 16.0% to 1.6%, while the overall non-repetition rate rises from 91.0% to 97.8%
⚡Achieved 100% valid tool selection rate across 956 tested contexts, on par with GPT-6-Sol
⚡Scored 83.0 on OSWorld and 84.1 on Terminal-Bench 2.1, ahead of DeepSeek-V4.1-Flash at 71.7 and 82.7
Nex-N2.6 is built with a stronger foundation to navigate interfaces, use tools, and complete lengthy tasks without losing its place.
Try now 👇
⭐GitHub: github.com/sii-nex/Nex-N2.6
🤗HuggingFace: huggingface.co/nex-agi/Nex-N…
🔗OpenRouter API: openrouter.ai/nex-agi/nex-n2…
🔗MOSS API: platform.moss.cn/docs/models…

Xipeng Qiu retweeted
Nex-N2.6 is now available for free via the MOSS API. 🚀
Nex’s eval results
⚡ In replay tests, reasoning repetition was 1.6% vs. 16.0% for Nex-N2.5-Pro.
⚡ 100% valid tool selection across 956 tested contexts
⚡ 83.0 on OSWorld and 84.1 on Terminal-Bench 2.1
Try it now 👇
Meet Nex-N2.6, our latest multimodal agentic model supporting text, image, and video inputs.
Open-sourced by Shanghai Innovation Institute, the model has performed strong benchmark results:
⚡Compared with Nex-N2.5-Pro, the reasoning repetition rate falls from 16.0% to 1.6%, while the overall non-repetition rate rises from 91.0% to 97.8%
⚡Achieved 100% valid tool selection rate across 956 tested contexts, on par with GPT-6-Sol
⚡Scored 83.0 on OSWorld and 84.1 on Terminal-Bench 2.1, ahead of DeepSeek-V4.1-Flash at 71.7 and 82.7
Nex-N2.6 is built with a stronger foundation to navigate interfaces, use tools, and complete lengthy tasks without losing its place.
Try now 👇
⭐GitHub: github.com/sii-nex/Nex-N2.6
🤗HuggingFace: huggingface.co/nex-agi/Nex-N…
🔗OpenRouter API: openrouter.ai/nex-agi/nex-n2…
🔗MOSS API: platform.moss.cn/docs/models…
Xipeng Qiu retweeted

Models trained on machine-generated transcripts beat the labeling models that produced them, in all five Arabic dialects. @xpqiu and coauthors show this with GigaSpeech 3, 39,000 hours of weakly labeled web audio.
pith.science/paper/2611.0247…

Xipeng Qiu retweeted
The biggest lineup of open models yet for a @LocalLLaMAsub AMA. 👀
Speech, sound, music, images, video—we're bringing the whole MOSS model family!!!
🗓 Oct 30 · 8–11 AM PT
Join r/LocalLLaMA and bring your questions ➡️ reddit.com/r/LocalLLaMA/s/Ut…

Xipeng Qiu retweeted
Try MOSS-Image in ComfyUI with our free API. 🎨
⚡ Get your API key: platform.mosi.cn/?utm_source…

Xipeng Qiu retweeted
MOSS-Image API is live FOR FREE
⚡ API: platform.mosi.cn/?utm_source…
Join our Discord to share your creations, exchange ideas, and technical support: discord.com/invite/Wjku5AYyx…

Xipeng Qiu retweeted

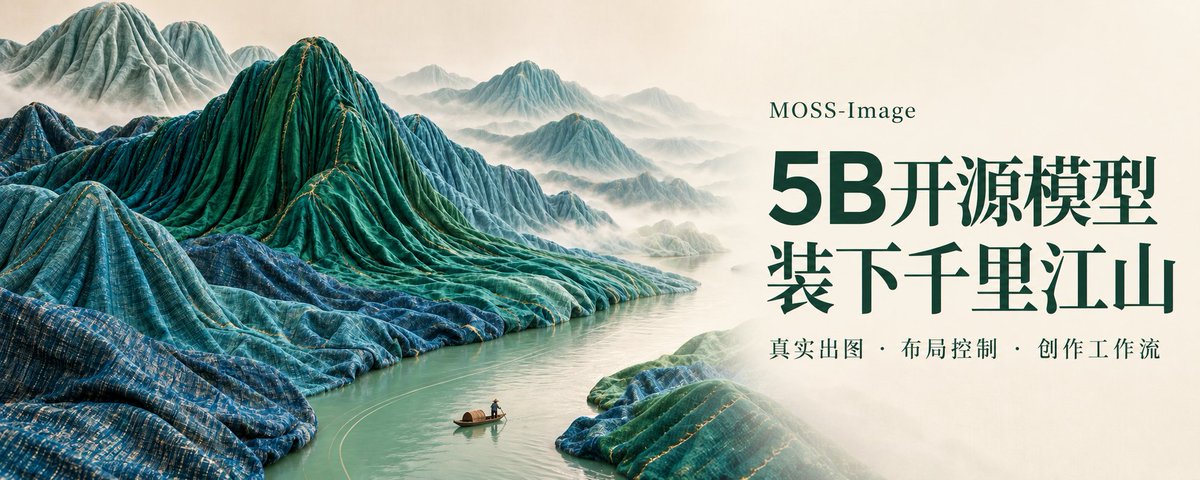
我把一城烟火、千里江山,交给了一个5B开源模型。
从宋城长卷、青绿群舞,到丝绸、青瓷和墨金山水:MOSS-Image 的真实成图、50 秒演示、提示词和 Layout 工作流都在这里。
点开长文,也去试一张。
🤝 Paid partnership
Xipeng Qiu retweeted
MOSS-Image API is coming soon in 24hrs
Join MOSS discord for FREE early access 👉 discord.gg/Wjku5AYyxx
Xipeng Qiu retweeted

Hi everyone! I'm a core dev of MOSS-Image, a 5B-parameter DiT image generation model.
Today: MOSS-Image-Base + MOSS-Image-SFT, model weights, inference code, and technical report. Our goal: a capable, controllable open-source image generation foundation for the community.
Xipeng Qiu retweeted

KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***

Xipeng Qiu retweeted
👀 want EARLY ACCESS to our next models?
join the MOSS Discord for upcoming early access opportunities, help with MOSS-Image, and ideas from fellow creators.
love seeing the community's LoRAs already 🫶 come show us yours
join MOSS discord 👉 discord.gg/z7TD5ehYts

Xipeng Qiu retweeted

Congrats to the @Open_MOSS team on the open-source release of MOSS-Image! 🎉
Proud to support MOSS-Image on Day 0 with vLLM-Omni! 🚀
Excited to help bring powerful image generation models to the open-source community and make them more accessible to everyone.

🤗 MOSS-Image is now open source on @huggingface .
Built on a 5B Diffusion Transformer (DiT), MOSS-Image brings Chinese & English text rendering and controllable layouts to image generation — from posters and infographics to creative visuals.@Open_MOSS
What it offers:
📝 Long prompts & text rendering — up to 4K-token prompts, including multi-line text
📐 Experimental JSON layout control — specify text, objects, and their positions using bounding boxes
🖼️ Flexible generation — multiple aspect ratios, resolutions, and customizable inference settings 🛠️ Developer workflows — Python (Diffusers), Gradio, ComfyUI, and a Prompt Enhancer Skill
📦 Base & SFT checkpoints are both available, with open model weights and Apache-2.0 licensed inference code.
🙌 Huge thanks to @sgl_project @vllm_project @ModelScope2022 for the Day-0 support!

Xipeng Qiu retweeted
Meet MOSS-Image-Base: an 8.56B open-weight text-to-image foundation model built for more controllable generation.
🤖 modelscope.ai/collections/op…
🧩 More than natural-language prompts: Generate from descriptive prompts, tag sequences, or JSON layouts that specify text and object placement.
📝 Layout-aware images: Control captions, scene elements, and bounding boxes for posters, whiteboards, diagrams, and other structured visuals.
🔧 Built for customization: As the base checkpoint in the MOSS-Image family, it is designed for research, fine-tuning, and workflow-specific adaptation.
🖥️ Ready for local workflows: Includes Diffusers support, a Gradio interface, CPU offloading options, and a native ComfyUI plugin.
📜 Model weights and inference code are released under Apache 2.0.

Xipeng Qiu retweeted
🤗 MOSS-Image is now open source on @huggingface .
Built on a 5B Diffusion Transformer (DiT), MOSS-Image brings Chinese & English text rendering and controllable layouts to image generation — from posters and infographics to creative visuals.@Open_MOSS
What it offers:
📝 Long prompts & text rendering — up to 4K-token prompts, including multi-line text
📐 Experimental JSON layout control — specify text, objects, and their positions using bounding boxes
🖼️ Flexible generation — multiple aspect ratios, resolutions, and customizable inference settings 🛠️ Developer workflows — Python (Diffusers), Gradio, ComfyUI, and a Prompt Enhancer Skill
📦 Base & SFT checkpoints are both available, with open model weights and Apache-2.0 licensed inference code.
🙌 Huge thanks to @sgl_project @vllm_project @ModelScope2022 for the Day-0 support!