





Pinned Tweet
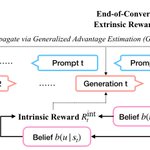
Personalization methods for LLMs often rely on extensive user history. We introduce Curiosity-driven User-modeling Reward as Intrinsic Objective (CURIO) to encourage actively learning about the user within multi-turn dialogs.
📜 arxiv.org/abs/2504.03206
🌎 sites.google.com/cs.washingt…
Yanming Wan retweeted

Excited to share that "Learning to summarize user information for personalized reinforcement learning from human feedback" is accepted to ICLR.
TL;DR We can train a conversation summarizer with RL to capture diverse user preferences for pluralistic LLM alignment.
w/ @natashajaques @mickel_liu @yanming_wan @PeterAhnnDD
arxiv: arxiv.org/abs/2507.13579
website: sites.google.com/stanford.ed…
code: github.com/nam630/pluralisti…

It’s a great honor to receive this award! Our related paper "Enhancing Personalized Multi-Turn Dialogue with Curiosity Reward" has been accepted to #NeurIPS2025. Looking forward to sharing and discussing with everyone!
📜 arxiv.org/pdf/2504.03206
🌏 sites.google.com/cs.washingt…

Congratulations to @UW #UWAllen's @yanming_wan, professor @natashajaques and collaborators on winning this year's Madrona Prize at our recent Research Showcase & Open House—and huge thanks to @MadronaVentures for supporting and encouraging our student researchers! #UWinnovates
Yanming Wan retweeted

Forget modeling every belief and goal! What if we represented people as following simple scripts instead (i.e "cross the crosswalk")?
Our new paper shows AI which models others’ minds as Python code 💻 can quickly and accurately predict human behavior!
shorturl.at/siUYI🧵

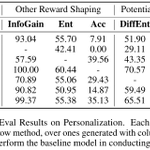
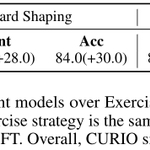
Baselines and entropy-based rewards lead to "controlling behavior", where the model gets high rewards by convincing the user to adopt a particular preference that is easier to cater to, rather than adhering to the ground-truth. "Grounded" rewards stop this reward hacking. (8/9)

Overall, we propose CURIO for enhancing personalization in LLMs for multi-turn dialogs, which encourages LLMs to actively learn user traits and adapt its responses accordingly.
This work was done with my awesome collaborators: @jiaxing_jxwu @marwaabdulhai @LiorShan @natashajaques

Yanming Wan retweeted

We introduce MMMG: a Comprehensive and Reliable Evaluation Suite for Multitask Multimodal Generation
✅ Reliable: 94.3% agreement with human judgment
✅ Comprehensive: 4 modality combination × 49 tasks × 937 instructions
🔍Results and Takeaways:
> GPT-Image-1 from @OpenAI leads image generation at 78.3% accuracy—13.7% ahead of the next-best model. The top open-source model, BAGEL from #ByteDance , achieves 45.5% accuracy.
> Audio generation is still challenging: Top open-sourced models achieve only 48.7% accuracy in sound (Make-An-Audio 2 from #ByteDance) and 41.9% in music (MusicGen from @AIatMeta).
📜 Paper: arxiv.org/abs/2505.17613v1
🛠️ Code and Evaluation Suite: github.com/yaojh18/MMMG
🥇Leaderboard: yaojh18.github.io/mmmg-leade…
🧵1/N

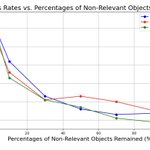
We filter out a proportion of irrelevant objects to assess the impact of excessive item quantity on GPT-4.
LLM relies on a very large proportion of objects being filtered out, showing that they can't effectively select relevant information and focus on relevant objects. (8/10)

Overall, we present FISER for ambiguous instruction following by building a model that explicitly performs social reasoning to infer the human’s intentions from prior actions.
This work was done with my awesome collaborators: @YueWu7677 @ypwang61 @maojiayuan @natashajaques (9/10)
Links
Paper: arxiv.org/abs/2409.18073
Code: github.com/Simon-Wan/FISER
Website: sites.google.com/view/fiser-…
(10/10)

In FISER, we explicitly model a human's intention by modeling the human’s overall plan as a set of predicates. We further assume that the human selects a subgoal that needs help, and specifies a robot’s task, which is the underlying intention of the instruction. (5/10)


We train FISER models from scratch using the following architecture.
The first 2N layers form the social reasoning and the last N form the embodied reasoning. The embeddings at Layer 2N are used to recognize the robot’s task and the last layer is used to predict actions. (6/10)

Even with careful CoT prompts and few-shot examples, GPT-4 Turbo is far from small-scale models trained from scratch. We compare their failure modes and find that prompting methods alone cannot provide the model with the ability of social and embodied reasoning. (4/10)

