

CTO/Founder @edge_delta | Ex @twitter and @microsoft | amor fati
Seattle, WA
Joined February 2012
- Tweets1.1K
- Following1.4K
- Followers1.5K
- Likes3.2K





Yesterday was a big day for security. A CA certificate compromise at eMudhra, a batch of PHP vulnerabilities, and new CVEs in Node.js, NGINX, Go and GitLab, all in one day. Between them, they touch millions of services. Every team running containers spent the morning asking the same question: how many of our images are affected, and how fast can we patch them?
We used to answer that question every day. We build around forty container images, which pull in hundreds of dependencies between them: Go services, Bun services for our AI team, a Playwright base and a Python MCP proxy. The scanner's list of CRITICAL and HIGH findings never stayed empty for long. Keeping it at zero took hours every week from security, DevOps and the service owners. A bump that should take ten minutes often took half a day.
Customers ask us about this a lot. "You automate observability. Can you help with security, especially patching?" This is how we do it for ourselves.
Our goal at Edge Delta is recursive self improvement for observability: agents that keep making production better, including the systems they run on. The same agents handle patching tasks very well.
We run three Edge Delta loops, one each for Go, Bun and custom base images. Each loop reads the new findings, edits the Dockerfiles and opens a PR. A CI gate rebuilds every affected image and scans it again. Then it starts the container and checks that it answers its health probe. If anything fails, the loop reads the gate log on its next run and fixes it.
A few things AI Teammates shipped so far:
• 30+ Go module bumps, including a SAML library migration
• A Bun service taken from 143 findings to zero
• Node 22 to 26 for a patched OpenSSL. The first build failed, and the next run read the log and fixed it
On days like yesterday, this is the automation that matters most.
Full write-up by Mehmet Asım Erel👇
edgedelta.com/company/blog/f…

if you skipped the "import Claude Code CLI sessions" prompt, you can get it back.
Quit the app (⌘Q), set importableCliSessionsDismissed to false in claude_desktop_config.json, and relaunch. Steps below.
#ClaudeCode #DevTips

Google's Gemini 4 Argon just went through all three of our incident response benchmarks. A month ago GPT-6 Astra became the first model to sit at the top of every board. Argon is right next to it on every one, at about a quarter of the cost.
🔷 Blast Radius Bench: 65% pass, the same rate as Astra on our hardest board. Astra keeps first place on graded score (0.726 vs 0.688) because it does better on the hard tier.
🔷 Noise Bench: 94%, third overall, just ahead of Claude Opus 5. Its only miss is slow-burn-saturation, the scenario Astra was the first to crack.
🔷 RCA Bench: tied with Astra for first, including every adversarial scenario and every case where no commit is to blame.
The cost is what sets it apart. Argon averaged $0.10 per RCA investigation, against $0.37 for Astra, $0.33 for Opus 5 and $0.59 for Fable 5.1. On Noise Bench it costs $0.08 per triage. The trade is time: Argon takes about two and a half minutes per investigation, while Astra takes about 70 seconds.
The jump from the previous generation is large too. Gemini 3.1 Pro passed 71% on Noise Bench at roughly the same cost per investigation as Astra. Argon reaches 94% at a quarter of that price.
My takeaway: last month frontier-level incident response came at a frontier price. Within a few weeks a second lab has matched it for a fraction of the cost.
Full leaderboards, methodology, and every trajectory are public.
edgedelta.com/benchmark
People ask us a lot if Edge Delta handles metrics. Yes, it does. Our pipeline does not care what the data is. Logs, traces and metrics all go through the same processors.
There is a bigger reason I care about this. Our AI Teammates are telemetry native. We own the pipeline, so we shape the data before anyone reads it, a person or an agent. Giving an AI more data does not give you a better investigation. After some point it is just noise, more tokens and slower answers.
Metrics is where you see this first. Every new label combination is a new time series. Put pod name next to service and route labels and the series count blows up quickly. Most dashboards and alerts only need the total per service.
We built a benchmark to push 1M data points per second through our gateway pipeline. Onur on our team took it further and ran it on Kubernetes for a full hour:
• 1M points/sec for 60 minutes, 3.6B points, zero failed
• 1M input series aggregated into 50K, 95% reduction
• 8 gateway pods with 4 CPU each, ~22.7 vCPU in total, memory flat around 4.2 GiB
• We picked and checked 500 stored totals, all of them matched what we sent
Fewer series with correct values. That helps the engineers on call and the agents working next to them.

Full write up edgedelta.com/company/blog/p…


Fatih Yildiz retweeted
Today, we released our new website, with what we believe to be the most clear and concise way to sum up what we're building: "your prod immune system"
AI has accelerated the SDLC which is causing the largest shift in prod ops I've ever seen in my lifetime. More code, PRs, merges, deployments than ever before, and this pace is well beyond the pace of which humans can surpass. We saw this over a decade ago with computers/AI in chess, and today not even the best player in the world has any hope of a chess engine. They lose 1000 times out of 1000. It may not feel like it yet, but prod ops is getting there at this very moment. When most engineers see the knowledge graph of their prod environment, there is immediately an aha moment. The graph is ridiculous, it's overwhelming, it's cluttered, for even tiny prod environments there are thousands of relationships, it's nearly entirely useless to the best engineers in the world. That's the point. It's not meant to be used by engineers.
Running prod from this point forward requires stochastic software (AI), deterministic software (guardrails) and humans making informed critical decisions (guardians). I do not believe we are anywhere close to RSI for this reason, without a deterministic harness around AI, it goes off the rails pretty quickly. Can that mean amazing magical things at times? Yes. Can it also carry massive levels of risk no serious business would ever internalize? Also yes.
We have intelligent data pipelines which optimize data (for agents, not necessarily for humans anymore) into indexes, we have a harness that is the most safe, open, and flexible harness in the world for prod ops, and we have a very robust set of things (top frontier and open models, customizable agents, knowledge graphs, shared context and memory, loops, real time perf evals, etc) that bring it all together.
We need autonomy for prod, but it must be earned. @edge_delta

Last week a customer opened a Zendesk ticket about a tricky concurrency issue that showed up with a specific pipeline configuration.
18 minutes later, Edge Delta AI Teammate had already picked it up, found the root cause, and opened a PR with the fix. Before any of us had even reacted to it.
Then it took us some time to review and merge it. The change was in one of our edge components, and we release those on a weekly schedule. Total: ~18h 48m from ticket to master.
But the part I keep thinking about is the first 18 minutes. No one assigned it and no one was paged. Edge Delta AI Teammate saw the ticket, dug into the code, and came back with a fix ready for review.
It's fascinating to see systems keep working while we are sleeping. We still review everything, but we're no longer the bottleneck for getting started.

Fatih Yildiz retweeted

A pod in our demo env crashlooped 300 times in 19 days. Our agents pick up such situations faster (we need a bigger drama for the demo, right?) but here our agents with the fix, deployment and verification of it.
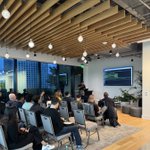
Had a great time speaking at the @ClickHouseDB × Pydata #seattle meetup, "Data Engineering in the Agentic Era"! 🎤
My talk was "Running Continuous Loops on Data Pipelines with Agents".
Everyone builds their pipeline once, but nobody maintains it 24/7. Like my Nest thermostat, you set the goals once, and an AI loop keeps volume, security, and schema stable.
Thanks to ClickHouse for hosting, to Matt Winkler and Vaibhav Gupta for great talks, and to everyone who came!
#DataEngineering #Observability #AIAgents #ClickHouse @edge_delta

#Jev from @typesafeai looks very promising for Observability Decision Model use cases.
At @edge_delta , we use frontier models for operational priority scoring, routing events, identifying recurring issues, and similar decisions. Latency adds up.
I tested Jev on our OperationPriorityScorer: reading an investigation thread and scoring its priority based on severity, business impact, urgency, and dependency context.
We selected 96 real threads, and compared Jev against GPT-5.4.
The outcome:
• 131 ms median latency vs 4.62 seconds — about 35x faster
• 72.9% agreement on operational priority bands
• 19 of 24 high/critical threads stayed high/critical
GPT-5.4 also generated explanations, so the output workloads were different.
Jev tended to assign lower priority, especially for medium-priority threads.
Still, very promising for an initial test on real observability data.


Tested Jev (typesafeai) vs GPT-5.4 on our OperationPriorityScorer: 96 real investigation threads.
131ms median latency vs 4.62s, ~35x faster
72.9% agreement on priority bands
19/24 high/critical stayed high/critical
Promising first run on real observability data.

#Jev from @typesafeai looks very promising for Observability Decision Model use cases.
At @edge_delta , we use frontier models for operational priority scoring, routing events, identifying recurring issues, and similar decisions. Latency adds up.
I tested Jev on our OperationPriorityScorer: reading an investigation thread and scoring its priority based on severity, business impact, urgency, and dependency context.
We selected 96 real threads, and compared Jev against GPT-5.4.
The outcome:
• 131 ms median latency vs 4.62 seconds — about 35x faster
• 72.9% agreement on operational priority bands
• 19 of 24 high/critical threads stayed high/critical
GPT-5.4 also generated explanations, so the output workloads were different.
Jev tended to assign lower priority, especially for medium-priority threads.
Still, very promising for an initial test on real observability data.
🤯 🎩 @OpenAI API access to GPT-6 Astra today and we ran it through all three of our incident response benchmarks within hours.
It is the first model to sit at the top of every board.
RCA Bench is the headline. 108 trials, 108 correct answers. That includes all twelve adversarial scenarios, three out of three each, and the negative cases too, where no commit is to blame and the right answer is to say so. It is also the only model that never blamed an innocent deploy. Every model before it had missed at least one trial.
Noise Bench: 96%, first place, statistically tied with Claude Fable 5.1 at the same pass rate.
Blast Radius Bench: 65%, first place on our hardest board. It solved every scenario that any model has ever solved. The five it missed are shared-infrastructure chains that all 30 models fail, so the ceiling there is now on us to raise.
What surprised me more than the scores is how it got them. Astra finishes an investigation in about 70 seconds on all three boards. Nothing else in the top ten is under 100. It writes about 2,500 output tokens per RCA investigation. Fable 5.1 writes 5,300, Opus 5 writes 5,700, GLM 5.2 writes 11,000. Same data, same tools, less reading, less thinking, more right answers. At $0.37 per investigation it costs about the same as Opus 5 and a third less than Fable 5.1.
For two months the story on these boards was convergence. A dozen models inside each other's error bars, small open-weight models closing in. Astra broke that. The frontier moved.
Hats off to @OpenAI 🎩 And our adversarial tier needs harder scenarios.
#AIBenchmarks #SRE #IncidentResponse #LLM #GPT6 #Observability @edge_delta

all our benchmarks are here edgedelta.com/benchmark and they are open sourced.