

Building Apache Maka(Incubating), focusing on AI agent. 中文/EN
Joined March 2011
- Tweets2.5K
- Following548
- Followers1.8K
- Likes3.9K


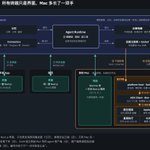


Maka 从 8 月开始也提出 Workhub 的概念,也就是由一个前端的 inbox bot 对所有需求进行分拣,交给不同的 Session 执行。
包括 Claude 的 Project,还有 Cursor 也有类似的设计,大家不约而同的走向了去 Session 的这个方向。
github.com/apache/maka/discu…

Google 这波这么牛了吗!?直接 Agent 能力干到全球第二了,仅次于 Opus 5.5,压过了 GPT 6 Astra 一头

Exciting news: Gemini 4 Carbon (High) from @GoogleDeepMind just made a huge debut on Arena, landing #1 in Text Arena, #2 in Agent Arena, and #4 in Code Arena: WebDev. Back at the top, Gemini 4 Carbon delivers frontier intelligence and reshapes the Pareto frontier across three arenas.
In Agent Arena, Gemini 4 Carbon ranks #2 with a +16.2% net improvement across +21.9K real-world agentic sessions from our global community, surpassing top models GPT-6 Astra and Fable-5.1. At $1.80 median cost per task, Gemini 4 Carbon (High) costs 72% less than the #1 ranked Claude Opus 5.5 (Max).
Its standouts by key signals:
- #1 Steerability (+18.6%): can the model course-correct when you push back?
- #2 Praise vs Complaint (+37.9%): implicit sentiment in users' reactions
- #3 Confirmed Success (+18.7%): explicit “yes, that worked” from users
In Code Arena: WebDev, Carbon scored 1768 pts landing #4:
- Just 2 pts below #3 Claude Sonnet 5.5 (xHigh), at 1770 pts
- 89 pts above #11 Gemini 4 Argon (High), at 1679 pts
By category, it ranks #3 in Gaming and Simulations, and #5 in Brand & Marketing.
In Text Arena, Gemini 4 Carbon (High) is the new #1 with 1528 pts, now ahead of Gemini 4 Argon (High) at #2 with 1520 pts.
Congrats to the @GoogleDeepMind team on this huge milestone!


现在 Maka Rust 分支已经做到,3000 个 Agent 并行的情况下,内存占用控制到 1.2GB 了。
对比之下 Codex 大概需要十几个 GB。
Maka Rust 还在持续快速迭代中,目标下个月中完成 Rust 全面切换!

现在几乎主要的 Agent 都是用 Electron 方案,Codex、Claude...一旦同时跑的 Session 和工作多了,性能消耗和资源占用都很大,尤其是 Web 渲染的各种动画。
我们在把整个 Maka 重写为 Rust + GPUI。为未来几十/上百/上千个 agent 并行做好准备。
已经几乎可用了:
github.com/apache/maka/tree/…
现在 Maka 已经把 GUI 完全做到终端里了,在 TUI 里实现了 GUI 的效果!

刚刚基本已经完成将gui带到terminal中来,基于github.com/longbridge/nsh 并添加tui支持。
实现在分支(包括vendor的nsh的tui支持)
github.com/apache/maka/tree/…
我的操作比较墨迹,时长比较长,所以建议视频开2倍速


昨天一个海外客户下单+订单管理页面,团队找用友询价,居然报2.6万美金...
整个页面和商城都停留在 10 年前的水平,技术栈感觉也很久没更新了。
自己快速搓了个 demo,评估下一周就能开发完上线,再去 AWS 买个 VPS,预计总成本 200 美金/年。
很难想象以后这些 SaaS 还有谁采购...
所有工作先在内部按可验证证据、实际影响范围和可恢复性分级,再决定顺序与投入:P0为严重、广泛或不可恢复的核心目标、安全、资金或权限损害,立即处理;P1为核心目标、关键功能或实际交付实质受阻,优先解决,不一概视为紧急;

LlamaFactory 团队开始做 Agent 自进化了!
让 Agent 根据评测反馈改自己的指令和 skills,再用测试验证有没有用。
这个和 DSH 对 Agent Harness,还有之前的一些 Agent 自进化方向的工作不谋而合。
还开源了 awesome-rsi 和 GDPevo 评测集,做 Agent 和 RSI 的朋友可以一起关注下~

👋 Hi everyone! Long time no see
We're the LlamaFactory team. After passing 70k stars on GitHub, we're now building the "LlamaFactory" of recursive self-improvement (RSI), towards a unified, efficient, stable, and flexible framework for agent self-evolution. Excited to share our team's latest work with you all.
TL;DR:
🐧 We've open-sourced PenguinHarness, a multi-agent self-evolution framework that brings every RSI algorithm under one roof, over 2,600 GitHub stars.
📖 To get a fuller picture of existing RSI work, we went through 140 papers, organized and categorized them into the awesome-rsi repo, and published a survey paper.
📊 To compare self-evolution efficiency across algorithms fairly, we built GDPevo, a self-evolution benchmark covering 6 enterprise scenarios and 240 tasks, and used it to evaluate 6 mainstream agents.
The details:
Following the same philosophy as LlamaFactory, we want to bring all RSI-related data, models, algorithms, and benchmarks into a unified open-source harness, so everyone can try and debug RSI more easily. We've already integrated 5 RSI algorithms and 7 benchmarks, and we're aiming for 100+ down the road.
Borrowing from DSH's "everything is a plugin" approach, we've packaged every algorithm and benchmark as a plugin. They're fully decoupled, so users can freely mix and match any RSI algorithm to evolve different agents. We also built a modern desktop client that installs in one click on any OS and runs locally, so you can grab the latest version from our website.
Website: penguin.ooo/
OSS Repo: github.com/Prism-Shadow/peng…
To better understand where the academic work stands today, we open-sourced the awesome-rsi repo and published a survey paper covering 140 recent works. We also mapped the trajectory of RSI against that of deep learning — many concepts line up one-to-one, only now the subject is an agent.
OSS Repo: github.com/Prism-Shadow/awes…
Paper: arxiv.org/abs/2610.14625
To better evaluate how different harnesses and methods perform at self-evolution, we built the GDPevo benchmark, spanning 6 real-world enterprise scenarios and 240 tasks. With a train/val split, it fairly measures an agent's self-evolution ability while guarding against overfitting.
OSS Repo: github.com/Prism-Shadow/GDPe…
Paper: arxiv.org/abs/2608.03764
This post isn't just about our work. We're also hoping to invite friends from academia and industry to join our open-source project. If you'd like to see your name on an open-source project and co-author papers with us, DM us and let's talk!


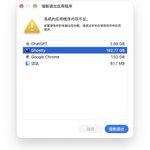
ChatGPT Web 现在可以直接调用和访问本机 Chrome 标签页了!
分析了下原理,就是 ChatGPT Chrome 插件在云端注册一个浏览器会话,作为 MCP 工具连给云端的 ChatGPT,统一由云端下发指令,插件再通过 Chrome 的 CDP 接口控制本机浏览器。
但看起来真的很黑科技了,未来会有更多 Agent 跑在云上

A few big upgrades for Chrome users today! We’re bringing the power of computer use to anyone who uses Chrome.
First up: ChatGPT can now use your tabs in Chrome to make answers more useful and get things done for you.
If you’re in Chat, it can look across your open tabs and gather info.
If you’re in Work, ChatGPT can control your Chrome tabs to get things, like sending messages, filling out forms, or downloading files. It can even help you organize and group that pile of tabs you have open.
现在几乎主要的 Agent 都是用 Electron 方案,Codex、Claude...一旦同时跑的 Session 和工作多了,性能消耗和资源占用都很大,尤其是 Web 渲染的各种动画。
我们在把整个 Maka 重写为 Rust + GPUI。为未来几十/上百/上千个 agent 并行做好准备。
已经几乎可用了:
github.com/apache/maka/tree/…
RC 的新观点依然是遥遥领先,Agent Harness 已经不再适用了,现在的模型不再需要驾驭和引导,不再需要额外的 plan mode、各种复杂的 skills、一些特殊的规则。
未来需要的是针对 Agent 薄薄的 runtime以及各种给 Agent 的各种程序,提供原生接口,或者是通过 Browser use Computer Use 访问。

I've actually stopped using the word "harness." I now think in terms of two things: agent runtimes and agent applications.
Agent runtimes should be very small. Their core job is to connect an LLM API to an execution environment. That environment could be a full OS or a language VM, like a JavaScript runtime. Almost all that matters here is robustness. An agent runtime must be able to keep an agent running forever. Literally forever.
Agent applications are everything else. Yes, literally every piece of software in the world.
If software isn't built for agents, they use it through computer use or browser use. These capabilities can be built into the agent runtime or provided by another agent application.
If software is agent-native, agents should be able to use it directly. The experience of an agent using that software—what we call "agent experience"—needs to be carefully designed, at least for now, to make efficient use of both time and tokens.
Another key piece is agent identity. Agent applications should recognize each agent individually, rather than just the browser or computer it's using. This allows each agent's actions to be recorded in detail and audited in real time or after the fact.
Everything we're building at @botiverse follows from this view.
补充一点,GPT 6.1 Sol 在 Agent Arena(模型匿名打分)的 Code 领域,是表现第一名的模型。
甚至高于 Astra。
也高于 Fable 5.1 和 Opus 5.5。
但 Opus 5.5 依然更全面,整体而言是第一名,在 Chat、Work 等工作也表现的更好,更灵活。
