

Intelligence Orchestrator, ASI, AGI, Prompting, AI Software Engineer, Algo Trader, Builder, Shipper, Agentic Loop Engineer
Joined January 2021
- Tweets14.8K
- Following1.1K
- Followers1.8K
- Likes10.6K



Pinned Tweet
DeepSeek V4.1 Flash 4× CMP 170HX optimized drop 🎙️⚡️
178 tok/s, one user. 587 tok/s across 8. 🔥
Prefill 1,570 tok/s at 2K.
KV cache 617K tokens. EXL3.
Full graphs and coop underneath, tensor-core MoE from row 43 up.
@Morrowmake
github.com/CurtisAccelerate/…


See the live:
curtisaccelerate.github.io/a…
I put the prompt into Hermes, it worked about 60 minutes with no feedback and produced what you see above. No claim is made to respecting the original benchmark requirements. I provided 4-5 turns of very generalized feedback.
bench / prompt from @niklaslenz_ai
New DeepSeek v4.1 1017 Flash 4x CMP 170HX Optimizations
Real-world optimizations
- Optimizations proven on prose, code, and real-world agentic Hermes at kernel level.
New bit-exact kernel improvements stack on my previous work:
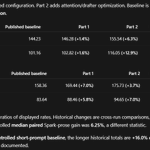
~9% cumulative from baseline, 2% latest
New attention + drafter
~16% code and 23% prose
- Not bit-exact but passed extensive A/B testing. Warrants additional quality confirmation and testing from community. Additionally, we don't claim a gain in concurrency needs additional testing.
Apply partial or both.
My machine is slower Broadwell: so will not match EPYC topline numbers but optimizations should transfer to other builds. Do take what works but give proper credit.
benchmarks and results 1017 github.com/CurtisAccelerate/…
base repo with kernel source and feature flags github.com/CurtisAccelerate/…

New DeepSeek v4.1 1017 Optimizations!
- Extended the new attention/drafter performance improvements from 1 user out to 8 user. The relative improvement is less with more concurrent streams because there's less slack and 7 requests fare worse due to specific padding but overall we saw gains across the board.
- We added sampled drafting. Most benchmarks are tested at temp 0 but Hermes/agentic default temp is 1. This drops the acceptance rate of greedy drafters on real-world tasks where the temp is not zero. Our current recommendation is greedy for temp 0, sampled for 1 request, and greedy for 2-8. We haven't tested sampled under concurrent requests. It requires some harness/serving intelligence. You can use the new optimizations with either greedy or sampled depending on your use case.
For future optimizers/optimizations, testing & optimizing drafters under real-world conditions may yield most value.
github.com/CurtisAccelerate/…

my bad, these are the better links to lead with:
github.com/CurtisAccelerate/…
github.com/CurtisAccelerate/…
DeepSeek 4.1 1017 Quality?
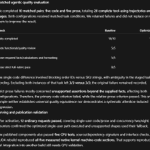
I notice some people reporting the EXL3 weights on DeepSeek 4.1 1017 produce poor outputs in reply to my build and others.
It has not been my experience with my build. It has been extremely strong in my testing. For example, I gave it a single prompt and it worked for 30 minutes building an extremely polished game that worked perfectly on a single prompt. And, I have it working on even longer run tasks.
But we did something different: we use some of the FP8 weights for important aspects.
I don't know if that makes the difference or if its the harness or server.
But, this model has impressed me and worked extremely well.

Something to know:
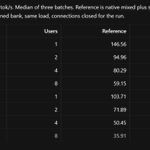
The largest perf gains, from the new attention + drafter, are only seen at concurrency/request depth 1 for now when more lanes are active, it does not use the new drafter and falls back to the previous optimized default.
This is not an inherent limitation though the relative advantage would likely decline at higher concurrency due to having more parallel work. In order to support multiple requests, requires batch-aware buffers.
The next obvious target would be request 2.
Example, on this sweep only users 1 is the new attention:


Dumb. Good thing I don't use reddit.

With Reddit banning open-source projects that have ANY AI contributions, here's a list of projects you can no longer discuss there:
Linux, Chromium, Firefox, WordPress, VS Code, Python, VLC, Blender, Git, Docker, LibreOffice, React, Node.js, PHP, TypeScript, Rust, Home Assistant, PyTorch, TensorFlow, Kubernetes, .NET, Angular, Go, Ruby on Rails, Ruby, PostgreSQL, Vim, nginx, Apache HTTP Server, FFmpeg, Redis, curl, OpenSSL, FreeBSD, Neovim, LLVM, GCC, systemd and QEMU
😂
Open source isn't as far behind frontier AI as it might appear because the frontier AI that's widely available is not the AI that leads on the benchmarks.
Codex used up in like 4-5 hours..
Weekly usage, codex credits from having Pro, and a reset used up in like 4 hours of use?
Should I be using Claude instead?