

Intelligence Orchestrator, ASI, AGI, Prompting, AI Software Engineer, Algo Trader, Builder, Shipper, Agentic Loop Engineer
Joined January 2021
- Tweets14.9K
- Following1.1K
- Followers1.8K
- Likes10.6K




The block universe is the “no this electron” of time: what you get when you describe everything and stand nowhere. Relativity kills a global now, not a local one.
Consciousness is the local now from inside, the place where the outcome is made rather than found. Whether that making is real is the measurement problem, the hard problem, and the problem of time, all at once.
Struggle is real, even though the outcome may be predetermined... replicator or entropy... whatever the force

As someone who coding in assembly and worked up to modern language, I understand your sentiments and agree with you to an extent but your insight is partial and incomplete-- fortunately, I have the exact insight to make it precise.
What really drives understanding and capability is ability to traverse through multiple layers of abstraction efficiently and importantly the ability to understand what level of abstraction/layer is salient.
Let's take problem domain like developing for retro-machines, if you have a useful abstraction/idea-- the challenge or problem is immediately going to be "explosion" of information problem where you need to solve a million small challenges. That's why even among those of us who were "good coders": few of us made games because knowing how doesn't solve the 10,000 challenges which is a function of having to work at the lowest levels of abstraction available.
So, the key isn't choosing to working at the lowest level: it is learning what the layers are and how to traverse them and provide value.
The case where AI works is when the information structures, the UI, is preserved enough that one can "dip into" just the right abstraction layer. Where it breaks down and I know what you are experiencing is when the layers themselves become indiscernible... when what's salient itself becomes lost.
I have been struggling with this on my file systems: I have an AI fully managing a linux box that I cannot even log into, no idea of the file structure, etc. I don't have the map.
At more meta-cognitive level, everything is becoming more descriptive, more pure virtualized, non ideated, the fabric of lived code is becoming-- this force almost seems like a function of entropy converting everything into pure description because nature abhors an indexcality?
It is also becoming more difficult to understand the AI while at same time I notice my writing is becoming more AI like: it may be that natural human language is a local optimal and that AI is finding new global optimal structures.
In the same way, some of what we thought as "learning" may have simply travelling through time: one can perform a multiplication through time or simply look it up in a table. Some of what we thought as skills may have been mirages of activity especially when it comes to coding. In the same way... or else what produces.
In answer to your question, it requires effort and creating structures, processes, and tools to strengthen both the information systems that produce patterns that enable the traversal of abstraction layers, sufficient understanding to know what abstraction layer is relevant, and the effortful practice of conscious intent.


See the live:
curtisaccelerate.github.io/a…
I put the prompt into Hermes, it worked about 60 minutes with no feedback and produced what you see above. No claim is made to respecting the original benchmark requirements. I provided 4-5 turns of very generalized feedback.
bench / prompt from @niklaslenz_ai

my bad, these are the better links to lead with:
github.com/CurtisAccelerate/…
github.com/CurtisAccelerate/…

New DeepSeek v4.1 1017 Optimizations!
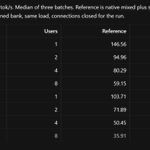
- Extended the new attention/drafter performance improvements from 1 user out to 8 user. The relative improvement is less with more concurrent streams because there's less slack and 7 requests fare worse due to specific padding but overall we saw gains across the board.
- We added sampled drafting. Most benchmarks are tested at temp 0 but Hermes/agentic default temp is 1. This drops the acceptance rate of greedy drafters on real-world tasks where the temp is not zero. Our current recommendation is greedy for temp 0, sampled for 1 request, and greedy for 2-8. We haven't tested sampled under concurrent requests. It requires some harness/serving intelligence. You can use the new optimizations with either greedy or sampled depending on your use case.
For future optimizers/optimizations, testing & optimizing drafters under real-world conditions may yield most value.
github.com/CurtisAccelerate/…

Also that learning to code + developing is different is not that different from today where in school one is encouraged to build data structures, sort algos, etc. where those things aren't practiced in professional development.
But I do agree that the era of new programming languages developed for people is probably over.
You're both wrong. But, to understand why we must pull back the veil on what it means to learn to code,
Level 1: You learn to think in a certain logical way and can think in multiple layers of abstraction. This is going to be valuable regardless whether coding preserves.
Level 2: You have earned confidence and grit. Earned confidence only comes from struggling through real difficulty.
Level 3: As a byproduct of developing, you develop experience in building and shipping. It is true you don't need to code to get to level 3 but there's no path to level 3 without developing: you are already level 3 and see your coding isn't valuable.
Level 1 and 2 can be attained in 2 years provided one isn't using AI. Level 3 takes 10 years and there's no easy path to level 3 without being a developer.
While task of coding is easier, being a software engineer is now more difficult than before because there's no simple formula for getting to a level where one can provide value. Before, it was simple-- just specialize in something.
There's another distinction to be understood: the promise of coding was always a false-promise. Because the promise was always: learn to code and develop anything. That was never true because specialized knowledge gaps.
Here's how I'd structure a 4 year program for a developer of tomorrow, fwiw:
First 2 years: coding + developing with no AI permitted.
Second 2 years: focus exclusively on agentic development and specifically focusing on building loops, observability, security, devops, selling.
DeepSeek 4.1 1017 Quality?
I notice some people reporting the EXL3 weights on DeepSeek 4.1 1017 produce poor outputs in reply to my build and others.
It has not been my experience with my build. It has been extremely strong in my testing. For example, I gave it a single prompt and it worked for 30 minutes building an extremely polished game that worked perfectly on a single prompt. And, I have it working on even longer run tasks.
But we did something different: we use some of the FP8 weights for important aspects.
I don't know if that makes the difference or if its the harness or server.
But, this model has impressed me and worked extremely well.


Understand the sentiment but I haven't found it poor at all!
It has been truly excellent.
Do not assume my build is same as others: I use the full quality NGRAM weights.
I have seen it work for 30 minutes perfectly in Hermes on a single prompt to produce perfect working game.
Something to know:
The largest perf gains, from the new attention + drafter, are only seen at concurrency/request depth 1 for now when more lanes are active, it does not use the new drafter and falls back to the previous optimized default.
This is not an inherent limitation though the relative advantage would likely decline at higher concurrency due to having more parallel work. In order to support multiple requests, requires batch-aware buffers.
The next obvious target would be request 2.
Example, on this sweep only users 1 is the new attention:


New DeepSeek v4.1 1017 Flash 4x CMP 170HX Optimizations
Real-world optimizations
- Optimizations proven on prose, code, and real-world agentic Hermes at kernel level.
New bit-exact kernel improvements stack on my previous work:
~9% cumulative from baseline, 2% latest
New attention + drafter
~16% code and 23% prose
- Not bit-exact but passed extensive A/B testing. Warrants additional quality confirmation and testing from community. Additionally, we don't claim a gain in concurrency needs additional testing.
Apply partial or both.
My machine is slower Broadwell: so will not match EPYC topline numbers but optimizations should transfer to other builds. Do take what works but give proper credit.
benchmarks and results 1017 github.com/CurtisAccelerate/…
base repo with kernel source and feature flags github.com/CurtisAccelerate/…
