

Into fun uses of ai from storytelling, entertainment, gaming and more. Opinions are my own, follow at your own risk.
Earth
Joined May 2009
- Tweets2.5K
- Following2.1K
- Followers1.6K
- Likes17.4K




🟩 Snatcher (G8+) retweeted

This is Genie 4, our most realistic and interactive world model yet. 🌐
Explore dynamic environments in real time to see how the scene responds, sounds, and how the people in it move, react, and speak.

🟩 Snatcher (G8+) retweeted

Spent years watching models ace a single image and completely whiff on anything that moves or changes angle. Today we’re fixing that.
Try Glimpse now, our first visual thinking model with competitive frontier performance compared to Astra on key public visual reasoning benchmarks.
🟩 Snatcher (G8+) retweeted

New on our Engineering blog: Creating in-house source control.
In May, we merged around 2,500 code changes per day. In September, we merged more than 30,000 per day. As a result, we became bottlenecked by developer infrastructure built for human (rather than agent) scale.
Here, we share how we built a new version control system—and fully migrated our monorepo from git—in five months: anthropic.com/engineering/re…

🟩 Snatcher (G8+) retweeted

Watch the new trailer for Gossip Goblin's #GodsDontGiveGifts, coming to theaters this December.
🟩 Snatcher (G8+) retweeted

🚨NEW EXPERIMENT 🚨
Playground is an experimental gaming platform that lets you create your own games with zero coding experience. If you can think it, you can play it.
Go to labs.google/playground to learn more! Available to users 18+ in the US.
🟩 Snatcher (G8+) retweeted

NVIDIA and MIT researchers just used Karpathy’s method to cut Agent harness costs by 2x - dropped 15-page PDF
The shift: one formula replaced prompt engineering: same LLM, same benchmark - change just the harness
here’s how they built it:
step 1 → inspect the agent’s execution logs - repeated actions, growing context, oversized outputs - find where tokens stop moving the task forward
step 2 → run Karpathy’s loop on the harness: propose → implement → review → test → keep or discard. Fix the quality and efficiency gates before the search starts
four fixes survived:
step 3 → fuse actions: edit the file and run its planned test in one tool call - remove the model round trip between them
step 4 → compact at completed steps - but only when expected savings outweigh the cost of rewriting the cached context
step 5 → stop replaying huge outputs: archive them, send them twice, then keep a handle and short excerpt. Retrieve exact pages when needed
step 6 → delegate log reading to a cheaper model - verify its evidence against the original. If verification fails, return the full log
how to steal this for your agents:
step 7 → start with one mechanism in Pi, where their code runs. Measure it against your current setup before combining all four
step 8 → freeze the changes, then test on unseen tasks. Track completion, API cost and tokens together - a cheaper failure is still a failure
the result:
50-54% lower API costs than native Codex and Claude Code on EdgeBench - using the same main LLMs
Against Pi: about one-third cheaper, 45-49% fewer tokens, retaining roughly 94% of its average score
bookmark this 15-page PDF - then build the full workflow from the article below ↓


🟩 Snatcher (G8+) retweeted

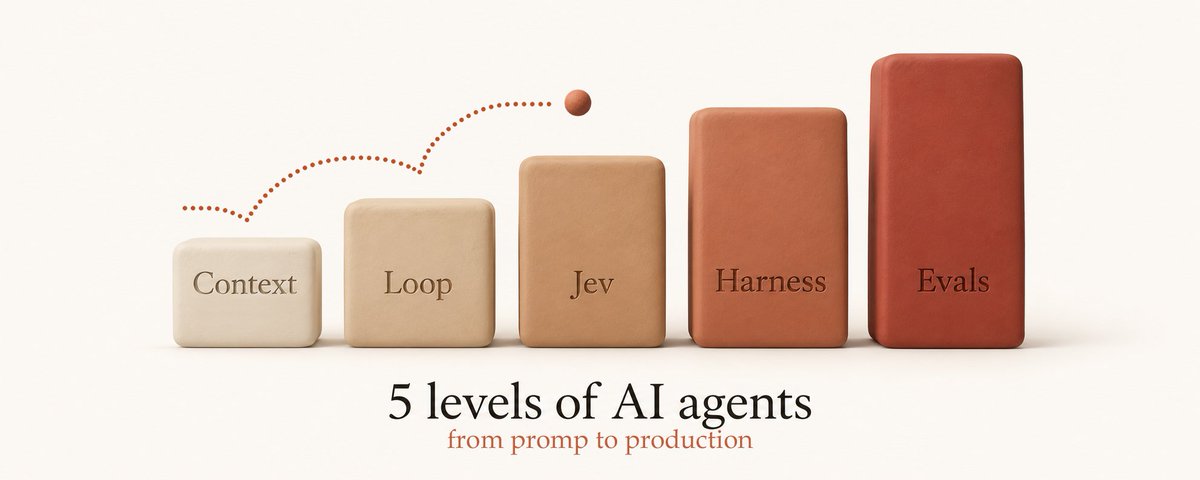
Here's how frontier teams went fully AI-native in how they build. With Amazon as the example
AWS's VP of Agentic AI just shared what happened when Amazon teams rebuilt how they work around coding agents:
> 6 engineers rebuilt Bedrock's inference engine in 76 days. It was scoped for 30 people and 12-18 months
> Prime Video cut a 90-week project to 24 weeks
> 25 Amazon Stores teams ship a median 4.5x faster
What they changed is simple enough to try on your own team:
Code and docs live in one repo, and nobody deletes the comments the agent leaves. Next session it reads its own notes instead of rediscovering your codebase from scratch.
Before a big push, someone senior spends real time cutting the project into small tasks. At Prime Video that took 3 weeks, and the sprint itself took 10 days.
Hard features get a proper spec. Simple stuff goes straight to the agent.
Then they queue up tasks, launch several agents at once and go do something else. Some run overnight. You come back to finished work instead of babysitting a chat.
Agents also run the integration tests themselves and fix what breaks, so when you review, you're looking at design decisions, not typos.
The first two weeks feel slower. That's normal, it compounds after.


🟩 Snatcher (G8+) retweeted

Atlassian's State of Product 2027 report is out, and one finding explains most of what I've been hearing from product leaders this year.
80% of product teams say they're shipping faster with AI. Customers aren't getting value any sooner.
The team behind Jira Product Discovery surveyed 1,000 senior product professionals across the US, Germany and France, so this isn't a small sample. Here's what stood out to me:
1. Decision-making didn't speed up. 69% say it's exactly as slow as before. The coding got faster, the docs got faster, and then it all sits in the same meetings waiting on the same debates about what to build.
2. AI adoption is done. 99% say AI is fully integrated into their workflows. Nobody is piloting anymore, so having AI is no longer an advantage over the team next door.
3. The PM role is blurring. 89% are doing other functions' work with AI and 67% can no longer clearly define their own job. Designers are prototyping, engineers are writing specs, PMs are doing a bit of everything.
4. Product is sharing the stage more. Only 24% say Product leads cross-functional work, down from 47% in 2025. That is the biggest drop in the whole report.
5. Prioritization still runs on opinion. Customer feedback, product data and business context sit across dozens of tools, nobody sees the full picture, and roadmap calls default to whoever's loudest. AI didn't touch this problem because the inputs were never connected.
6. Deciding what to build matters more than ever. 86% say so. Driving measurable business results tops this year’s list of rewarding work. Last year, it sat at the bottom.
My read is that for most teams, speed was never the real constraint. Alignment and customer insight were. AI just removed the excuse. When building is cheap, a team's quality shows up entirely in what it chooses to build, and a lot of teams are finding out their choosing process was weaker than their shipping process.
The upside is that the hard part moved to exactly where PMs are supposed to add value. Deciding well was always the job. It's just harder to hide bad decisions behind slow delivery now.
The full report has the year-over-year data and a section on how the high-performing teams are handling this. It's worth the 20 mins: go.atlss.in/eepnpy
Where is this pressure showing up for you?
#ad #AtlassianPartner
🤝 Paid partnership

🟩 Snatcher (G8+) retweeted

introducing Jevbox: an open-source document drive that organizes itself, answers questions, and cites everything (all powered by Jev).
TLDR;
- upload anything and Jev categorizes and files it into the folder tree
- search is hierarchical: Jev picks the folder, then the document, then the section. No embeddings, no vector DB
- every answer cites the page and section it came from
- permissions are enforced at retrieval. If someone loses access to a source, they lose access to answers built on it too
- ships with an MCP server, so your agents get the same permission-aware context
@andrewlu0 has been experimenting with Jev internally and wanted to see how far it could go on a real document library. It's built on Extend Parse + Jev, and fully open-source
The GitHub has instructions to self-host, or you can deploy it to Render in one click
🟩 Snatcher (G8+) retweeted
THE VIBE MANUFACTURING PLAYBOOK
1. Measure everything. Digital calipers for small parts, a phone LiDAR app like Polycam to scan a space or an object. Bad measurements are the #1 reason first builds fail
2. Have a frontier model write the design as code. Describe the part to a model like Claude Opus 5.5 or Astra, and have it write the design in a codebased CAD tool like OpenSCAD or CadQuery. Zoo's Text to CAD does it in one step!
3. Use real CAD files. The text to 3D models on Hugging Face make shapes that look right, but factories need precise files: STEP for machined parts, DXF for lasercut metal, STL for 3D printing
4. Make sure it can be made. Ask the AI to check the design against how factories actually work: how tight metal can bend, how small a hole can be, how much wiggle room parts need etc...
5. Prototype in plastic first. A $300 to $600 home 3D printer like a Bambu Lab lets you test the fit overnight before paying for metal (really fun to play with too!)
6. Pay an engineer for 1 hour. Before your first real order, have a mechanical engineer on Upwork etc review the files. It's the cheapest insurance you'll ever buy.
7. Send it out. SendCutSend cuts and bends metal, Xometry and Protolabs handle machining and plastic, JLCPCB builds circuit boards. Instant quotes, and parts usually ship in days.
8. Add the brains. Most smart features run on a cheap wifi chip like the ESP32. Design the board in KiCad, and use ESPHome to control it straight from your phone.
9. Make one, then fix it. Your first version will be off somewhere! Order a single unit, test it, and adjust.
10. Do the math. Add up parts, finishing, assembly, packaging, and shipping. Custom products are hard to resell, so price for healthy margins.
11. Sell the design and make to order. Let customers adjust the measurements, and only manufacture after they pay. Zero warehouse, zero unsold stock.
12. Handle the boring part. If it plugs into a wall or touches kids, you'll need safety certification. It's slow and annoying, which is exactly why it's a moat.
13. Scale when it works. Once orders are steady, switch to batch runs and your cost per unit drops fast.
Vibe coding changed who can build software!
Vibe manufacturing is about to change who can build things!!
Even if you just want to make things for yourself (and not make things for others)
WELCOME TO THE VIBE MANUFACTURING ERA

We are now entering into an era where any product can be created exactly to a consumer's preferences & needs.
I vibe-fabricated a dog door with a wifi-controlled lock, perfectly to the specifications & design of my house.
I know nothing about metal fabrication or electrical engineering.
It's now getting manufactured and delivered in 2 weeks -- for almost the same cost if I bought a mass-produced item off-the-shelf.
🟩 Snatcher (G8+) retweeted

98% of US households aren't paying for AI yet
More charts in State of Markets II: a16z.news/p/state-of-markets…


Introducing our State of Markets pt 2, along with a companion podcast where we unpack the data and discuss what comes next.
Tech is the everything cycle.
Supply: putting the buildout in context, just passed railroads as % of GDP. The wisdom of Elon is real: the factory (or the datacenter!) is the product.
Demand: diffusion is so, so early. Median AI vendor spending in the top 1% of companies is 8x that of the top 10%. Only about 30% of S&P 500 companies report a quantified AI impact, which means there’s a substantial opportunity in connecting models to a company's data and workflows. Diffusion into companies is one of the main themes of the next 5 years.
We’re entering the agent work period. Only a few million users today, but applicable to billions of internet users with massive surplus created. META/GOOG monetize US users at $200+ per year today. Agent opportunity is much higher.
Mega-trends the next 5 years: Consumer agents, Robotics, Autonomy, AI x bio, Personal health, Diffusion into enterprise, New era of American Dynamism.
Much more in our SoM report here - a16z.news/p/state-of-markets…
@a16z @sarahdingwang @aleximm @santiago__rdz


🟩 Snatcher (G8+) retweeted

Today we’re introducing a next-generation Federated Learning system. By using Trusted Execution Environments (TEEs), it delivers verifiable differential privacy while moving computation server-side to cut training times. Read the blog: goo.gle/4hIPtWX

ALT This diagram shows both the flow of data through the system as well as the steps needed to validate the privacy guarantees of workloads running on the system.
🟩 Snatcher (G8+) retweeted
"explain how Shazam works"
I had no idea
Karpathy is so right about this
custom explainer videos will change education

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.

🟩 Snatcher (G8+) retweeted

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
🟩 Snatcher (G8+) retweeted
Where does money invested into the AI buildout actually go?
For every $100 flowing into the supply chain:
- $50 to chips
- $20 to power
- $15 to networking
- $15 to cooling, buildings, and land
More charts in State of Markets II: a16z.news/p/state-of-markets…

Introducing our State of Markets pt 2, along with a companion podcast where we unpack the data and discuss what comes next.
Tech is the everything cycle.
Supply: putting the buildout in context, just passed railroads as % of GDP. The wisdom of Elon is real: the factory (or the datacenter!) is the product.
Demand: diffusion is so, so early. Median AI vendor spending in the top 1% of companies is 8x that of the top 10%. Only about 30% of S&P 500 companies report a quantified AI impact, which means there’s a substantial opportunity in connecting models to a company's data and workflows. Diffusion into companies is one of the main themes of the next 5 years.
We’re entering the agent work period. Only a few million users today, but applicable to billions of internet users with massive surplus created. META/GOOG monetize US users at $200+ per year today. Agent opportunity is much higher.
Mega-trends the next 5 years: Consumer agents, Robotics, Autonomy, AI x bio, Personal health, Diffusion into enterprise, New era of American Dynamism.
Much more in our SoM report here - a16z.news/p/state-of-markets…
@a16z @sarahdingwang @aleximm @santiago__rdz
🟩 Snatcher (G8+) retweeted

Introducing JEV-27B-VL.
We believe it is the world’s first open-weight, near-SOTA multimodal decision model — built with AutoTrust AI’s Blocks of Experts (BoE) recipe.
It does not just describe what it sees. It turns visual state into calibrated action probabilities, then selects what to do next.
In this demo, it sees Mario’s position, movement, obstacles, and timing — then chooses whether to run, jump, or do both.
See → decide → act.

🟩 Snatcher (G8+) retweeted
I built a working StarCraft level with Sonnet 5.5.
You play Terran, defending your base against the Zerg:
→ Build Marines, Siege Tanks, and Battlecruisers
→ Use SC2 models from Sketchfab (by Catholomew)
→ Music generated with Suno
📌 Play it here: terran-defense-alpha.vercel.…
Sonnet also made the sizzle reel below. Check out my latest tutorial on Sonnet here: youtu.be/MLnsMIbibZY

Sonnet 5.5 is like Opus 5.5 except it's 50% cheaper while also being insanely fast.
The speed makes it incredible at making and editing videos. Here’s my new tutorial where I walk through how I used @claudeai's new model to make 7 videos, including:
→ A dynamic motion graphics reel
→ Product launch videos and viral shorts
→ An anime opening music video (!)
The opening sizzle reel alone is worth the watch.
📌 Watch now: youtu.be/MLnsMIbibZY

🟩 Snatcher (G8+) retweeted

This is actually insane. With the latest AI models, I was able to make a fully playable demo in this art style that you can play in your browser!
Check it out -> pokemon-battle-sim-1vq.pages…


