
Cancer researcher with an interest in bioinformatics and protein design Google Scholar: https://teapawt.net/t.co/UUNsPGcEjX
Joined August 2017
- Tweets842
- Following187
- Followers37
- Likes8.4K






Jeff Brender retweeted

I must be among an extremely small group of people (n=1?) that have both 1) trained a frontier LLM and 2) designed and synthesized custom viruses in a lab with my own two hands.
And I think that the takes on AI killing us all by creating dangerous viruses is total bogus.
Jeff Brender retweeted

The AI Pandemic Isn’t On Its Way - The Atlantic theatlantic.com/health/2026/…

Jeff Brender retweeted

Some thoughts about the Anthropic report and the accompanying NYT piece on detecting nefarious biological applications of Anthropic's AI. Firstly, I am glad that they wrote this; describing how people might be potentially using your tech for doing bad things even as you are planning an IPO takes some courage. It's the responsible thing to do. That being said, here's my take:
One thing that bothers me about a lot of discussion around AI-enabled biological risk is the way the argument quickly moves through several very different layers and claims as though they were equivalent. The problem is that non-specialists especially can move through this chain very quickly to support unsubstantiated conclusions.
The chain roughly is: AI can do impressive biological reasoning and design, THEREFORE AI can substantially enable dangerous wet-lab biology, THEREFORE catastrophic biological attacks become much more likely.
But those are not the same proposition, and they hide a lot of devil-in-details subtleties. First of all, we must acknowledge that the evidence for the first is increasingly strong. AI systems can reason about biology, analyze sequences, propose protein and gene designs, generate hypotheses, suggest experiments, and in some cases outperform experts on computational tasks. As a computational scientist I myself do this all the time. There is no doubt at this point that AI gives you access to an incredible amount of compressed and potentially actionable information.
But the jump from that to real-world biological capability is much larger than it is often made to sound. A computationally plausible sequence is not a functioning phenotype. A functioning construct is not a robust organism. A robust organism is not necessarily stable, producible, transmissible, deliverable, or effective in the real world. Those of us who have worked in computational chemistry or biology for a long time know how riddled with false positives and negatives and plausible-but-wrong conclusions the results of these investigations are and how much work it takes to substantiate or falsify ideas. Getting an experiment to work on a small scale in biology is hard enough; scaling the experiment and make it robust and impervious to multiple external confounders is extremely difficult. The problem is not a lack of models, it's simply what we don't know. The value of ignorance in biology cannot be underestimated.
Especially in biology, the downstream steps are often where most of the science lives. This is why I think many biological AI-risk case studies have a structural problem. They often provide evidence for one or two links in a long causal chain - usually a combination of literature searching, hypothesis generation and computational design - and then hand-wavingly invite the reader to fill in the gaps and emotionally supply the rest. I say "emotionally" because that is in fact how lay readers will react to articles like the one in the NYT about Anthropic's report.
If we were to sketch the actual chain of biological discovery, it's more like:
Intent ---> access---> useful AI reasoning and hypothesis generation ---> successful design ---> successful experimental realization (including multiple independent runs with controls and confounders) ---> robust phenotype ---> scaled production ---> dissemination ---> consequential exposure.
This chain exists for both a cancer drug and toxin; it's just how science works. Showing that AI improves one or two of those steps does not establish that the entire chain has suddenly become easy. And yet the rhetoric frequently conflates multiple steps, as if the unmeasured gaps have already disappeared.
There is another important distinction here: capability versus qualitative improvement. The relevant question is not simply, “Can an AI system provide useful biological information?” Of course it can. The question is: how much does AI increase a person’s real-world ability to do something dangerous beyond what was already possible using PubMed, textbooks, protocols, databases, software, collaborators, and the Internet? If AI enables someone to accomplish in six weeks what they would have accomplished in six months, that's an impressive demonstration of AI acceleration, but by itself it does not make AI qualitatively more enabled to cause harm. Proving whether AI really takes the capability to the next level is a much harder empirical question, and one whose answer we frankly don't yet know. As mentioned earlier, there is now good evidence that AI can produce a meaningful and impressive signal on computational biology tasks. But evidence that this computational enhancement translates into comparable uplift across the physical bottlenecks required for serious biological misuse is still much thinner.
There is also a profound asymmetry here that deserves much more attention. Anthropic’s own researchers have acknowledged that, in many biological interactions, they could not reliably determine whether the user’s ultimate purpose is beneficial or malicious. That means the base rates are heavily skewed toward researchers doing important benign research. The overwhelming majority of people asking about proteins, mutations, viral biology, immune evasion, delivery, stability, expression, or experimental optimization are trying to do useful science, not build biological weapons. So a safety system designed around ambiguous capabilities rather than demonstrated malicious intent will inevitably face a false-positive problem. And because legitimate biological research is vastly more common than malicious biological research, even a seemingly “accurate” classifier can block far more beneficial work than harmful work.
When you cannot reliably infer intent, the burden of broad restrictions disproportionately falls on the enormous population of scientists, engineers, physicians, students, and companies trying to use the same capabilities for beneficial purposes. A false negative might enable misuse, but millions of false positives will quietly but insidiously suppress scientific progress much more than they will quell misuse. When this suppression translates to missed drugs for cancer, missed antibodies against immune disorders, missed cures for rare disease, the cost is very real and very significant.
None of this means biological risk from AI should be ignored. I am not saying nobody in the near future would ever be able to produce a reasonably potent virus or toxin substantially aided by AI. Precaution is reasonable, and genuinely dangerous capabilities should absolutely be evaluated. We have had preparedness and response frameworks for chemical and biological risk for a long time, and AI does not change the necessity for having them. But precautionary reasoning or preparedness should not be confused with evidence that a catastrophic capability already exists, nor does it give us license to amplify a low-probability, (relatively) low-impact scenario into a mass casualty event.
As a minor but important point, we should therefore make sure that certain words don't automatically translate into other words that are unsubstantiated. “Cannot rule out” is not the same as “has been demonstrated.” And “AI helped with biological design” is not the same as “AI erased the gap between biological knowledge and reliable biological weaponization.”
If we want a serious discussion of AI biological risk, we should estimate the whole causal chain rather than demonstrate the first few links and let fear fill in the rest. Otherwise we will cause panic, fear-mongering and greater public reluctance to adopt this technology, and instead of minimizing harm, all we will end up doing is to apply a blunt tool to a subtle problem and minimize the enormous good that AI can do.
anthropic.com/threat-intelli…
nytimes.com/2026/09/10/us/po…
@ramez @p_maverick_b @SynBio1 @baym @OmicsOmicsBlog @anshulkundaje @Noahpinion

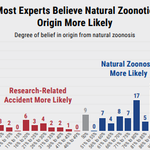
Amid all the outrage over Fauci and others believed early on, no one has seriously tried to debunk Proximal Origin on its *scientific* merits. Does SARS-CoV-2 closely resemble any known natural virus enough to suggest engineering? No. Can it be built from known viruses? No
1
60
Jeff Brender retweeted

How much does a scientific claim actually change between the preprint and the final published paper?
We used a large language model to track it across all available 72,644 bioRxiv -> journal pairs from 2018 - 2025 in this new work with @HaoYin. 🧵

Jeff Brender retweeted

Have you wondered what the wet lab success rates are for current AI-driven protein design models? Look no further!
In our new open access review, @KevinKaichuang, @avapamini, @SarahAlamdari, and I report wet lab success rates for *over 200* different protein design tasks 🧬💻


Myocarditis rates for the COVID-19 vaccine fell to baseline with the introduction of the bivalent booster

One of the most common problems in the vaccine debate is people citing myocarditis rates that are either inaccurate, outdated, or both. This is a good example.
The 2/10,000 rate (20 per 100,000) claimed here by Dr. Murthy is not supported by any published study I’m aware of. National surveillance in South Korea found the highest dose-specific rate in adolescent males was 5 per 100,000 after dose 2 of BNT162b2 (Ahn 2024, J Korean Med Sci 39:e317). CDC’s Vaccine Safety Datalink, which actively monitors 12-39 year olds, found rates of about 38 per million after dose 2 of the original monovalent vaccine. That was the peak. It’s 3.8 per 100,000, not 20.
But more importantly, that was 2020-2021. The VSD data show that myocarditis incidence dropped with each subsequent formulation and is now back at background levels of about 2 per million for the 2024-2025 doses. A Danish study of over 1 million adults who received the JN.1-adapted vaccine found a myocarditis IRR of 1.12 (95% CI 0.41-3.10), no association (Andersson 2025, JAMA Netw Open 8:e2523557). Two U.S. studies of the XBB.1.5-adapted vaccines also found no signal (Pan 2025, Nat Commun 16:6514; Sun 2025, Vaccine 45:126629).
Citing a historical peak rate, inflating it by 4-5x, and presenting it as if it reflects the current risk is not a serious argument.

1
77


Jeff Brender retweeted

Toward truly generalizable binding affinity prediction
Accurately predicting protein–ligand binding affinity is a cornerstone of structure-based drug design. Deep learning models have made major progress—but benchmarking them reliably is harder than it seems. Overlaps between commonly used training and test sets (such as PDBbind and CASF) can make models appear to generalize better than they truly do.
David Graber and coauthors take an important step forward with PDBbind CleanSplit, a carefully curated dataset that removes structural overlaps using protein 3D similarity, ligand Tanimoto scores, and pocket-aligned ligand RMSD. The result is a cleaner separation between training and evaluation data, enabling a more realistic measure of model generalization.
They also introduce GEMS, a sparse graph neural network that integrates protein–ligand interaction graphs with embeddings from large protein and chemistry language models. Trained on CleanSplit, GEMS maintains strong accuracy on CASF and independent test sets, even without benefiting from overlapping examples—showing genuine understanding of molecular interactions.
Why this matters: as generative methods like AlphaFold3, RFdiffusion, and DiffSBDD begin creating massive libraries of new protein–ligand complexes, the field needs scoring functions that can assess novel structures with confidence. CleanSplit and GEMS together provide a foundation for the next generation of robust, data-leakage-free affinity prediction.
Paper: nature.com/articles/s42256-0…

Jeff Brender retweeted
Do co-folding models learn physics—or just memorize pockets?
Deep models like AlphaFold3 and RoseTTAFold All-Atom can place small molecules into protein pockets with eye-popping accuracy. But when chemistry changes, do they still obey sterics, electrostatics, and chemistry—or just stick the ligand where training data “expects” it?
Matthew Masters, Amr Mahmoud, and Markus Lill probe this with physically motivated stress tests. They mutate binding sites (strip contacts to Gly, overpack with Phe, invert properties) and edit ligands (methylate sugars to kill H-bonding; flip ATP’s triphosphate to positively charged groups). If models understood interactions, poses should shift—or unbind entirely.
Instead, several co-folding models frequently keep nearly the same pose in the same pocket, sometimes with steric clashes or implausible electrostatics. Scaling to CASF-2016 shows the effect broadly: many poses persist despite disruptive pocket edits. Independent funnel metadynamics then indicates these mutated complexes should not bind, confirming the non-physical predictions.
Takeaway: co-folding is a breakthrough, but for drug design you still need physics in the loop. Use pose sanity checks (clash counts, Coulomb maps), replicate with varied seeds, and validate critical cases with MD/free-energy. Next-gen models should bake in hard priors (repulsion, charge, geometry) and be benchmarked on adversarial chemistry, not only native poses.
Paper: nature.com/articles/s41467-0…

Jeff Brender retweeted

Holy shit...Stanford just built a system that converts research papers into working AI agents.
It’s called Paper2Agent, and it literally:
• Recreates the method in the paper
• Applies it to your own dataset
• Answers questions like the author
This changes how we do science forever.
Let me explain ↓

Jeff Brender retweeted

Earlier this year, the President’s budget proposed a 40% cut to the NIH budget.
This sparked an obvious research question:
What if the NIH had been 40% smaller in previous years?
Here’s what Pierre Azoulay, Danielle Li, Bhaven Sampat, and I found when we looked at grants that were at-risk of being cut in an alternative history with a smaller NIH budget:
- 51% of 21st century drugs have a patent that cites one or more articles funded by an at-risk grant
- 12% of drugs have more than a quarter of their patent-to-paper citations going to at-risk research
- 35% of drugs that acknowledge NIH support reference a grant that would have been at-risk
We were able to make these estimates because we have access to the real priority scores for all NIH grants made over 1980-2007. Since NIH mostly funds research by working down these priority scores until the budget runs out, we can identify the grants that would probably have been cut with a smaller budget.
Would anyone miss the research funded by these at-risk grants? To help assess that, we link these at-risk grants to drugs, focusing on all 557 FDA approvals for new molecular entities approved in the 21st century.
Most new drugs are protected by patents. We look at these patents to see if they cite research funded by at-risk grants. We find 51% of drugs have a patent that cites one or more articles funded by an at-risk grant.
This doesn’t mean 51% of drugs wouldn’t exist if the NIH had been 40% smaller. Various caveats cut in different ways (see discussion in the online appendix). But we take this as evidence that the benefits of at-risk NIH research are wide and diffuse.
We consider other ways to link drugs with at-risk grants. For example, we find that 12% of drugs have more than a quarter of their patent-to-paper citations going to at-risk research. See the paper for some examples of specific drugs.
Finally, it’s less common, but in some cases, drugs directly acknowledge support from specific NIH grants in their patents. Only 40 drugs acknowledge NIH grant support, but of that group, 14 (35%) acknowledge support from a grant that is at-risk.
Are drugs linked to at-risk research worse? We look at two proxies for drug value: whether a drug gets priority review at the FDA, and stock market reactions when a drug patent is announced. Yes, very imperfect, but we think still worth looking at.
We find that drugs that cite at-risk research are, on average, no less likely to get priority reviews at FDA and do not have worse implied valuations by the stock market. In short, we don’t have reason to believe drugs linked to at-risk research are worse.

Jeff Brender retweeted

🚨 BAD news for Medical AI models.
MASSIVE revelations from this @Microsoft paper.
🤯 Current medical AI models may look good on standard medical benchmarks but those scores do not mean the models can handle real medical reasoning.
The key point is that many models pass tests by exploiting patterns in the data, not by actually combining medical text with images in a reliable way.
The key findings are that models overuse shortcuts, break under small changes, and produce unfaithful reasoning.
This makes the medical AI model's benchmark results misleading if someone assumes a high score means the model is ready for real medical use.
---
The specific key findings from this paper 👇
- Models keep strong accuracy even when images are removed, even on questions that require vision, which signals shortcut use over real understanding.
- Scores stay above the 20% guess rate without images, so text patterns alone often drive the answers.
- Shuffling answer order changes predictions a lot, which exposes position and format bias rather than robust reasoning.
- Replacing a distractor with “Unknown” does not stop many models from guessing, instead of abstaining when evidence is missing.
- Swapping in a lookalike image that matches a wrong option makes accuracy collapse, which shows vision is not integrated with text.
- Chain of thought often sounds confident while citing features that are not present, which means the explanations are unfaithful.
- Audits reveal 3 failure modes, incorrect logic with correct answers, hallucinated perception, and visual reasoning with faulty grounding.
- Gains on popular visual question answering do not transfer to report generation, which is closer to real clinical work.
- Clinician reviews show benchmarks measure very different skills, so a single leaderboard number misleads on readiness.
- Once shortcut strategies are disrupted, true comprehension is far weaker than the headline scores suggest.
- Most models refuse to abstain without the image, which is unsafe behavior for medical use.
- The authors push for a robustness score and explicit reasoning audits, which signals current evaluations are not enough.
🧵 Read on 👇

Jeff Brender retweeted
🧬 Bad news for medical LLMs.
This paper finds that top medical AI models often match patterns instead of truly reasoning.
Small wording tweaks cut accuracy by up to 38% on validated questions.
The team took 100 MedQA questions, replaced the correct choice with None of the other answers, then kept the 68 items where a clinician confirmed that switch as correct.
If a model truly reasons, it should still reach the same clinical decision despite that label swap.
They asked each model to explain its steps before answering and compared accuracy on the original versus modified items.
All 6 models dropped on the NOTA set, the biggest hit was 38%, and even the reasoning models slipped.
That pattern points to shortcut learning, the systems latch onto answer templates rather than working through the clinical logic.
Overall, the results show that high benchmark scores can mask a robustness gap, because small format shifts expose shallow pattern use rather than clinical reasoning.

Jeff Brender retweeted
Kolmogorov–Arnold graph neural networks for molecular property prediction
Predicting molecular properties quickly and accurately is critical for drug discovery, materials science, and chemical engineering—but traditional deep learning approaches often face a trade-off between accuracy, efficiency, and interpretability. Graph neural networks (GNNs) have become a workhorse for modeling molecules as graphs of atoms and bonds, while Kolmogorov–Arnold networks (KANs) offer a mathematically grounded way to model complex functions with fewer parameters and greater interpretability.
Longlong Li and coauthors introduce KA-GNNs, a new framework that fully integrates KAN modules into all three core GNN components: node embedding, message passing, and readout. They develop a Fourier-series-based KAN that captures both low- and high-frequency patterns in molecular graphs, with strong theoretical guarantees of expressiveness. Tested on seven benchmark datasets from MoleculeNet, KA-GNN variants (KA-GCN and KA-GAT) consistently outperform state-of-the-art models—achieving higher accuracy, faster runtime, and improved ability to highlight chemically meaningful substructures.
By combining richer feature transformations, explicit modeling of covalent and non-covalent interactions, and interpretable predictions, KA-GNNs offer a powerful, generalizable tool for molecular property prediction. The approach could accelerate AI-driven drug discovery and materials design while providing domain experts with insights into the structural drivers of a molecule’s behavior.
Paper: nature.com/articles/s42256-0…

Jeff Brender retweeted

Are frontier AI models really capable of “PhD-level” reasoning? To answer this question, we introduce FormulaOne, a new reasoning benchmark of expert-level Dynamic Programming problems. We have curated a benchmark consisting of three tiers, in increasing complexity, which we call ‘shallow’, ‘deeper’, ‘deepest’.
The results are remarkable:
- On the ‘shallow’ tier, top models reach performance of 50%-70%, indicating that the models are familiar with the subject matter.
- On ‘deeper’, Grok 4, Gemini-Pro, o3-Pro, Opus-4 all solve at most 1/100 problems. GPT-5 Pro is significantly better, but still solves only 4/100 problems.
- On ‘deepest’, all models collapse to 0% success rate.
🧵

Jeff Brender retweeted

Accelerating Protein Design by Scaling Experimental Characterization
🚀 New preprint from David Baker!🚀
1. This preprint introduces a novel workflow called Semi-Automated Protein Production (SAPP) that significantly accelerates the experimental validation of de novo protein designs. SAPP enables rapid, modular, and cost-effective protein production and characterization, allowing for the purification and analysis of hundreds of protein designs per day.
2. The SAPP protocol leverages a standardized cloning approach and optimized purification pipeline to achieve at least a tenfold increase in throughput compared to traditional methods. It reduces the total hands-on time to just 6 hours for end-to-end execution, making it highly efficient for large-scale protein design campaigns.
3. A key innovation is the use of a background-suppressing cassette in the cloning process, which eliminates the need for colony isolation and sequencing, thus bypassing traditional multi-day cloning protocols. This approach ensures that the correct clone is the dominant construct in most cases, with a clonal purity of over 90% in many instances.
4. The authors also developed a scalable demultiplexing protocol (DMX) to further reduce costs. DMX converts DNA oligo pools into sequence-verified clonal constructs, enabling the purification and characterization of over 1000 designs at a cost of $5 per construct. This protocol integrates seamlessly with SAPP and is particularly useful for large design campaigns.
5. The SAPP and DMX protocols have been successfully applied to characterize tens of thousands of de novo designed proteins, including mini-protein binders, enzymes, and large protein assemblies. These workflows are designed to be widely adoptable, making large-scale experimental testing more accessible and affordable.
6. The integration of these protocols with computational protein design methods is expected to drive the development of new protein design models informed by experimental data. This could also enable active learning approaches, where experimental feedback is used to iteratively improve protein designs.
💻Code: github.com/bwicky/SAPP_DMX
📜Paper: biorxiv.org/content/10.1101/…
#ProteinDesign #ExperimentalValidation #SAPP #DMX #ComputationalBiology #HighThroughput #CostEffective #ActiveLearning

Jeff Brender retweeted

🧵1/ Antivaxxers love this chart.
It shows mortality from scarlet fever, whooping cough, measles, diphtheria & smallpox falling before vaccines were introduced.
Their claim? “Vaccines didn’t save us.”
Let’s break down why this argument is completely misleading.
📉⚠️


