Matini94 retweeted

FuseCon wasn’t just about Titan on stage.
We shared how 400+ AI agents support QA, security, privacy, and releases at Deriv.
AI-first means building and running the company with AI by default, while people focus on judgment and exceptions.
FuseCon highlights.
#FUSECON26 #AI


Matini94 retweeted

15 AI founders you should follow on Twitter:
@sama
= founded OpenAI
@AravSrinivas
= founded Perplexity AI
@karpathy
= ex-founding member at OpenAI
@darioamodei
= founded Anthropic
@demishassabis
= founded DeepMind
@hwchase17
= founded LangChain
@adcock_brett
= founded Figure AI
@AndrewYNg
= founded DeepLearning. AI
@jeremyphoward
= founded fast. ai
@DrJimFan
= leads AI robotics at NVIDIA
@natfriedman
= ex-CEO of GitHub
@swyx
= founded Smol AI
@ai_explorer25
= underrated ai creator
@levelsio
= founded PhotoAI
@fchollet
= founded Keras
@rasbt
= underrated ML educator
Matini94 retweeted

LisanBench results for GPT-5.5 - it's good.
GPT-5.5 is now the strongest model without Thinking on both metrics!
GPT-5.5-medium uses on average ~45.6% less tokens than GPT-5.4-medium while scoring 1.77x higher!
(1.14x higher score on the difficulty weighted metric)
Running LisanBench for GPT-5.5-medium cost basically the same as for GPT-5.4-medium despite being 2x more expensive.
GPT-5.5-medium has the highest validity ratio (% of legal and correct moves) out of all tested models.
In the overall GPT-5.5-medium is:
- Rank #4 by average path length: 9327
- Rank #3 by difficulty-weighted score: 2539
on the difficulty weighted metric:
- Opus 4.7-xhigh used +134.9% more tokens and scored +55.9% higher
- Opus 4.6-16k used +11.1% more tokens and scored 9.2% higher
- Sonnet 4.6-16k used +3.1% more tokens and scored -9.1% lower
Current Validity ratio leaderboard:
1. GPT 5.5 (medium): 99.44%
2. Opus 4.7 (xhigh): 99.35%
3. Sonnet 4.6 (16k): 99.28%
4. Opus 4.6 (16k): 98.74%
5. Gemini 3.1 Pro Preview (low): 97.77%
The "non-thinking" version of GPT-5.5 uses 3.3x more tokens than GPT-5.4 (non thinking), but gets a 3.1x higher avg score and 2.96x higher weighted score.

Matini94 retweeted
I was basically Claude-only for the last 6 months.
but GPT-5.5 pulled me back.
The research output is just better. It gives me exactly what I need, every time.
@sama and the OpenAI team really cooked.
GPT Image 2 is also absurdly good.
Matini94 retweeted

🚨 Anthropic's own team just showed how to actually use Claude Code properly.
30 minutes. free. the person who created Claude Code.
watch the workshop. bookmark it.
worth more than every $500 course you almost bought.
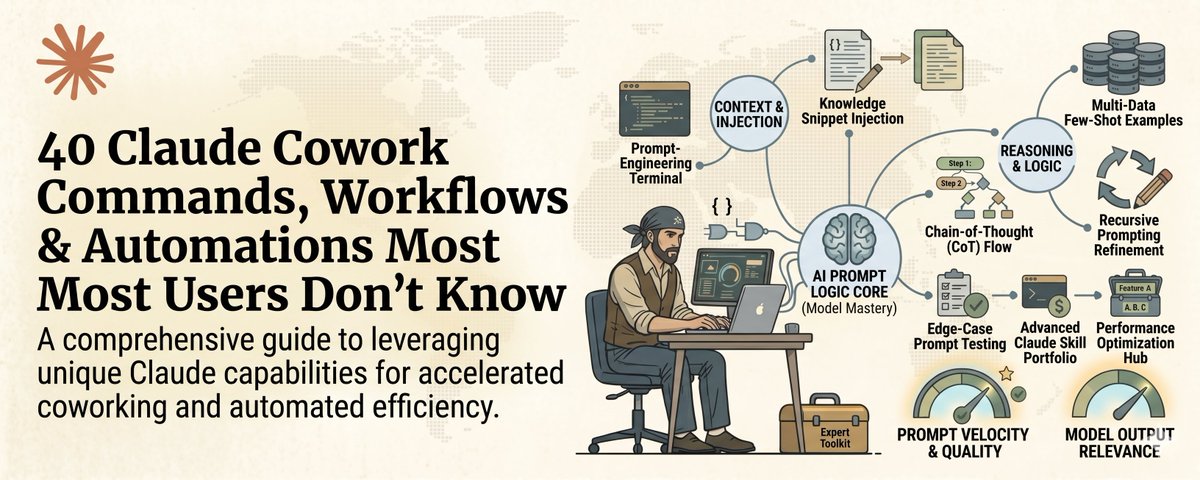
you've been using Claude without knowing 40 of its commands.
Then read the guide below.